How to Calculate Predictive Maintenance Software TCO Across Multi-Site Operations
Publication Date
author
Why does predictive maintenance software TCO become harder to see across multiple sites?
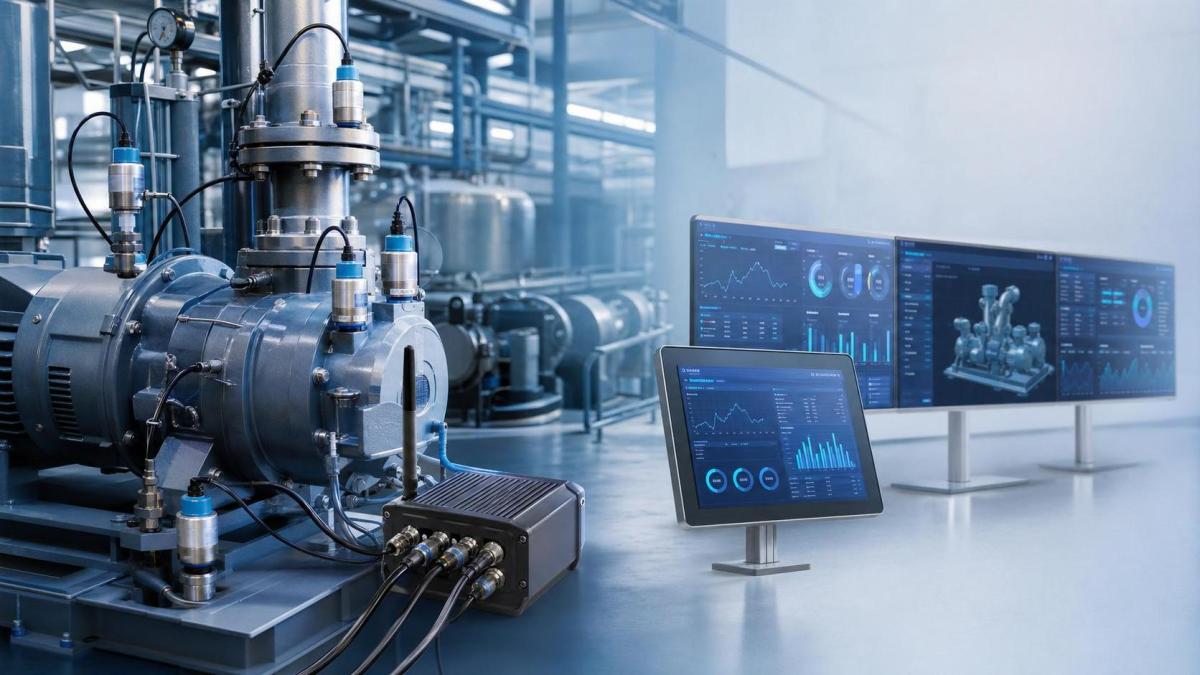
The short answer is scale changes the cost structure. A single plant can hide inefficiencies. A network of plants exposes them quickly.
When teams discuss predictive maintenance software TCO, they often start with subscription fees. That is necessary, but it is rarely enough for an approval decision.
In distributed operations, every site adds variation. Sensor fleets differ. PLC generations differ. Network policies differ. Maintenance maturity differs as well.
That means the true predictive maintenance software TCO includes technical onboarding, data cleaning, edge connectivity, user adoption, and governance over time.
A useful way to think about it is simple: software cost is only the visible layer. The larger spend usually sits in integration effort and operating discipline.
This matters in robotics, aerospace supply chains, precision machining, and sensor-heavy production lines, where downtime is expensive and tolerance failures travel downstream.
That is also why data-first organizations favor engineering evidence over vendor adjectives. The decision improves when cost assumptions are tied to measurable plant conditions.
What should be included in predictive maintenance software TCO, beyond the license line?
A complete model should separate acquisition costs from operating costs and risk-adjusted value. Without that split, comparisons become misleading.
Most multi-site evaluations should account for these cost blocks:
- Software subscription or perpetual license, including user tiers and data volume thresholds.
- Implementation services for site rollout, asset mapping, model setup, and workflow design.
- Integration with CMMS, ERP, SCADA, historians, MES, and edge gateways.
- Sensor upgrades where installed devices lack resolution, stability, or protocol compatibility.
- Cloud, storage, cybersecurity review, and network segmentation changes.
- Training time for maintenance planners, reliability engineers, and plant administrators.
- Ongoing model monitoring, false alert tuning, and governance across sites.
Many buyers miss the sensor and data layer. Predictive maintenance software TCO rises fast when vibration, thermal, or current data cannot support reliable inference.
Another hidden item is internal labor. Even with a strong vendor, subject matter experts must validate failure modes, critical assets, and alarm logic.
In practice, the most reliable forecasts use a three-year view. One year can understate stabilization costs. Five years can overstate uncertain savings assumptions.
A practical cost checklist
How do you calculate predictive maintenance software TCO in a way that stands up to review?
A defensible calculation starts with asset criticality, not with a vendor quote. Otherwise, the model remains commercial rather than operational.
Begin by grouping sites into rollout waves. Plants with similar machine families and data maturity should be modeled together.
Then define three numbers for each wave: total deployment cost, annual operating cost, and expected avoided loss.
Deployment cost usually includes implementation services, edge hardware, sensor retrofit, IT review, and internal project labor.
Annual operating cost should include license renewals, support, cloud usage, retraining, and site-level administration time.
Expected avoided loss needs stricter discipline. Use historical failure records, mean downtime cost, spare part exposure, and maintenance overtime.
In precision sectors, one avoided event may include scrap, missed delivery penalties, requalification time, and customer quality containment.
A practical formula is:
Predictive maintenance software TCO = deployment costs + three-year operating costs + upgrade allowances - measurable avoided losses.
The subtraction should stay conservative. Count only benefits that can be traced to specific assets, maintenance actions, and time windows.
That approach aligns with an engineering mindset often associated with TSV: parameters first, claims second, assumptions always visible.
Where do multi-site cost surprises usually come from?
Surprises rarely come from the headline quote. They come from heterogeneity between sites and from overconfidence in existing data readiness.
A common example is protocol fragmentation. One site may run modern OPC UA connectivity. Another may depend on aging gateways and manual exports.
Another issue is environmental stress. Sensors proven in clean assembly areas may fail early in high-vibration, high-temperature, or conductive dust environments.
Model portability also gets overstated. A bearing model tuned for one motor family may perform poorly on another with different loads and duty cycles.
More subtle costs appear in workflow friction. If alerts do not connect cleanly to work orders, teams end up running parallel manual processes.
Those manual bridges consume time and weaken trust. Eventually, predictive maintenance software TCO rises because adoption never reaches the intended level.
The safer assumption is that multi-site standardization takes longer than software demos suggest. Budgeting should reflect that reality upfront.
Warning signs worth testing early
- Savings claims are based on generic percentages rather than your asset history.
- The vendor cannot show alert precision across mixed machine populations.
- Site onboarding assumes identical naming, historian structure, and maintenance taxonomy.
- Cybersecurity scope is described vaguely or postponed until after selection.
- The proposal treats all downtime as equally costly, which is rarely true.
How can you compare vendors without reducing the decision to price alone?
Price matters, but predictive maintenance software TCO should be compared against evidence quality, rollout friction, and the probability of sustained use.
A lower quote can be more expensive if integration is custom-heavy or if false positives drive unnecessary inspections.
A better comparison method is to score vendors on operational fit and cost transparency at the same time.
This is where independent benchmarking matters. In hard-tech environments, broad claims are less useful than testable thresholds and site-specific operating evidence.
What is a realistic next step before budget approval?
The best next step is not a full rollout. It is a bounded cost model tied to a pilot wave with representative site variation.
Choose a limited asset set across two or three plants. Include one site with mature data and one with known integration complexity.
That structure reveals whether predictive maintenance software TCO will remain stable when conditions are less controlled.
Before approval, document five things clearly:
- Which assets are in scope, and why they are financially critical.
- What data already exists, and what must be upgraded.
- Which integration tasks belong to the vendor and which remain internal.
- What success means in measurable terms, such as avoided downtime hours.
- What assumptions will be revisited before phase two expansion.
A disciplined predictive maintenance software TCO review is less about producing a perfect number. It is about making every assumption visible and testable.
That is the practical standard worth following in any advanced industrial setting: fewer slogans, more traceable inputs, and decisions anchored in operational truth.
When the cost model is built that way, vendor comparison becomes clearer, rollout risk becomes smaller, and future expansion is easier to defend.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Oct 02, 2026How to Qualify Machined Parts Suppliers for Hard Tech ProgramsHard tech supply chain machined parts demand rigorous supplier qualification. Learn how to assess capability, traceability, quality controls, and delivery resilience.Dr. Marcus Vance
 Oct 01, 2026How to Select an Outdoor Security Radar Sensor for Perimeter Detection?Outdoor security radar sensor selection guide: compare range, accuracy, false-alarm control, integration, and field testing for reliable perimeter detection.TSV Data Lab
 Sep 30, 2026How to Evaluate Solid-State LiDAR Hardware for Outdoor Autonomous VehiclesSolid state LiDAR hardware evaluation guide for outdoor autonomous vehicles—compare range, point-cloud quality, environmental resilience, integration, and safety.TSV Data Lab
 Sep 29, 2026ISO 9283 Repeatability: How to Evaluate Cobot Positioning PerformanceISO 9283 cobot repeatability explained: learn how payload, reach, approach direction, and test conditions affect positioning performance and cell capability.Chen Wei (Automation Lead Engineer)
 Oct 02, 2026What Documents Prove a Precision Machining Supplier Can Hold Tolerance?What documents prove a precision machining supplier can hold tolerance? Explore certificates, FAI reports, calibration, SPC, and traceability evidence to qualify suppliers with confidence.Dr. Marcus Vance
 Oct 01, 2026Can a Machining Supplier Meet Aerospace Fatigue Testing Requirements?Can a machining supplier meet aerospace fatigue testing requirements? Learn the traceability, process control, and test evidence needed for reliable aerospace parts.Dr. Marcus Vance
 Sep 30, 2026Which Industrial Robot Specifications Matter for High-Precision Assembly?Which industrial robot specifications matter most for high-precision assembly? Explore repeatability, accuracy, stiffness, vibration, calibration, and force control for reliable yields.Chen Wei (Automation Lead Engineer)
 Sep 29, 2026How Do You Verify Servo Motor Torque Under Continuous Load?How do I verify servo motor torque under continuous load? Learn RMS torque checks, torque-speed limits, thermal derating, and real-machine testing.Chen Wei (Automation Lead Engineer)
 Oct 02, 2026ZD330 Software Configuration: Verifying Cut-List Import Before PurchaseZD330 software and machine configuration: verify cut-list imports, data mapping, labels, and workflow before purchase to reduce errors and choose with confidence.Victor Lin (Chief Software Architect)
 Sep 28, 2026Spindle Runout Measurement in Germany: DIN Standards, Methods, and Acceptance LimitsSpindle runout measurement Germany: explore DIN standards, proven methods, acceptance limits, and audit-ready practices for reliable machining quality.Dr. Marcus Vance
 Sep 27, 2026How to Select Wall-Mount Edge Devices for Space-Constrained Factory NetworksWall mount edge devices for space-constrained factories: evaluate workload, thermal design, power resilience, cable access, and network reliability for smarter deployments.TSV Data Lab
 Sep 26, 2026Machining Tolerance Analysis: How to Set Limits That Meet Function and Cost TargetsMachining tolerance analysis: learn how to set functional limits, control tolerance stacks, reduce inspection risk, and balance precision with production cost.Dr. Marcus Vance
 Sep 25, 2026How to Evaluate an Industrial Infrastructure Data Platform for Multi-Site OperationsIndustrial infrastructure data platform evaluation guide for multi-site operations: compare data quality, edge resilience, interoperability, governance, and scalable proof-of-value criteria.Victor Lin (Chief Software Architect)
 Sep 24, 2026How to Select Machine Vision Optics for Accurate Inspection at Different Working DistancesMachine vision optics selection guide for accurate inspection at every working distance. Compare FOV, pixel scale, DOF, distortion, lighting, and telecentric options.TSV Data Lab
 Sep 23, 2026How to Evaluate a Machine Vision System Integrator for High-Speed Inspection LinesChoose a machine vision system integrator with proven expertise in high-speed inspection, reliable reject timing, robust optics, and measurable acceptance criteria.TSV Data Lab
 Oct 02, 2026What affects the cost of a pick and place robot cell?Pick and place robot cost depends on throughput, tooling, vision, safety, and integration. Compare quotes confidently and avoid hidden automation costs.Chen Wei (Automation Lead Engineer)
 Oct 01, 2026What is included in a robotic system integration project cost?Robotic system integration project cost explained: compare equipment, engineering, safety, testing, installation, and lifecycle factors for smarter automation investments.Chen Wei (Automation Lead Engineer)