
How Can Industrial Edge Devices Reduce Data Loss to the Cloud?
Publication Date
author
Reducing data loss between industrial edge devices and the cloud starts with a practical shift in thinking: the network cannot be treated as permanently available, and the cloud cannot be treated as the first safe destination for every record. An industrial edge device should preserve, validate, and account for data locally before it attempts transmission.
This matters when a gateway is collecting PLC tags, machine-vision results, vibration readings, location data, or quality records that may later support production decisions and traceability. A short cellular interruption, overloaded Wi-Fi segment, broker restart, power event, or certificate failure can create a gap. If the device simply streams data and discards it after sending, that gap may be invisible until an engineer needs the missing history.
The reliable approach combines local store-and-forward buffering, delivery-aware messaging, resilient connectivity, clear data priorities, and evidence that the cloud received what the edge intended to send. More bandwidth can improve throughput, but it does not by itself prevent lost, duplicated, corrupted, or untraceable records.
Begin by defining what “data loss” means in the operation
Different industrial datasets tolerate different failure modes. A dashboard temperature point arriving a few minutes late is usually less serious than a missing reject decision from a vision station. A robot safety function should never depend on a cloud round trip at all; it needs deterministic local control. By contrast, cloud synchronization may be appropriate for event history, model updates, fleet reporting, and long-term analytics.
Before choosing a gateway, protocol, or cloud service, classify each data flow by four questions:
- What is the consequence if a record never arrives?
- How long may delivery be delayed before the information loses value?
- Can the receiving system safely process the same record twice?
- Must the data be retained for traceability, investigation, or process improvement?
These answers determine the architecture. High-frequency raw sensor streams may need local aggregation or event-based sampling. Alarm transitions, production counts, recipe changes, and inspection outcomes usually need durable event records. Images, point clouds, and other large files may require local staging with a separate upload and confirmation workflow, rather than being pushed through the same channel as small telemetry messages.
A common mistake is assigning the same delivery expectation to every tag. That creates either excessive storage and network costs or insufficient protection for the records that actually matter. Define criticality first, then design the handling path for each class.
Make the edge device the first durable system of record
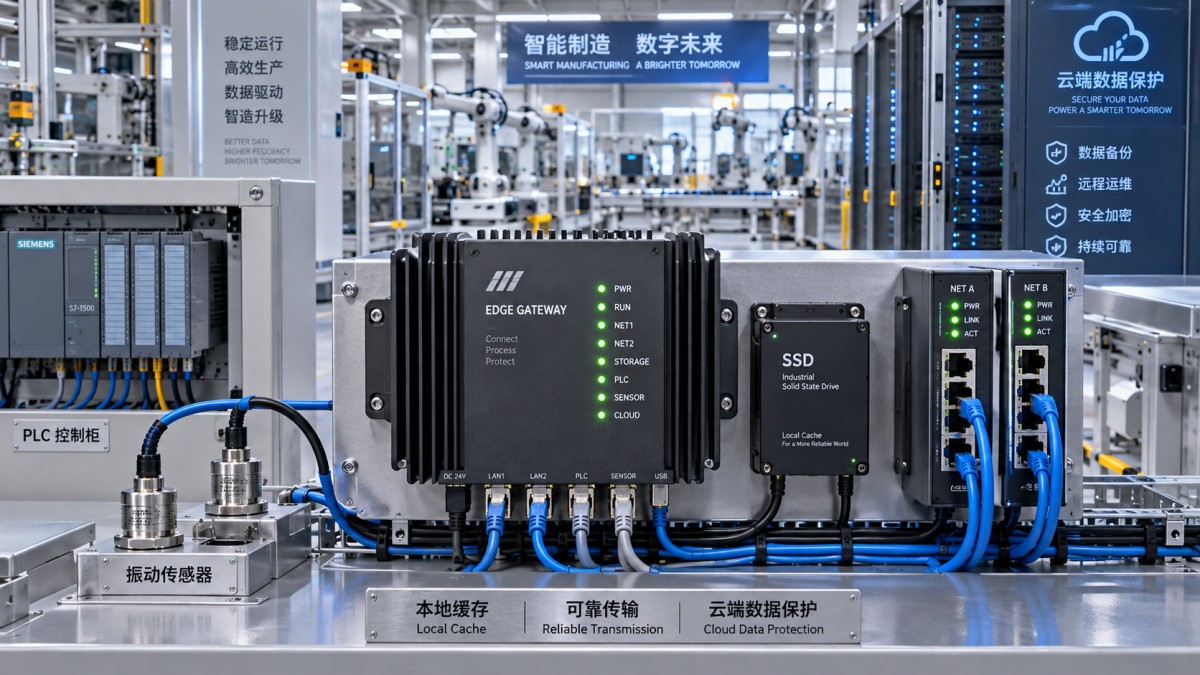
An edge gateway needs persistent local storage, not only memory queues. Memory buffers disappear when a process restarts, power drops, or the device is replaced. Persistent buffering writes outbound messages to a durable queue or local database before transmission. Once a connection returns, the gateway forwards the backlog in a controlled order and removes a record only after its delivery condition has been met.
That condition needs to be explicit. “Sent” may mean the device handed a packet to its network stack. It does not prove that a broker, ingestion service, or downstream application accepted and committed the event. For critical data, track at least three states: captured locally, acknowledged by the cloud endpoint, and processed by the target system. The exact implementation varies, but the distinction prevents a false sense of completeness.
Storage sizing should reflect the realistic outage window, data rate, payload size, and a reserve for retries. It should also account for bursts. A vision system may generate modest average traffic but create a large burst when defects trigger image retention. If a gateway reaches its storage limit, its behavior must be intentional: preserve critical records, reduce noncritical sampling, compress eligible payloads, or alert operators. Silent overwriting is rarely acceptable for traceability data.
Local storage also needs operational safeguards. Use storage designed for the device’s write pattern, monitor remaining capacity and write failures, and protect the queue from abrupt shutdowns. Where the process warrants it, a controlled shutdown path or backup power can give the gateway time to commit in-flight records. Redundancy is useful, but it does not replace a recoverable local journal.
Use delivery semantics that match the risk
Industrial protocols and cloud ingestion services differ in how they confirm delivery. The useful question is not which protocol is fashionable; it is what happens when a connection breaks at each point in the exchange.
At-least-once delivery is often a sensible target for industrial event data, but only when the cloud side is idempotent. In plain terms, processing the same event again should not create a second production count, second work order, or contradictory inspection result. Give each event a unique identifier generated at the source, such as a device identity paired with a sequence number or universally unique event ID. Retain that ID through brokers, transformations, and storage layers.
Sequence numbers add another benefit: they reveal gaps. A cloud service that sees records 701, 702, and 704 knows that 703 requires investigation, even if the network reported no obvious error. Use timestamps as well, but do not rely on time alone to prove ordering. Devices can reboot, clocks can drift, and an offline queue can legitimately send older records after newer ones.
For file-based data, a successful transfer should include integrity verification. A checksum or comparable content-validation method allows the receiver to confirm that the stored object is the same one the edge device prepared. This is especially important when transferring inspection images, LiDAR captures, firmware packages, or engineering files that cannot be meaningfully reconstructed from partial data.
Design for unreliable plant connectivity
Factory networks are difficult environments. Metal structures, moving equipment, electromagnetic interference, segmented networks, maintenance changes, and shared wireless capacity can all affect availability. A gateway that works in a clean lab network may behave very differently beside motors, weld cells, mobile equipment, or enclosed machinery.
Network resilience should be designed around recovery, not assumed uptime. The edge application should detect disconnects promptly, reconnect with controlled backoff, and preserve outbound data while it waits. Retry storms are a real risk: if hundreds of devices reconnect after an outage and retry at the same moment, they can overload the broker or gateway. Randomized retry intervals, queue rate limits, and reconnection throttling help the system recover without creating a second incident.
Where the business impact justifies it, provide an alternate path such as a second wired route or managed cellular connection. That choice is not automatically right for every device. Redundant access has value only if the gateway can detect a failed primary path, transition safely, and return without disrupting message order or exhausting the data plan. It must be tested under actual failure conditions rather than merely listed as a hardware feature.
Network segmentation also affects data availability. Security controls that block unapproved outbound sessions, DNS resolution, time synchronization, or certificate renewal can look like random data loss from the application’s perspective. The networking, OT, and cloud teams should agree on the required endpoints, ports, identity flow, and recovery behavior before deployment.
Do not let security controls become an unplanned failure source
Encryption, mutual authentication, and certificate-based identity protect industrial data in transit, but they introduce lifecycle requirements. An expired certificate can stop a previously healthy fleet from publishing. A device with an incorrect clock may reject a valid certificate. A credential rotation that is not synchronized with a disconnected gateway can leave it unable to reconnect.
Build credential renewal, clock health, and remote configuration validation into normal operations. The edge device should report certificate status before expiry becomes a service interruption, and it should retain enough local data to survive a planned maintenance window. Credentials should be unique per device or managed group so that replacing or revoking one device does not require a broad outage.
Security also protects data integrity. Restrict which devices can publish to which topics or endpoints, and validate payload structure at ingestion. A message that arrives successfully but is assigned to the wrong machine, parsed with the wrong unit, or accepted from an unauthorized source is an integrity failure, even though no packets were dropped.
Protect the data before it leaves the machine network
Cloud transmission cannot repair data that the gateway never captured correctly. Industrial edge devices should validate source quality at acquisition: communication status, sensor plausibility, tag type, scale, unit, and timestamp. When a PLC read fails, record it as a quality state rather than quietly reusing the last value. When a sensor reports outside its credible range, preserve the reading with an appropriate quality flag instead of silently normalizing it into a plausible value.
Time deserves particular attention. Distributed devices need a consistent time source and a defined policy for clock correction. If local time changes abruptly, event ordering and batch reconstruction can become confusing. Keeping both a source timestamp and a gateway receipt timestamp can help distinguish when an event occurred from when the system observed it.
For systems using local analytics or Edge AI, retain the decision context needed for later review. Sending only “pass” or “fail” may be sufficient for live control, but a traceability workflow may need the model version, configuration version, confidence state, source image reference, or ruleset that produced the decision. The aim is not to upload every raw signal indefinitely; it is to retain enough evidence to explain an important result.
Measure completeness, not just uptime
A connection-status indicator is useful, but it does not show whether records are complete. A device can appear online while its queue grows because cloud acknowledgements are failing, a downstream consumer is unavailable, or payloads are rejected.
Useful operational metrics include local queue depth and age, time since last confirmed cloud acknowledgement, retry count, storage capacity, rejected-message count, missing sequence ranges, clock synchronization status, and rate of duplicate events. Monitor these per device and in aggregate. A sudden increase in queue age may point to a network issue, while growing rejections may indicate a schema or authentication change.
Alert thresholds need to follow data criticality. A backlog of routine condition-monitoring telemetry may be tolerable for longer than a backlog of quality disposition events. Pair alerts with clear actions: inspect connectivity, pause lower-priority uploads, increase storage headroom, repair a certificate, or trigger a controlled backfill. An alert with no defined response simply moves uncertainty from the edge device to the operations team.
Test the failure paths before production depends on them
Reliability claims should be demonstrated through failure testing. Disconnect the network during active traffic. Restart the broker. Reboot the gateway with records in its queue. Fill local storage in a controlled environment. Introduce delayed acknowledgements and duplicate delivery. Validate that the cloud identifies missing sequence numbers, deduplicates retries where required, and preserves the original event context after recovery.
These tests often expose configuration problems that normal commissioning misses: queues kept only in memory, retry intervals that overwhelm an endpoint, retained messages mistaken for an audit trail, or cloud rules that discard an unfamiliar payload field. They also produce concrete acceptance criteria for procurement. Instead of asking whether an industrial gateway is “reliable,” ask how long it can buffer the required workload, how it persists unsent data, how acknowledgements are handled, how storage exhaustion is reported, and how device replacement preserves identity and traceability.
For engineering teams comparing edge gateways, brokers, and ingestion platforms, the most useful benchmarks are measurable ones: recovery behavior after an outage, queue persistence across restart, message ordering rules, duplicate handling, local storage health, and observability. That evidence-led approach aligns with TechStat Vanguard’s emphasis on engineering parameters over broad product claims.
The strongest data-loss strategy is therefore not a single feature. It is a chain of evidence from acquisition to cloud processing: capture the right record, store it durably, transmit it with an appropriate delivery contract, verify receipt, detect gaps, and prove recovery under failure. When each link has an owner and a measurable condition, cloud-connected industrial systems can remain trustworthy even when the network is not.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Oct 07, 2026How to Evaluate an HMI Panel Distributor for Industrial Automation ProjectsHMI panel distributor evaluation guide: verify technical compatibility, traceability, supply reliability, lifecycle support, and total cost for automation projects.Victor Lin (Chief Software Architect)
 Oct 06, 2026Navigation Fault Tolerance Standards for AMRs: What Safety Teams Must VerifyNavigation fault tolerance standards: learn what AMR safety teams must verify, from localization loss and sensor faults to stopping distance, safe restart, and site-specific validation.Chen Wei (Automation Lead Engineer)
 Oct 05, 2026Calculating Edge Computing Total Cost of Ownership Across Distributed SitesEdge computing ownership cost explained: calculate deployment, energy, connectivity, security, remote support, and refresh costs across distributed sites.TSV Data Lab
 Oct 04, 2026CAD/CAM Benchmarking in the GCC: What Manufacturers Should Ask a ConsultantCAD CAM benchmark consultant GCC guide: learn the key questions manufacturers should ask to validate post-processors, workflows, machine performance, and production risk.Victor Lin (Chief Software Architect)
 Oct 03, 2026Selecting Automotive Radar Sensor Modules for ADAS Range, Resolution, and IntegrationAutomotive radar sensor module selection guide for ADAS: compare range, resolution, field of view, latency, and integration to build safer, reliable vehicle systems.TSV Data Lab
 Oct 02, 2026How to Qualify Machined Parts Suppliers for Hard Tech ProgramsHard tech supply chain machined parts demand rigorous supplier qualification. Learn how to assess capability, traceability, quality controls, and delivery resilience.Dr. Marcus Vance
 Oct 01, 2026How to Select an Outdoor Security Radar Sensor for Perimeter Detection?Outdoor security radar sensor selection guide: compare range, accuracy, false-alarm control, integration, and field testing for reliable perimeter detection.TSV Data Lab
 Sep 30, 2026How to Evaluate Solid-State LiDAR Hardware for Outdoor Autonomous VehiclesSolid state LiDAR hardware evaluation guide for outdoor autonomous vehicles—compare range, point-cloud quality, environmental resilience, integration, and safety.TSV Data Lab
 Sep 29, 2026ISO 9283 Repeatability: How to Evaluate Cobot Positioning PerformanceISO 9283 cobot repeatability explained: learn how payload, reach, approach direction, and test conditions affect positioning performance and cell capability.Chen Wei (Automation Lead Engineer)
 Oct 06, 2026Are Collaborative Robots Safe Enough to Operate Without Fencing?Are collaborative robots safe enough to work without fencing? Explore risk assessment, safeguarding options, and practical guidance for safer, productive cobot cells.Chen Wei (Automation Lead Engineer)
 Oct 05, 2026What Causes Machine Vision Systems to Miss Small Defects?What causes machine vision systems to miss small defects? Discover how lighting, optics, motion, and AI thresholds affect detection—and prevent costly escapes.TSV Data Lab
 Oct 04, 2026How Should You Compare 5-Axis CNC Machine Accuracy Claims?How do I compare 5-axis CNC machine accuracy claims? Learn how to assess standards, thermal stability, TCP accuracy, and real-world test evidence.Dr. Marcus Vance
 Oct 03, 2026Is Edge Computing Necessary for Real-Time Quality Inspection?Is industrial edge computing necessary for real-time quality inspection? Explore how latency, data volume, reliability, and control integration shape the right architecture.TSV Data Lab
 Oct 02, 2026What Documents Prove a Precision Machining Supplier Can Hold Tolerance?What documents prove a precision machining supplier can hold tolerance? Explore certificates, FAI reports, calibration, SPC, and traceability evidence to qualify suppliers with confidence.Dr. Marcus Vance
 Oct 01, 2026Can a Machining Supplier Meet Aerospace Fatigue Testing Requirements?Can a machining supplier meet aerospace fatigue testing requirements? Learn the traceability, process control, and test evidence needed for reliable aerospace parts.Dr. Marcus Vance
 Sep 30, 2026Which Industrial Robot Specifications Matter for High-Precision Assembly?Which industrial robot specifications matter most for high-precision assembly? Explore repeatability, accuracy, stiffness, vibration, calibration, and force control for reliable yields.Chen Wei (Automation Lead Engineer)
 Sep 29, 2026How Do You Verify Servo Motor Torque Under Continuous Load?How do I verify servo motor torque under continuous load? Learn RMS torque checks, torque-speed limits, thermal derating, and real-machine testing.Chen Wei (Automation Lead Engineer)























