
How industrial IoT predictive maintenance solutions cut downtime
Publication Date
author
For enterprise decision-makers, unplanned downtime is not just a maintenance issue—it is a direct threat to output, margins, and supply chain resilience. Industrial IoT predictive maintenance solutions help manufacturers move beyond reactive repairs by turning real-time machine data into early warnings, measurable risk control, and smarter asset strategies. This article examines how data-driven maintenance reduces disruption and supports more reliable industrial operations.
What decision-makers are really searching for when evaluating predictive maintenance
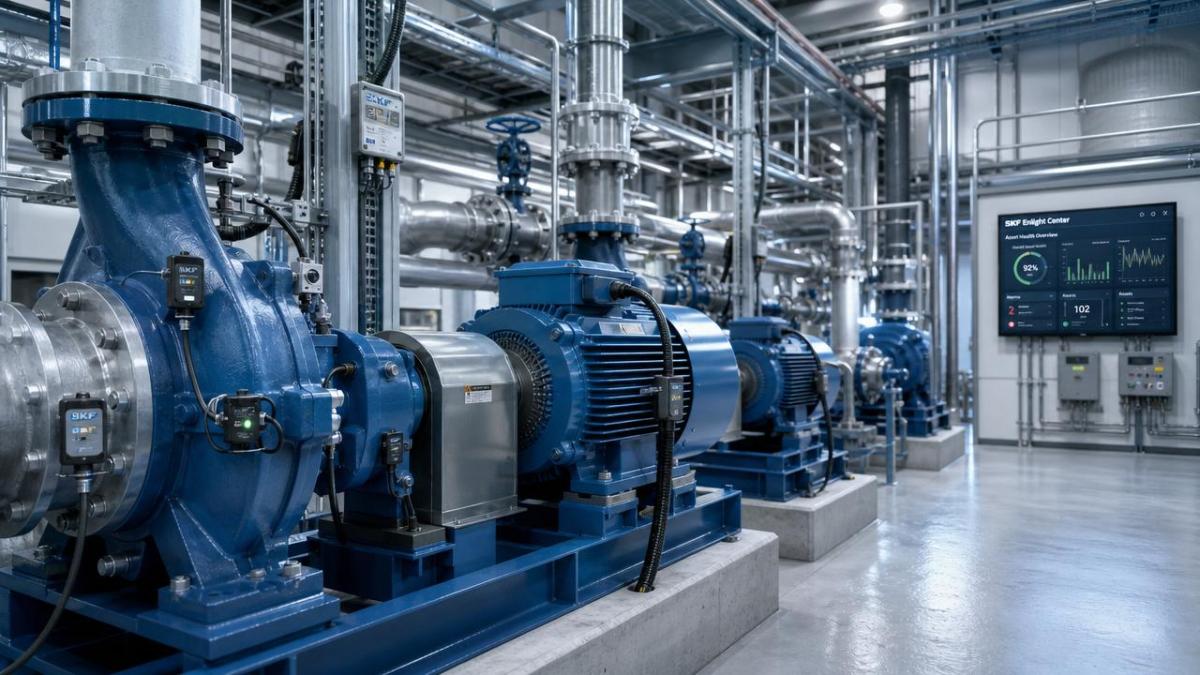
When leaders search for industrial IoT predictive maintenance solutions, they usually want one answer first: will this materially reduce downtime without creating another expensive digital project?
The core intent is practical, not academic. Buyers want to understand how predictive maintenance works in operating plants, where value appears first, and which assets justify investment.
They also want clarity on risk. Many manufacturers have already invested in sensors, MES, ERP, CMMS, or SCADA systems, yet still struggle with unexpected failures.
That is why the real question is broader than maintenance technology alone. It is whether machine data can become a reliable operational control layer.
For enterprise decision-makers, the most important issues are clear: measurable downtime reduction, realistic payback, deployment complexity, cybersecurity, integration effort, and organizational adoption across maintenance and operations teams.
Any useful discussion of industrial IoT predictive maintenance solutions should therefore focus less on buzzwords and more on business outcomes, asset prioritization, and implementation discipline.
Why unplanned downtime is so expensive beyond the maintenance budget
Unplanned downtime is rarely limited to the cost of replacing a failed motor, bearing, pump, or gearbox. Its full impact spreads through production, labor, logistics, and customer commitments.
A single line stoppage can disrupt upstream material flow, delay downstream finishing, force schedule changes, increase overtime, and reduce overall equipment effectiveness across multiple assets.
In industries with tight delivery windows, downtime also damages on-time performance and can trigger penalties, expediting costs, or lost future business from customers who prioritize supply certainty.
There is also the hidden cost of inefficient maintenance behavior. Reactive teams often overstock spares for fear of repeat failure, while preventive teams replace components too early just to stay safe.
Neither model is ideal. Reactive maintenance accepts disruption, while calendar-based maintenance can waste parts, labor, and machine availability without truly reducing risk.
Industrial IoT predictive maintenance solutions address this gap by using condition-based signals to identify deterioration before functional failure occurs, enabling intervention at a more economically rational moment.
How industrial IoT predictive maintenance solutions actually cut downtime
At a practical level, predictive maintenance reduces downtime by detecting early changes in machine condition that human inspection or routine time-based maintenance may miss.
These systems collect data from sensors and control systems, then analyze patterns linked to failure modes such as vibration imbalance, bearing wear, overheating, cavitation, pressure loss, or electrical anomalies.
Instead of waiting for a machine to fail, operators and maintenance teams receive earlier visibility into abnormal behavior, often days or weeks before breakdown becomes critical.
That time window matters. It allows teams to align repairs with planned production stops, reserve technicians, stage spare parts, and avoid emergency troubleshooting under pressure.
Downtime falls not only because failures are prevented, but because maintenance response becomes better organized. Planning quality improves when failure timing becomes more predictable.
Industrial IoT predictive maintenance solutions also improve root-cause analysis. Historical condition data helps engineers distinguish between isolated incidents and recurring patterns caused by load, environment, installation, or process instability.
Over time, the result is not just fewer stoppages. It is a more intelligent maintenance system where intervention is based on evidence, not assumptions.
Which assets typically deliver the fastest business value
Not every machine should be monitored first. The strongest predictive maintenance programs begin with assets where failure has a disproportionate operational or financial consequence.
For most manufacturers, this includes bottleneck equipment, high-speed rotating machinery, critical pumps, compressors, conveyors, chillers, furnaces, and specialized production systems with long repair cycles.
Decision-makers should prioritize assets using four filters: failure frequency, downtime cost, safety or quality impact, and the availability of meaningful condition signals.
An asset that fails rarely but stops an entire plant may deserve higher priority than a frequently repaired noncritical machine with easy redundancy.
The best early use cases are usually those with clear historical pain, measurable impact, and sufficient data to support a reliable detection model.
This is important because predictive maintenance value is rarely unlocked by deploying sensors everywhere at once. It comes from focusing first on the assets where insight converts into operational control.
What financial gains should enterprises realistically expect
Enterprise buyers often hear ambitious claims about AI, autonomous factories, or self-healing machines. Those promises are less useful than a grounded view of where value is typically created.
The first and most visible gain is reduced unplanned downtime. If critical assets fail less often, production continuity improves, schedule volatility declines, and labor disruption decreases.
The second gain is better maintenance efficiency. Teams spend less time firefighting and more time planning, diagnosing, and executing targeted interventions with the right parts and skills.
The third gain is longer asset life. Components are not run to catastrophic failure, but they are also not replaced prematurely under overly conservative preventive schedules.
Additional value may appear through lower spare-parts consumption, reduced scrap caused by unstable equipment, lower energy waste from degraded machines, and improved safety in high-risk environments.
For decision-makers, the most credible ROI models link predictive maintenance directly to production economics: avoided downtime hours, preserved throughput, maintenance labor optimization, and reduced secondary damage.
That framework is more reliable than headline ROI percentages because it reflects actual plant constraints, utilization rates, and margin sensitivity.
What data and infrastructure are needed for predictive maintenance to work
Successful industrial IoT predictive maintenance solutions do not always require a complete digital overhaul, but they do require dependable data and a sensible architecture.
Common inputs include vibration, temperature, current, voltage, acoustic signals, pressure, flow, lubricant condition, and event data from PLCs or existing control systems.
In many facilities, the challenge is not data scarcity but data fragmentation. Information may already exist across SCADA, historian, CMMS, and manual maintenance logs without a unified interpretation layer.
That is why edge connectivity and contextualization matter. Raw signals become useful only when mapped to asset identity, operating state, maintenance history, and production conditions.
Decision-makers should ask whether a solution can handle noisy industrial environments, varying machine duty cycles, and intermittent connectivity without degrading analytical reliability.
It is also essential to distinguish between simple threshold alerts and true predictive analytics. Thresholds identify obvious out-of-range conditions, while predictive models aim to detect evolving failure behavior earlier and more accurately.
How to judge vendors without getting lost in marketing language
Because this market is crowded, many platforms sound similar. The right evaluation approach is to examine engineering fit, workflow fit, and evidence of measurable operational outcomes.
Start with detection credibility. Which failure modes can the system identify? Under what operating conditions? How often does it generate false positives or miss actual issues?
Next, assess integration depth. Can the platform connect with your existing sensor stack, historians, CMMS, ERP, and maintenance workflows without creating heavy manual work?
Then examine usability. Maintenance teams do not need attractive dashboards alone; they need alerts that are interpretable, actionable, and prioritized by operational consequence.
Decision-makers should also ask how the vendor supports model tuning, onboarding, cybersecurity controls, edge deployment, and multi-site standardization.
Most importantly, request proof based on comparable assets or industries. In hard-tech operations, parameters matter more than slogans. A vendor should explain where its predictions are accurate and where uncertainty remains.
Common implementation mistakes that limit results
Many predictive maintenance initiatives underperform not because the concept is weak, but because execution is disconnected from operational reality.
A frequent mistake is starting with too many assets. Broad deployments create data volume, but not necessarily value. Teams become overloaded before they establish repeatable response workflows.
Another mistake is treating predictive maintenance as an IT project rather than a reliability program. Without maintenance ownership and operations alignment, alerts often fail to trigger timely action.
Some companies also underestimate data quality issues. Poor sensor placement, incomplete maintenance records, and missing context can reduce model confidence and user trust.
There is also the problem of unclear success metrics. If leadership cannot track avoided failures, downtime reduction, maintenance response time, and economic impact, support will weaken.
The most effective programs begin with a narrow scope, a defined asset class, baseline failure data, and explicit decision rules for what happens when the system detects risk.
How enterprise leaders should build the business case
For enterprise decision-makers, the business case should begin with economics, not technology. The first step is quantifying the cost of downtime on the most critical assets.
That includes lost production, margin impact, labor disruption, schedule recovery cost, spare-parts usage, quality losses, and any customer-service penalties linked to missed output.
Next, estimate what portion of those failures are detectable in advance through condition data. Not all failures are predictable, so realistic assumptions matter.
Then calculate the cost of deployment, including sensors, connectivity, software, integration, training, change management, and internal engineering support.
A strong business case compares current reactive and preventive costs against a future-state model where a defined percentage of failures are avoided or managed during planned downtime windows.
Leaders should also include strategic benefits that are harder to price but still important: better plant resilience, improved maintenance planning, lower operational uncertainty, and more consistent delivery performance.
Where predictive maintenance fits in a broader operating model
Predictive maintenance is most powerful when it is not isolated from the rest of industrial decision-making. It should connect with reliability engineering, production planning, and capital allocation.
When machine health signals are trusted, production teams can schedule around risk more intelligently. Procurement can stock critical parts more precisely. Engineering can address recurring design or process weaknesses.
Over time, industrial IoT predictive maintenance solutions can support a more mature asset strategy by revealing which machines deserve refurbishment, redesign, replacement, or tighter process control.
For multi-site enterprises, this creates an additional advantage: standardized condition monitoring across plants, with comparable risk visibility and shared failure learning.
In that sense, predictive maintenance is not only a maintenance upgrade. It becomes a practical foundation for more data-driven operations, where asset reliability is managed as a business variable.
Conclusion: downtime reduction depends on disciplined use of machine data
Industrial IoT predictive maintenance solutions cut downtime when they are applied to the right assets, supported by reliable data, and embedded into real maintenance decisions.
For enterprise leaders, the value is not in adopting another digital platform for its own sake. The value is in converting hidden machine deterioration into actionable lead time.
That lead time protects output, reduces disruption, improves maintenance efficiency, and strengthens supply reliability in environments where every unplanned stop carries financial consequences.
The clearest path forward is to start with high-impact assets, define measurable outcomes, and evaluate solutions using engineering evidence rather than broad marketing claims.
When executed with that discipline, predictive maintenance becomes more than a technology initiative. It becomes a direct lever for operational resilience, cost control, and smarter industrial asset management.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Oct 07, 2026How to Evaluate an HMI Panel Distributor for Industrial Automation ProjectsHMI panel distributor evaluation guide: verify technical compatibility, traceability, supply reliability, lifecycle support, and total cost for automation projects.Victor Lin (Chief Software Architect)
 Oct 06, 2026Navigation Fault Tolerance Standards for AMRs: What Safety Teams Must VerifyNavigation fault tolerance standards: learn what AMR safety teams must verify, from localization loss and sensor faults to stopping distance, safe restart, and site-specific validation.Chen Wei (Automation Lead Engineer)
 Oct 05, 2026Calculating Edge Computing Total Cost of Ownership Across Distributed SitesEdge computing ownership cost explained: calculate deployment, energy, connectivity, security, remote support, and refresh costs across distributed sites.TSV Data Lab
 Oct 04, 2026CAD/CAM Benchmarking in the GCC: What Manufacturers Should Ask a ConsultantCAD CAM benchmark consultant GCC guide: learn the key questions manufacturers should ask to validate post-processors, workflows, machine performance, and production risk.Victor Lin (Chief Software Architect)
 Oct 03, 2026Selecting Automotive Radar Sensor Modules for ADAS Range, Resolution, and IntegrationAutomotive radar sensor module selection guide for ADAS: compare range, resolution, field of view, latency, and integration to build safer, reliable vehicle systems.TSV Data Lab
 Oct 02, 2026How to Qualify Machined Parts Suppliers for Hard Tech ProgramsHard tech supply chain machined parts demand rigorous supplier qualification. Learn how to assess capability, traceability, quality controls, and delivery resilience.Dr. Marcus Vance
 Oct 01, 2026How to Select an Outdoor Security Radar Sensor for Perimeter Detection?Outdoor security radar sensor selection guide: compare range, accuracy, false-alarm control, integration, and field testing for reliable perimeter detection.TSV Data Lab
 Sep 30, 2026How to Evaluate Solid-State LiDAR Hardware for Outdoor Autonomous VehiclesSolid state LiDAR hardware evaluation guide for outdoor autonomous vehicles—compare range, point-cloud quality, environmental resilience, integration, and safety.TSV Data Lab
 Sep 29, 2026ISO 9283 Repeatability: How to Evaluate Cobot Positioning PerformanceISO 9283 cobot repeatability explained: learn how payload, reach, approach direction, and test conditions affect positioning performance and cell capability.Chen Wei (Automation Lead Engineer)
 Oct 06, 2026Are Collaborative Robots Safe Enough to Operate Without Fencing?Are collaborative robots safe enough to work without fencing? Explore risk assessment, safeguarding options, and practical guidance for safer, productive cobot cells.Chen Wei (Automation Lead Engineer)
 Oct 05, 2026What Causes Machine Vision Systems to Miss Small Defects?What causes machine vision systems to miss small defects? Discover how lighting, optics, motion, and AI thresholds affect detection—and prevent costly escapes.TSV Data Lab
 Oct 04, 2026How Should You Compare 5-Axis CNC Machine Accuracy Claims?How do I compare 5-axis CNC machine accuracy claims? Learn how to assess standards, thermal stability, TCP accuracy, and real-world test evidence.Dr. Marcus Vance
 Oct 03, 2026Is Edge Computing Necessary for Real-Time Quality Inspection?Is industrial edge computing necessary for real-time quality inspection? Explore how latency, data volume, reliability, and control integration shape the right architecture.TSV Data Lab
 Oct 02, 2026What Documents Prove a Precision Machining Supplier Can Hold Tolerance?What documents prove a precision machining supplier can hold tolerance? Explore certificates, FAI reports, calibration, SPC, and traceability evidence to qualify suppliers with confidence.Dr. Marcus Vance
 Oct 01, 2026Can a Machining Supplier Meet Aerospace Fatigue Testing Requirements?Can a machining supplier meet aerospace fatigue testing requirements? Learn the traceability, process control, and test evidence needed for reliable aerospace parts.Dr. Marcus Vance
 Sep 30, 2026Which Industrial Robot Specifications Matter for High-Precision Assembly?Which industrial robot specifications matter most for high-precision assembly? Explore repeatability, accuracy, stiffness, vibration, calibration, and force control for reliable yields.Chen Wei (Automation Lead Engineer)
 Sep 29, 2026How Do You Verify Servo Motor Torque Under Continuous Load?How do I verify servo motor torque under continuous load? Learn RMS torque checks, torque-speed limits, thermal derating, and real-machine testing.Chen Wei (Automation Lead Engineer)























