How to Evaluate Predictive Maintenance Software With SCADA Integration for Existing Plants
Publication Date
author
Choosing predictive maintenance software with SCADA integration for existing plants is less about software fashion and more about operational truth. In brownfield environments, every claim must be tested against legacy controls, asset criticality, cybersecurity boundaries, and measurable uptime impact. The strongest evaluation process starts where TechStat Vanguard places its emphasis: parameters, interfaces, tolerances, and the real behavior of data under plant conditions.
Why this evaluation matters now
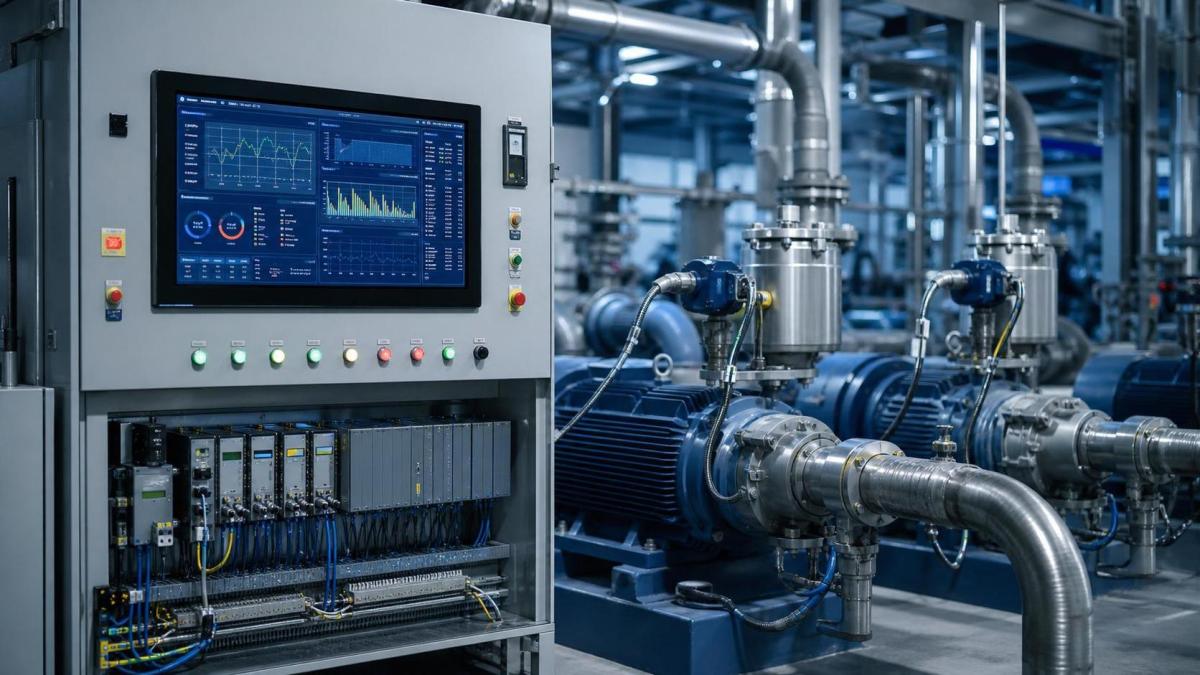
Many industrial sites are running assets that were never designed for modern analytics stacks. PLC generations vary, historian quality differs by line, and SCADA naming conventions may reflect years of local modifications.
At the same time, shutdown costs are rising. So are expectations around ESG reporting, energy efficiency, spare-parts planning, and resilience across distributed operations.
That is why predictive maintenance software with SCADA integration has moved from a pilot topic to a board-level reliability question. It touches production continuity, maintenance labor, compliance traceability, and capital allocation.
The market, however, is crowded with broad promises. TSV’s data-driven mindset is useful here: ignore slogans, inspect the engineering path from raw signal to trusted maintenance action.
What predictive maintenance software with SCADA integration actually means
In practical terms, predictive maintenance software with SCADA integration connects machine and process data already visible in plant supervision systems to condition models, anomaly detection, and maintenance workflows.
That sounds simple, but the value depends on three layers working together.
The signal layer
This includes vibration, temperature, pressure, current, cycle counts, alarms, and contextual process variables. If the signal is noisy, slow, missing, or poorly timestamped, prediction quality collapses quickly.
The interpretation layer
This is where the software turns historical patterns into condition indicators, fault signatures, and remaining useful life estimates. Good platforms explain why a model is flagging risk.
The action layer
Output must support maintenance scheduling, work-order prioritization, and root-cause review. If alerts stay trapped in dashboards, the plant has observation, not predictive maintenance.
Where existing plants usually face friction
Brownfield sites rarely fail because the concept is wrong. They struggle because integration assumptions are wrong.
In other words, evaluating predictive maintenance software with SCADA integration requires more than checking connector lists. It requires tracing how real plant data becomes a maintainable decision system.
The evaluation criteria that deserve the closest scrutiny
The most reliable assessments usually center on a few measurable dimensions rather than feature catalogs.
Interoperability under plant constraints
Ask which SCADA systems, historians, OPC standards, and edge gateways are proven in live deployments, not just supported on paper. Request examples involving similar asset age and control complexity.
Data fidelity and timestamp discipline
Prediction quality depends on clean chronology. Review sampling rates, buffering behavior, resynchronization methods, and how the platform handles missing values, manual entries, and out-of-range events.
Model transparency
Black-box scoring may look impressive during demonstrations. In operations, maintenance teams need interpretable drivers, threshold logic, confidence levels, and a defensible audit trail.
Deployment architecture
Cloud, on-premise, or hybrid choices should reflect OT policy, latency needs, and data residency rules. The right architecture is the one the plant can operate securely for years.
Lifecycle economics
Look beyond license price. Include sensor retrofits, tag engineering, historian cleanup, cybersecurity review, model tuning, user training, and the cost of scaling from one line to many.
How business value should be framed
The most useful business case is not a generic promise of fewer failures. It is a site-specific map of avoided loss and improved planning.
- Critical rotating assets may justify investment through avoided unplanned outages.
- Process lines with expensive changeovers may gain more from earlier fault isolation.
- Utility systems may benefit through energy anomaly detection and load stability.
- Multi-site groups often value standardized asset visibility and benchmarking.
This is where TSV’s philosophy becomes practical. Engineering truth means tying software claims to plant-level metrics such as false-positive rate, detection lead time, maintenance compliance, and downtime cost per event.
A sensible approach to pilots and comparisons
A disciplined pilot is usually the fastest way to evaluate predictive maintenance software with SCADA integration. The pilot should be narrow enough to control variables, but broad enough to test workflow impact.
Start with one failure mode, not every asset
Choose assets with known downtime consequences and accessible data. Pumps, compressors, conveyors, and spindle-driven equipment are common entry points.
Define success before data ingestion
Agree on metrics such as detection lead time, alert precision, operator response time, and maintenance action closure. Without this, pilots drift into presentation exercises.
Stress-test edge cases
Review startup conditions, planned shutdowns, recipe changes, maintenance overrides, and sensor loss. Real plants do not operate in ideal laboratory cycles.
Questions that separate substance from marketing
During vendor review, a few direct questions can expose whether the platform is ready for existing plants.
- Which SCADA environments are already deployed in sites with similar control maturity?
- How is data quality scored before models are trained or alerts are issued?
- What happens when tag naming is inconsistent across lines or sites?
- Can the platform explain why a recommendation was generated?
- How are cybersecurity updates handled inside OT approval processes?
- What resources are required to scale from pilot to enterprise rollout?
These questions keep attention on implementation physics rather than interface polish.
Moving from evaluation to a defensible decision
The best choice is usually the platform that fits existing plant reality with the least distortion. That means reliable SCADA interoperability, transparent analytics, manageable security design, and measurable operational payoff.
For organizations comparing predictive maintenance software with SCADA integration, the next step is not a broad request for slogans. It is a structured shortlist built around asset criticality, data readiness, integration burden, and pilot success criteria.
A useful internal review often starts with three documents: a plant data map, a ranked asset risk list, and a validation scorecard for vendors. Once those exist, comparison becomes clearer, faster, and less vulnerable to information noise.
That is the point of evaluating with rigor. In hard-tech operations, maintenance intelligence only matters when data can be trusted, actions can be justified, and uptime gains can be proven.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Sep 23, 2026How to Evaluate a Machine Vision System Integrator for High-Speed Inspection LinesChoose a machine vision system integrator with proven expertise in high-speed inspection, reliable reject timing, robust optics, and measurable acceptance criteria.TSV Data Lab
 Sep 23, 2026What drives ultra-precision machining cost at 1-micron tolerance?Ultra precision machining cost per part at 1 micron tolerance depends on process, material, metrology, and yield. Learn how to compare quotes confidently.Dr. Marcus Vance
 Sep 22, 2026Drone Engine-T550CC Applications: Build the UAV Power System Around the MissionAn application guide for Drone Engine-T550CC integration, covering payload planning, airframe matching, cooling, fuel, vibration, test procedures, documentation, and service preparation.Elena Rostova (UAV Systems Researcher)
 Sep 22, 2026How to Evaluate Industrial Edge Computing Vendors for Factory DeploymentIndustrial edge computing vendor evaluation guide for factories: compare latency, protocol fit, reliability, security, and lifecycle support before deployment.TSV Data Lab
 Sep 21, 2026Drone Payload Integration: Matching Power, Data, and Center of Gravity for Reliable FlightsDrone payload integration made practical: balance power, data, center of gravity, and endurance to build safer, more reliable mission-ready flights.Elena Rostova (UAV Systems Researcher)
 Sep 20, 2026Autonomous Navigation Pricing: Cost Drivers and Budget Benchmarks for AMR ProjectsAutonomous navigation price explained: compare AMR cost drivers, software, sensors, integration, safety, and lifecycle budgets to build a scalable project plan.Chen Wei (Automation Lead Engineer)
 Sep 19, 2026How to Scope Automation Integration Services for Multi-System Factory ProjectsAutomation integration services: learn how to scope multi-system factory projects with clear workflows, interface contracts, safety boundaries, and acceptance criteria.Victor Lin (Chief Software Architect)
 Sep 18, 2026Selecting UAV Aerospace Structural Parts for Strength, Weight, and Fatigue LifeUAV aerospace structural parts guide: compare strength, weight, stiffness, fatigue life, joints, and traceability to select reliable flight-ready components.Elena Rostova (UAV Systems Researcher)
 Sep 17, 2026Selecting Commercial Drone Payloads for European Inspection ProjectsCommercial drone payloads Europe: learn how to select RGB, thermal and LiDAR systems for compliant, reliable inspection data and better project outcomes.Elena Rostova (UAV Systems Researcher)
 Sep 16, 2026Machining Tolerance Validation: How to Verify Critical Dimensions Before Production ReleaseMachining tolerance analysis validation: verify critical dimensions, measurement systems, process capability, and tolerance stacks before production release.Dr. Marcus Vance
 Sep 15, 2026AGV Tape Guidance vs Laser Navigation: Which Fits Your Warehouse Layout?AGV tape guidance comparison: discover how tape and laser navigation fit changing warehouse layouts, docking needs, floor conditions, maintenance, and route flexibility.Chen Wei (Automation Lead Engineer)
 Sep 14, 2026How Point Cloud Analytics Improves Asset Inspection Workflows Across GCC ProjectsPoint cloud analytics GCC helps project leaders improve asset inspections with accurate change detection, safer workflows, and faster maintenance decisions.TSV Data Lab
 Sep 13, 2026How Aerospace Manufacturers Can Build a Digital Thread From Design to Certified ProductionDigital manufacturing for aerospace: learn how to build a traceable digital thread from design through certified production, supplier control, and audit-ready compliance.Victor Lin (Chief Software Architect)
 Sep 12, 2026How to Select a Thermal Sensor for Mapping Drones in Surveying ProjectsMapping drone thermal sensor selection made simple: compare GSD, radiometric data, NETD, calibration, and workflow fit for accurate, survey-ready thermal maps.Elena Rostova (UAV Systems Researcher)
 Sep 11, 2026Integrating Photogrammetry Workflows into Digital Twin Projects Without Data BottlenecksPhotogrammetry workflow integration for digital twins: learn how to streamline capture, validation, versioning, and delivery to prevent data bottlenecks.Victor Lin (Chief Software Architect)
 Sep 10, 2026Hard-Tech Supply Chain Procurement: Qualifying Suppliers to Cut Lead-Time RiskHard-tech supply chain procurement guide: qualify suppliers with proven process, traceability, capacity, and change control to reduce lead-time risk.Chen Wei (Automation Lead Engineer)
 Sep 09, 2026Industrial Application Notes: Cost Factors That Shape Automation Project BudgetsIndustrial application notes cost factors explained: uncover the engineering, safety, integration, and commissioning variables that shape accurate automation budgets.Victor Lin (Chief Software Architect)