
When MES API Integration Latency Starts Hurting Throughput
Publication Date
author
When mes system api integration latency begins to slow data exchange between shop-floor systems and decision layers, throughput losses rarely stay isolated for long.
For enterprise leaders navigating advanced manufacturing, even small delays can distort scheduling, reduce equipment utilization, and weaken supply chain responsiveness.
This article examines how latency turns from a technical nuisance into an operational risk—and what data-driven teams should measure first.
Why MES API latency becomes a throughput problem sooner than leaders expect
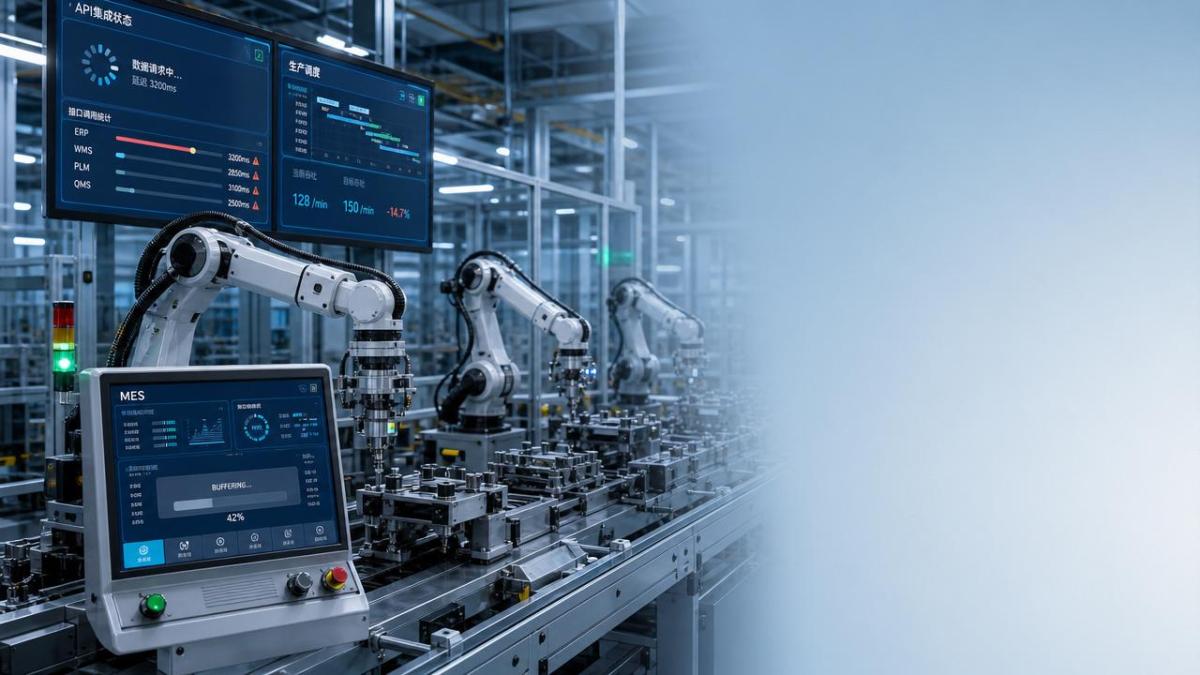
The core search intent behind mes system api integration latency is practical, not academic. Decision-makers want to know when integration delay starts affecting output, cost, and planning accuracy.
They are usually not asking whether latency exists. They are asking how much latency is tolerable, where it shows up first, and whether the issue justifies operational or architectural intervention.
For enterprise readers, the key judgment is simple. Latency becomes dangerous when it breaks the timing assumptions behind scheduling, traceability, machine coordination, or exception handling.
At that point, the MES is no longer acting as a reliable execution layer. It becomes a delayed mirror of production reality, and throughput decisions start relying on stale information.
This is why latency should not be framed only as an IT performance metric. In advanced manufacturing, it is an operational timing issue with direct consequences for cycle time and output stability.
What enterprise decision-makers usually care about most
Senior leaders rarely care about raw milliseconds in isolation. They care about missed production targets, underused assets, rising work in progress, and slower response to disruptions.
In practice, the most important questions tend to be business-facing. Is throughput being constrained, is quality risk increasing, and is the integration architecture still fit for scale?
They also want to understand the cost of inaction. If latency remains unresolved, will the business face more expediting, more manual overrides, more inventory buffers, or weaker customer delivery performance?
Another common concern is visibility. Many organizations suspect data delay, but they lack a clean method to connect API timing issues with measurable production losses.
That gap matters because budget approvals depend on evidence. A technical team may report sluggish interfaces, but leadership needs a quantified link to revenue, utilization, or supply chain reliability.
How latency actually reduces throughput on the shop floor
Throughput loss usually appears through compounding micro-delays rather than one dramatic failure. MES APIs that lag by seconds can still damage performance if decisions depend on near-real-time feedback.
One common pattern is delayed production state updates. If machine status, completion signals, or material consumption events arrive late, dispatching logic starts acting on outdated conditions.
The result is avoidable idle time. A downstream process may wait for confirmation that already happened, while planners and supervisors see an execution picture that trails actual production.
Another pattern is slower exception handling. If alarms, quality holds, or maintenance triggers reach the MES late, escalation starts later and the recovery window becomes more expensive.
Latency also affects synchronization across systems. MES often sits between ERP, SCADA, historians, WMS, quality systems, and edge devices. Delay at one API boundary propagates into the broader workflow.
In highly automated environments, this matters even more. Small integration lags can disrupt recipe validation, lot genealogy, operator instructions, or machine-to-machine handoff timing.
Even where physical automation is limited, latency still hurts labor efficiency. Operators spend more time checking status manually, supervisors override system recommendations, and planners pad schedules defensively.
When mes system api integration latency crosses from nuisance to operational risk
Not every delay is equally harmful. The real threshold depends on process tempo, batch size, product mix, and how tightly execution decisions depend on live system feedback.
In a low-mix environment with long production runs, moderate latency may be tolerable for some reporting interfaces. In a high-mix or regulated environment, the tolerance is much lower.
Latency becomes an operational risk when it changes decisions, not just dashboards. If delayed data causes the wrong job sequence, delayed replenishment, missed traceability events, or slower release decisions, the risk is already real.
A useful leadership test is this: if the API delay disappeared tomorrow, would output, responsiveness, or labor coordination improve in a measurable way? If yes, the issue deserves priority.
Another threshold appears when teams create workarounds. Manual logging, local spreadsheets, delayed confirmations, and phone-based status checks are signs that the system timing model no longer matches operations.
Those workarounds may keep production moving temporarily, but they reduce data integrity and make scaling much harder. They are often the visible symptom of deeper integration timing problems.
What to measure first before approving a fix
Leaders need more than average API response time. Mean values often hide the spikes that cause the most disruption in production environments.
Start with end-to-end event latency. Measure how long it takes for a real production event to be captured, transmitted, processed, and made actionable in the receiving system.
Then compare that timing against process-critical windows. A two-second delay may be irrelevant for weekly reporting but unacceptable for machine dispatch, interlock confirmation, or automated material flow.
Track p95 and p99 latency, not just averages. Throughput damage often comes from intermittent delays, queue buildup, or burst traffic under peak production conditions.
Also measure event freshness at the point of decision. What matters is not only how fast an API responds, but whether the consuming process is acting on current data.
Queue depth, retry rates, timeout frequency, and duplicate event handling are also important. These metrics often reveal whether the issue is network-related, architectural, or tied to application logic.
Most importantly, correlate latency with business metrics. Compare delayed intervals with OEE loss, line stoppages, schedule adherence, WIP growth, and order completion variance.
Where the root causes usually sit
MES integration latency is rarely caused by one factor alone. In most plants, the problem emerges from combined friction across applications, infrastructure, and process design.
Legacy middleware is a common source. Older polling-based integrations, batch synchronization jobs, and monolithic connectors often cannot support the timing needs of modern execution environments.
Another root cause is architectural mismatch. Many MES landscapes were designed for visibility and recordkeeping first, then later stretched into near-real-time orchestration roles.
API design quality also matters. Excessive payload size, chatty request patterns, poor pagination, synchronous dependencies, and weak error handling all increase timing instability.
Infrastructure bottlenecks remain important too. Network congestion, underprovisioned gateways, overloaded application servers, and database contention can all contribute to inconsistent performance.
There is also a governance dimension. If ownership is split across OT, IT, vendors, and site teams without shared service-level expectations, latency issues persist because nobody manages the full chain.
How to evaluate whether the fix is worth the investment
For executives, the investment case should be framed around throughput recovery, planning confidence, labor efficiency, and resilience—not simply faster APIs.
Estimate the cost of delay using operational evidence. Quantify lost productive minutes, additional expediting, inventory buffering, manual intervention hours, and quality or traceability risk exposure.
Then compare that against the likely remediation path. In some cases, tuning interfaces and redesigning event flows may be enough. In others, the business may need middleware modernization or MES integration re-architecture.
Payback is often stronger in facilities with high product variability, tight takt windows, regulated traceability, or strong dependence on coordinated automation.
It is also worth evaluating strategic upside. Lower latency can improve future readiness for edge analytics, closed-loop process control, autonomous intralogistics, and multi-site performance benchmarking.
That broader view matters because a latency fix may not only recover current throughput. It may also remove a structural barrier to scaling digital operations across plants.
What a sound executive response looks like
A strong response begins with classification. Separate reporting latency from execution-critical latency so the organization does not waste effort solving the wrong problem first.
Next, identify the workflows where stale data changes actions. These are usually scheduling updates, quality release steps, machine state transitions, material movement confirmations, and exception escalation paths.
Require a time-based map of the current integration chain. Leaders should be able to see where delays occur across device, gateway, middleware, MES, and downstream applications.
From there, prioritize fixes by operational value. Start where latency is directly constraining throughput or forcing manual compensation, not where the dashboards merely look slow.
Finally, put governance around performance. Define acceptable latency by use case, assign ownership across IT and OT, and review performance against business outcomes rather than isolated technical tickets.
Conclusion: treat latency as an execution risk, not a background IT issue
When mes system api integration latency starts hurting throughput, the problem has already moved beyond software inconvenience. It is affecting how reliably the factory senses, decides, and responds.
For enterprise decision-makers, the right question is not whether latency exists, but whether it is distorting execution enough to reduce output, resilience, or planning accuracy.
The fastest path to clarity is data-driven. Measure end-to-end event timing, isolate decision-critical workflows, and connect delay patterns to throughput, utilization, and response performance.
In advanced manufacturing, timing integrity is operational integrity. When the MES integration layer falls behind reality, throughput suffers quietly first—then visibly, then expensively.
Organizations that address the issue early gain more than technical speed. They build a production system that can scale with confidence, absorb disruption faster, and make decisions on engineering truth instead of delayed signals.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Sep 29, 2026ISO 9283 Repeatability: How to Evaluate Cobot Positioning PerformanceISO 9283 cobot repeatability explained: learn how payload, reach, approach direction, and test conditions affect positioning performance and cell capability.Chen Wei (Automation Lead Engineer)
 Sep 29, 2026How Do You Verify Servo Motor Torque Under Continuous Load?How do I verify servo motor torque under continuous load? Learn RMS torque checks, torque-speed limits, thermal derating, and real-machine testing.Chen Wei (Automation Lead Engineer)
 Sep 28, 2026Spindle Runout Measurement in Germany: DIN Standards, Methods, and Acceptance LimitsSpindle runout measurement Germany: explore DIN standards, proven methods, acceptance limits, and audit-ready practices for reliable machining quality.Dr. Marcus Vance
 Sep 27, 2026How to Select Wall-Mount Edge Devices for Space-Constrained Factory NetworksWall mount edge devices for space-constrained factories: evaluate workload, thermal design, power resilience, cable access, and network reliability for smarter deployments.TSV Data Lab
 Sep 26, 2026Machining Tolerance Analysis: How to Set Limits That Meet Function and Cost TargetsMachining tolerance analysis: learn how to set functional limits, control tolerance stacks, reduce inspection risk, and balance precision with production cost.Dr. Marcus Vance
 Sep 25, 2026How to Evaluate an Industrial Infrastructure Data Platform for Multi-Site OperationsIndustrial infrastructure data platform evaluation guide for multi-site operations: compare data quality, edge resilience, interoperability, governance, and scalable proof-of-value criteria.Victor Lin (Chief Software Architect)
 Sep 24, 2026How to Select Machine Vision Optics for Accurate Inspection at Different Working DistancesMachine vision optics selection guide for accurate inspection at every working distance. Compare FOV, pixel scale, DOF, distortion, lighting, and telecentric options.TSV Data Lab
 Sep 23, 2026How to Evaluate a Machine Vision System Integrator for High-Speed Inspection LinesChoose a machine vision system integrator with proven expertise in high-speed inspection, reliable reject timing, robust optics, and measurable acceptance criteria.TSV Data Lab
 Sep 29, 2026How MES and OEE work together to identify production lossesMES and OEE work together to uncover hidden production losses, connect downtime, speed, and quality data, and drive smarter shop-floor improvements.Victor Lin (Chief Software Architect)
 Sep 28, 2026When is a SCADA API the right choice for connecting plant systems?SCADA API guide: learn when governed plant data integration improves traceability, security, and scalability—without compromising real-time control.Victor Lin (Chief Software Architect)
 Sep 27, 2026How SCADA data integration improves traceability across production linesSCADA data integration connects production-line data to improve traceability, accelerate quality investigations, and strengthen safety decisions.Victor Lin (Chief Software Architect)
 Sep 26, 2026What to define before starting SCADA integration planningSCADA integration planning starts with clear scope, control boundaries, data models, cybersecurity, and testing. Discover the definitions that reduce risk and costly rework.Victor Lin (Chief Software Architect)
 Sep 25, 2026How a smart factory with Industrial IoT reduces production blind spotsDiscover how a smart factory with Industrial IoT turns real-time machine, quality, and workflow data into actionable insights that reduce production blind spots and delivery risks.Victor Lin (Chief Software Architect)
 Sep 24, 2026When does Industrial IoT make smart manufacturing easier to scale?Smart manufacturing Industrial IoT scales when trusted data, interoperable systems, and secure workflows turn connected assets into measurable gains.TSV Data Lab
 Sep 23, 2026What drives ultra-precision machining cost at 1-micron tolerance?Ultra precision machining cost per part at 1 micron tolerance depends on process, material, metrology, and yield. Learn how to compare quotes confidently.Dr. Marcus Vance
 Sep 22, 2026Drone Engine-T550CC Applications: Build the UAV Power System Around the MissionAn application guide for Drone Engine-T550CC integration, covering payload planning, airframe matching, cooling, fuel, vibration, test procedures, documentation, and service preparation.Elena Rostova (UAV Systems Researcher)
 Sep 22, 2026How to Evaluate Industrial Edge Computing Vendors for Factory DeploymentIndustrial edge computing vendor evaluation guide for factories: compare latency, protocol fit, reliability, security, and lifecycle support before deployment.TSV Data Lab























