How to Test Edge AI Robots for Latency, Safety, and Real-World Reliability?
Publication Date
author
For technical evaluators, robot edge AI testing is not about checking a single benchmark. It is about proving whether a robot can react fast enough, remain safe under abnormal conditions, and keep working when the environment becomes messy, variable, and operationally inconvenient.
The core search intent behind robot edge AI testing is practical validation. Readers are not looking for abstract AI theory. They need a defensible way to measure latency, verify safety behavior, expose failure modes, compare vendors, and decide whether a platform is trustworthy enough for deployment.
That priority shapes the whole evaluation process. The most useful tests are the ones that connect edge inference speed to control-loop timing, link safety claims to observable stop behavior, and translate lab results into evidence about uptime, recovery, and reliability in real operating conditions.
For technical assessment teams, the right overall judgment is simple. A robot edge AI system is ready only when perception, decision, and actuation performance stay within defined limits across realistic workloads, adverse environments, communication interruptions, and component degradation scenarios.
What Technical Evaluators Actually Need From Robot Edge AI Testing
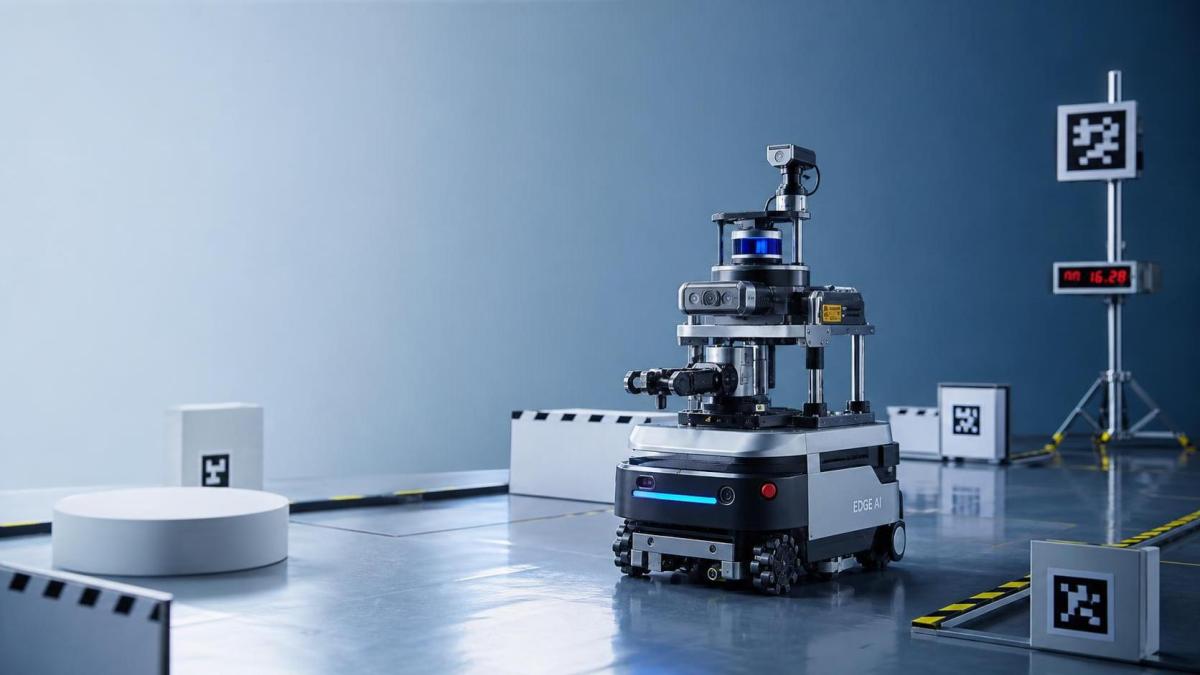
When evaluators search for guidance on robot edge AI testing, they are usually preparing for supplier qualification, pre-deployment validation, or risk review. Their real concern is not whether the robot demos well, but whether its measured behavior remains stable under repeatable and non-ideal conditions.
Three questions dominate most evaluations. First, can the robot meet end-to-end latency requirements for its task class. Second, will it fail safely when sensing, compute, or communication quality deteriorates. Third, does it remain operationally reliable after long runs, environmental stress, and unplanned disturbances.
That means broad marketing metrics are almost useless on their own. Frame rate, TOPS, and nominal inference time may sound impressive, but they do not show whether a mobile robot avoids dynamic obstacles consistently, or whether a manipulator still picks accurately after thermal drift and sensor contamination.
A strong assessment therefore combines subsystem measurements with mission-level testing. You need timing data from the compute stack, fault-response evidence from the safety layer, and task completion data from realistic scenarios. Only that combination reveals whether edge AI performance is operationally meaningful.
Start With a System Definition Before You Measure Anything
Before running tests, define the robot as a closed operational system. List its sensors, edge processor, middleware, control architecture, actuation chain, network dependencies, power limits, and environmental assumptions. Without this map, latency or safety results are hard to interpret and impossible to compare across platforms.
Next, specify the mission profile. A warehouse AMR, a collaborative inspection robot, and an outdoor UAV ground-support rover all have different timing and reliability thresholds. Evaluation criteria must match the actual operating envelope, not a generic robotics checklist borrowed from another application class.
Then define acceptance metrics in engineering terms. Use maximum allowable end-to-end latency, jitter bounds, detection confidence under specific lighting or clutter conditions, emergency stop distance, recovery time after fault, and mission success rate over repeated cycles. Parameters should be measurable and tied to deployment risk.
This stage is where many weak evaluations fail. Teams test what is convenient instead of what matters. If the robot will operate near people, moving carts, reflective surfaces, or electromagnetic noise, those conditions must be represented early in the test design rather than treated as optional edge cases.
How to Test Latency in Edge AI Robots Without Misleading Yourself
Latency testing for edge AI robots should measure the full chain, not just AI inference. The meaningful figure is end-to-end time from sensor capture to physical response. That includes acquisition, preprocessing, model execution, post-processing, middleware transport, planner output, and actuator command execution.
Break latency into layers first. Measure sensor timestamp accuracy, image or point-cloud buffering delay, neural inference time, inter-process communication delay, planner cycle time, and motor-controller response. This decomposition helps identify whether the bottleneck comes from compute, software architecture, or electromechanical lag.
Jitter matters as much as mean latency. A robot with average response of 40 milliseconds but occasional spikes to 180 milliseconds may be unacceptable in dynamic obstacle avoidance or human-robot collaboration. Evaluators should record percentile performance, especially P95, P99, and worst-case outliers during loaded operation.
Testing should also cover workload variation. Run the robot with clean data, cluttered scenes, multiple detected objects, degraded lighting, and concurrent software tasks. Edge AI systems often look stable in isolated benchmarks, then lose timing determinism when perception load and control load increase together.
Thermal behavior is another overlooked factor. Edge processors may throttle under sustained utilization, quietly increasing inference time after thirty or sixty minutes of operation. Long-duration latency logging under realistic ambient temperatures is essential if the robot is intended for continuous shifts rather than short demonstrations.
For mobile and connected systems, verify whether latency changes when network access is limited or unavailable. Some “edge” architectures still rely on cloud services for model updates, map support, or supervisory decisions. Testing must confirm what performance remains fully local and what degrades when connectivity drops.
Safety Testing Must Prove Behavior, Not Just Compliance Claims
Safety evaluation for robot edge AI systems begins with one discipline: separate functional capability from safe behavior. A robot can detect obstacles accurately and still be unsafe if stop logic is delayed, fault handling is ambiguous, or degraded sensing does not trigger a predictable protective response.
Start by identifying hazardous events. Examples include missed human detection, false negative zone intrusion, delayed emergency stop, unstable behavior after sensor dropout, unsafe restart after reboot, and incorrect action selection when model confidence collapses. Each hazard should map to a specific test condition and pass criterion.
Then test normal and abnormal transitions. The robot should behave safely not only during ideal operation, but also during camera occlusion, LiDAR contamination, partial compute failure, actuator overload, battery voltage drop, and middleware crash. Evaluators should observe whether the system enters a bounded, recoverable, and documented state.
Emergency behavior needs direct measurement. Record stopping distance, stop initiation delay, and controlled deceleration under different speeds, payloads, and floor conditions. For manipulators, measure force-limited behavior, contact response, and whether safe torque or safe motion functions behave consistently after repeated triggers.
False positives also deserve attention. An overly conservative system that halts repeatedly may be technically safe but operationally unusable. Good safety testing therefore includes nuisance-stop rate, recovery friction, operator intervention frequency, and whether protective behavior remains proportionate to the actual level of uncertainty.
If a vendor cites compliance with relevant standards, treat that as supporting evidence rather than final proof. Technical evaluators still need test records showing how the implemented system behaves in the application context, because integration details often determine real risk far more than brochure-level certification language.
Real-World Reliability Comes From Exposure to Variability
Reliability testing asks a different question from performance testing. Instead of “How well does the robot work right now,” it asks, “How often does it keep working over time when the environment, hardware state, and task conditions stop being convenient?” That is where many procurement decisions are won or lost.
Begin with endurance runs. Operate the robot over extended cycles with representative missions, payloads, and environmental changes. Track task completion rate, drift in localization or manipulation accuracy, compute temperature, memory stability, sensor health, battery behavior, and frequency of manual resets or operator interventions.
Next, inject controlled variability. Change illumination, introduce reflective materials, add dust, vary floor texture, alter object placement, and include dynamic obstacles or background motion. For outdoor or semi-outdoor robots, add wind, vibration, moisture exposure limits, and electromagnetic interference where relevant to the use case.
Recovery behavior is a core reliability metric. A robust edge AI robot should not only detect faults, but restore operation predictably after transient failures. Measure restart time, data persistence, localization re-acquisition, task resumption quality, and whether the robot returns to a safe default state before continuing work.
Component interaction deserves close inspection. A robot may pass isolated sensor and compute tests, yet fail when small degradations combine. Slight camera blur, CPU heating, reduced battery output, and higher scene complexity can jointly create unacceptable behavior even though no single subsystem appears out of specification.
Field reliability also depends on maintainability. Evaluators should document calibration frequency, ease of cleaning sensors, log accessibility, diagnostic coverage, and replacement complexity for critical modules. A platform that performs well initially but requires constant specialist intervention may be a weak operational choice.
Build a Test Matrix That Connects Data to Deployment Decisions
The most effective robot edge AI testing programs use a structured matrix rather than ad hoc trials. Organize tests by scenario, stressor, metric, threshold, and consequence of failure. This creates traceability from engineering evidence to supplier qualification, operational risk review, and deployment approval decisions.
A practical matrix usually spans four layers: baseline functionality, stressed performance, fault response, and endurance reliability. Within each layer, define exact inputs, environmental conditions, instrumentation method, sample size, and acceptance threshold. Consistency matters because comparison across vendors depends on disciplined repeatability.
Instrumentation should be independent wherever possible. External timing probes, synchronized video, controller logs, safety relay records, and power or temperature data help validate what the robot reports about itself. Internal logs alone are useful, but they should not be the sole source of truth.
Scoring should also reflect application priority. For example, a high-speed mobile robot may place heavier weight on worst-case latency and stop distance, while an inspection manipulator may emphasize detection robustness, repeatability after thermal drift, and mean recovery time after vision faults. One template does not fit every deployment.
Most importantly, report uncertainty honestly. If sample sizes are limited, environments are partially simulated, or certain failure cases could not be reproduced, document those gaps directly. Technical decision-makers need to know where confidence is high, where it is moderate, and where residual risk remains unresolved.
Common Testing Mistakes That Distort Edge AI Robot Evaluation
One common mistake is treating model accuracy as a proxy for robot readiness. A perception model may score well on curated datasets while failing in the robot’s actual camera angle, vibration profile, or lighting conditions. Dataset performance should inform testing, not replace system-level validation.
Another mistake is using average latency without examining tails. Robots fail operationally on spikes, not means. A single delayed obstacle response in a dense environment can matter more than hundreds of nominal cycles, especially where humans, equipment, or high-value payloads are nearby.
Teams also underestimate integration effects. Middleware configuration, thread scheduling, storage bandwidth, time synchronization, and thermal packaging can materially alter edge AI behavior. Evaluating the processor board or model in isolation misses the engineering reality of the deployed robot.
Finally, many reviews stop at pass-fail outcomes. That wastes data. The better approach is to capture margins: how far below the limit average stop distance remains, how much jitter grows under thermal load, how accuracy shifts after lens contamination, and how quickly recovery degrades across repeated disturbances.
What a Defensible Final Judgment Looks Like
A defensible conclusion from robot edge AI testing does not say merely that the system “works.” It states that under defined workloads and environmental conditions, the robot met or missed explicit latency, safety, and reliability thresholds, with known confidence bounds and documented residual risks.
For technical evaluators, that level of clarity is what turns testing into decision-grade evidence. It supports supplier comparison, helps engineering teams identify redesign priorities, and reduces the chance of approving a platform whose weaknesses only emerge after deployment begins.
In practice, the best robot edge AI testing programs are rigorous because they are grounded in operational reality. They measure full-path latency instead of headline inference speed, verify safety responses instead of accepting claims, and challenge reliability through variability, endurance, and recovery testing.
That is the standard worth applying. In edge robotics, deployment trust is never created by a benchmark alone. It is earned when measured performance remains credible after the robot encounters heat, clutter, noise, faults, uncertainty, and the ordinary unpredictability of the real world.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Oct 02, 2026How to Qualify Machined Parts Suppliers for Hard Tech ProgramsHard tech supply chain machined parts demand rigorous supplier qualification. Learn how to assess capability, traceability, quality controls, and delivery resilience.Dr. Marcus Vance
 Oct 01, 2026How to Select an Outdoor Security Radar Sensor for Perimeter Detection?Outdoor security radar sensor selection guide: compare range, accuracy, false-alarm control, integration, and field testing for reliable perimeter detection.TSV Data Lab
 Sep 30, 2026How to Evaluate Solid-State LiDAR Hardware for Outdoor Autonomous VehiclesSolid state LiDAR hardware evaluation guide for outdoor autonomous vehicles—compare range, point-cloud quality, environmental resilience, integration, and safety.TSV Data Lab
 Sep 29, 2026ISO 9283 Repeatability: How to Evaluate Cobot Positioning PerformanceISO 9283 cobot repeatability explained: learn how payload, reach, approach direction, and test conditions affect positioning performance and cell capability.Chen Wei (Automation Lead Engineer)
 Oct 02, 2026What Documents Prove a Precision Machining Supplier Can Hold Tolerance?What documents prove a precision machining supplier can hold tolerance? Explore certificates, FAI reports, calibration, SPC, and traceability evidence to qualify suppliers with confidence.Dr. Marcus Vance
 Oct 01, 2026Can a Machining Supplier Meet Aerospace Fatigue Testing Requirements?Can a machining supplier meet aerospace fatigue testing requirements? Learn the traceability, process control, and test evidence needed for reliable aerospace parts.Dr. Marcus Vance
 Sep 30, 2026Which Industrial Robot Specifications Matter for High-Precision Assembly?Which industrial robot specifications matter most for high-precision assembly? Explore repeatability, accuracy, stiffness, vibration, calibration, and force control for reliable yields.Chen Wei (Automation Lead Engineer)
 Sep 29, 2026How Do You Verify Servo Motor Torque Under Continuous Load?How do I verify servo motor torque under continuous load? Learn RMS torque checks, torque-speed limits, thermal derating, and real-machine testing.Chen Wei (Automation Lead Engineer)
 Oct 02, 2026ZD330 Software Configuration: Verifying Cut-List Import Before PurchaseZD330 software and machine configuration: verify cut-list imports, data mapping, labels, and workflow before purchase to reduce errors and choose with confidence.Victor Lin (Chief Software Architect)
 Sep 28, 2026Spindle Runout Measurement in Germany: DIN Standards, Methods, and Acceptance LimitsSpindle runout measurement Germany: explore DIN standards, proven methods, acceptance limits, and audit-ready practices for reliable machining quality.Dr. Marcus Vance
 Sep 27, 2026How to Select Wall-Mount Edge Devices for Space-Constrained Factory NetworksWall mount edge devices for space-constrained factories: evaluate workload, thermal design, power resilience, cable access, and network reliability for smarter deployments.TSV Data Lab
 Sep 26, 2026Machining Tolerance Analysis: How to Set Limits That Meet Function and Cost TargetsMachining tolerance analysis: learn how to set functional limits, control tolerance stacks, reduce inspection risk, and balance precision with production cost.Dr. Marcus Vance
 Sep 25, 2026How to Evaluate an Industrial Infrastructure Data Platform for Multi-Site OperationsIndustrial infrastructure data platform evaluation guide for multi-site operations: compare data quality, edge resilience, interoperability, governance, and scalable proof-of-value criteria.Victor Lin (Chief Software Architect)
 Sep 24, 2026How to Select Machine Vision Optics for Accurate Inspection at Different Working DistancesMachine vision optics selection guide for accurate inspection at every working distance. Compare FOV, pixel scale, DOF, distortion, lighting, and telecentric options.TSV Data Lab
 Sep 23, 2026How to Evaluate a Machine Vision System Integrator for High-Speed Inspection LinesChoose a machine vision system integrator with proven expertise in high-speed inspection, reliable reject timing, robust optics, and measurable acceptance criteria.TSV Data Lab
 Oct 02, 2026What affects the cost of a pick and place robot cell?Pick and place robot cost depends on throughput, tooling, vision, safety, and integration. Compare quotes confidently and avoid hidden automation costs.Chen Wei (Automation Lead Engineer)
 Oct 01, 2026What is included in a robotic system integration project cost?Robotic system integration project cost explained: compare equipment, engineering, safety, testing, installation, and lifecycle factors for smarter automation investments.Chen Wei (Automation Lead Engineer)