How to Evaluate Predictive Maintenance Software for Multi-Site Manufacturing Plants
Publication Date
author
Evaluating predictive maintenance software for multi-site manufacturing plants starts with one practical question: can the platform improve uptime with evidence, not promises? In distributed operations, failures rarely stay local. A bearing issue in one facility can expose maintenance gaps, inconsistent sensor data, and weak reporting standards across the network. That is why predictive maintenance software has moved from an experimental digital tool to a strategic operating decision.
For organizations managing complex assets, the real challenge is not access to vendors. It is separating useful engineering capability from polished marketing language. In the spirit of TechStat Vanguard’s view that parameters matter more than adjectives, software evaluation should focus on data fidelity, integration depth, model transparency, and operational fit across different plants.
Why multi-site evaluation is different
A single plant can often tolerate inconsistent workflows for a while.
A multi-site footprint usually cannot.
Different machine vintages, control systems, maintenance cultures, and local reporting practices create a fragmented data environment. Predictive maintenance software must work across that variation without flattening important context.
That is also why a plant-by-plant pilot can be misleading. A platform may perform well in a highly instrumented site, then lose value in older facilities with sparse sensor coverage or inconsistent CMMS records.
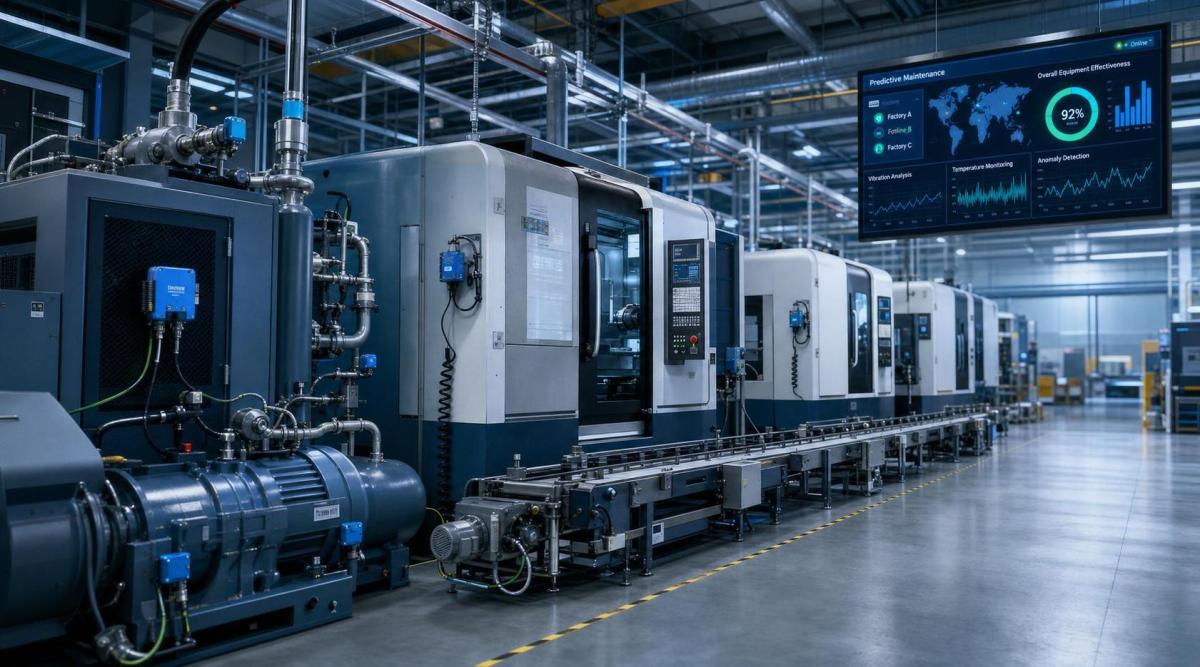
The useful benchmark is not whether the system produces alerts. It is whether it produces reliable, comparable insight across sites with different operating realities.
What predictive maintenance software should actually do
At a basic level, predictive maintenance software analyzes condition, usage, and failure patterns to identify probable asset issues before breakdown occurs.
That definition is too broad to guide a purchase.
In practice, the software should connect machine signals, maintenance history, and operating context into decisions that maintenance teams can act on. It should help answer whether a component is degrading, how urgent the issue is, and what intervention is justified.
The strongest systems usually combine several functions:
- continuous condition monitoring for vibration, temperature, pressure, current, or acoustic signals;
- anomaly detection that distinguishes true equipment drift from normal operational variation;
- failure prediction models linked to asset type, duty cycle, and environment;
- workflow integration with CMMS, EAM, SCADA, MES, and historian systems;
- site-level and enterprise-level dashboards that preserve local detail while enabling network comparison.
If one of these layers is missing, the promised value often collapses in day-to-day use.
Data quality is the first gate
The quality of predictive maintenance software is limited by the quality of the data it consumes.
This sounds obvious, but many evaluations still begin with dashboard design instead of signal integrity. That order is backwards.
When reviewing a platform, look at how it handles missing data, sensor drift, timestamp misalignment, and inconsistent asset naming. In multi-site plants, these issues are normal, not exceptional.
A serious platform should show how it cleans, normalizes, and validates incoming data. It should also expose confidence levels, not hide uncertainty behind a clean interface.
Questions worth asking
- What minimum sampling frequency is required for each asset class?
- How does the system flag low-confidence predictions?
- Can models adapt when operating loads change between plants?
- How much manual data engineering is needed after deployment?
These details matter more than broad claims about artificial intelligence.
Integration depth shapes long-term value
A predictive model has limited business value if it sits outside the maintenance workflow.
In real operations, value appears when alerts trigger inspection routines, work orders, spare parts checks, and follow-up verification. That requires integration, not just visibility.
For multi-site use, the platform should connect to both enterprise systems and local plant infrastructure. Compatibility with PLC environments, historians, MES layers, and CMMS tools is usually more important than an impressive front end.
It is also worth checking whether integration is native, API-based, or dependent on custom services. Hidden integration effort often becomes the most expensive part of rollout.
Scalability is not just about adding more sites
Many vendors define scale as the ability to onboard more assets.
That is only one part of the picture.
In a distributed manufacturing network, scale means supporting different asset criticalities, regulatory environments, maintenance teams, and data maturity levels without losing consistency.
A scalable predictive maintenance software platform should allow standard governance with local flexibility. That may include shared KPI definitions, central model libraries, and role-based access, while still accommodating plant-specific thresholds and maintenance practices.
This is especially relevant in sectors adjacent to aerospace, robotics, machining, and sensor-intensive production, where TSV-style benchmarking depends on parameter discipline. If the software cannot preserve data lineage and asset context, comparisons across sites become politically convenient but technically weak.
Look for engineering relevance, not black-box excitement
The most attractive interface is not always the most useful system.
What matters is whether plant teams can understand why the software generated an alert and what action it supports.
Engineering relevance shows up in explainability. For example, can the platform tie a warning to rising vibration on a known failure mode? Can it separate load-related changes from mechanical degradation? Can it show how prior maintenance history affects the recommendation?
This is where many predictive maintenance software evaluations become too commercial. A system that cannot explain signal behavior in operational terms may still demonstrate machine learning sophistication, but it will struggle to earn trust where uptime decisions carry real cost.
Useful proof points during evaluation
- false positive rate by asset category;
- lead time between alert and verified failure condition;
- reduction in unplanned downtime after workflow adoption;
- maintenance labor impact, not just model accuracy;
- evidence from plants with similar equipment age and complexity.
Where software creates value across the network
The strongest business case usually appears in high-value, failure-sensitive assets.
That includes rotating equipment, CNC spindles, compressors, conveyors, HVAC support systems, robotics cells, and process-critical pumps. In these environments, predictive maintenance software can reduce surprise stoppages and improve spare parts timing.
There is also a second layer of value that matters in multi-site networks. Standardized condition visibility helps identify whether one plant has a local maintenance issue or whether a recurring pattern points to supplier quality, asset design, or operating practice.
That wider view supports better capital planning. It also shortens the cycle between detecting a pattern and acting on it across the network.
A practical evaluation path
A disciplined selection process usually starts with asset criticality, not software features.
Map the assets where failure creates the highest production, safety, or quality impact. Then review whether the necessary data already exists, what sensing gaps remain, and how each site records maintenance events.
From there, compare vendors against a shared scorecard:
- data readiness and model transparency;
- integration effort across OT and IT layers;
- ability to support legacy and modern assets together;
- governance for cross-site deployment;
- measurable outcome targets for uptime, cost, and reliability.
A pilot should include at least two contrasting sites. One should be digitally mature. One should reflect the harder reality of partial instrumentation and uneven records.
That approach reveals whether the predictive maintenance software can scale beyond the showcase environment. It also produces a more honest basis for investment decisions, rollout sequencing, and internal alignment.
The next step is not to chase the broadest feature list. It is to define the operating conditions, data standards, and business thresholds that matter most, then test which platform can meet them with traceable evidence. In a market crowded with claims, that is still the clearest path to choosing predictive maintenance software that will hold up across the full manufacturing network.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Oct 02, 2026How to Qualify Machined Parts Suppliers for Hard Tech ProgramsHard tech supply chain machined parts demand rigorous supplier qualification. Learn how to assess capability, traceability, quality controls, and delivery resilience.Dr. Marcus Vance
 Oct 01, 2026How to Select an Outdoor Security Radar Sensor for Perimeter Detection?Outdoor security radar sensor selection guide: compare range, accuracy, false-alarm control, integration, and field testing for reliable perimeter detection.TSV Data Lab
 Sep 30, 2026How to Evaluate Solid-State LiDAR Hardware for Outdoor Autonomous VehiclesSolid state LiDAR hardware evaluation guide for outdoor autonomous vehicles—compare range, point-cloud quality, environmental resilience, integration, and safety.TSV Data Lab
 Sep 29, 2026ISO 9283 Repeatability: How to Evaluate Cobot Positioning PerformanceISO 9283 cobot repeatability explained: learn how payload, reach, approach direction, and test conditions affect positioning performance and cell capability.Chen Wei (Automation Lead Engineer)
 Oct 01, 2026Can a Machining Supplier Meet Aerospace Fatigue Testing Requirements?Can a machining supplier meet aerospace fatigue testing requirements? Learn the traceability, process control, and test evidence needed for reliable aerospace parts.Dr. Marcus Vance
 Sep 30, 2026Which Industrial Robot Specifications Matter for High-Precision Assembly?Which industrial robot specifications matter most for high-precision assembly? Explore repeatability, accuracy, stiffness, vibration, calibration, and force control for reliable yields.Chen Wei (Automation Lead Engineer)
 Sep 29, 2026How Do You Verify Servo Motor Torque Under Continuous Load?How do I verify servo motor torque under continuous load? Learn RMS torque checks, torque-speed limits, thermal derating, and real-machine testing.Chen Wei (Automation Lead Engineer)
 Oct 02, 2026ZD330 Software Configuration: Verifying Cut-List Import Before PurchaseZD330 software and machine configuration: verify cut-list imports, data mapping, labels, and workflow before purchase to reduce errors and choose with confidence.Victor Lin (Chief Software Architect)
 Sep 28, 2026Spindle Runout Measurement in Germany: DIN Standards, Methods, and Acceptance LimitsSpindle runout measurement Germany: explore DIN standards, proven methods, acceptance limits, and audit-ready practices for reliable machining quality.Dr. Marcus Vance
 Sep 27, 2026How to Select Wall-Mount Edge Devices for Space-Constrained Factory NetworksWall mount edge devices for space-constrained factories: evaluate workload, thermal design, power resilience, cable access, and network reliability for smarter deployments.TSV Data Lab
 Sep 26, 2026Machining Tolerance Analysis: How to Set Limits That Meet Function and Cost TargetsMachining tolerance analysis: learn how to set functional limits, control tolerance stacks, reduce inspection risk, and balance precision with production cost.Dr. Marcus Vance
 Sep 25, 2026How to Evaluate an Industrial Infrastructure Data Platform for Multi-Site OperationsIndustrial infrastructure data platform evaluation guide for multi-site operations: compare data quality, edge resilience, interoperability, governance, and scalable proof-of-value criteria.Victor Lin (Chief Software Architect)
 Sep 24, 2026How to Select Machine Vision Optics for Accurate Inspection at Different Working DistancesMachine vision optics selection guide for accurate inspection at every working distance. Compare FOV, pixel scale, DOF, distortion, lighting, and telecentric options.TSV Data Lab
 Sep 23, 2026How to Evaluate a Machine Vision System Integrator for High-Speed Inspection LinesChoose a machine vision system integrator with proven expertise in high-speed inspection, reliable reject timing, robust optics, and measurable acceptance criteria.TSV Data Lab
 Oct 01, 2026What is included in a robotic system integration project cost?Robotic system integration project cost explained: compare equipment, engineering, safety, testing, installation, and lifecycle factors for smarter automation investments.Chen Wei (Automation Lead Engineer)
 Sep 30, 2026How much does warehouse automation cost for a growing distribution center?How much does warehouse automation cost? Explore equipment, integration, facility upgrades, lifecycle expenses, and ROI factors for a growing distribution center.Chen Wei (Automation Lead Engineer)
 Sep 29, 2026How MES and OEE work together to identify production lossesMES and OEE work together to uncover hidden production losses, connect downtime, speed, and quality data, and drive smarter shop-floor improvements.Victor Lin (Chief Software Architect)