
What repeatability numbers really mean for cobot accuracy
Publication Date
author
In cobot selection and daily operation, repeatability is often quoted as a shortcut for accuracy—but the number alone can mislead. This article breaks down what collaborative robots repeatability benchmarks actually measure, how test conditions affect results, and why operators should read beyond the datasheet. If you want more stable positioning, fewer process errors, and better real-world performance, understanding repeatability is the first step.
Why repeatability matters differently from one workflow to another
For operators, the biggest mistake is assuming a single repeatability figure predicts success in every task. In reality, the same cobot can perform well in one station and poorly in another, even when the published specification looks impressive. That is why collaborative robots repeatability benchmarks should be read as context-dependent engineering data, not as a universal promise.
A ±0.02 mm repeatability value may sound excellent, but what does it mean on a live production floor? The answer depends on payload, reach, speed, mounting orientation, gripper mass, fixture rigidity, ambient vibration, and the direction of approach. A dispensing station, a screwdriving cell, and a machine-tending setup all stress the robot differently. Operators who understand these differences can avoid false expectations, reduce process drift, and communicate better with engineering and maintenance teams.
This is especially important in data-driven manufacturing environments such as those advocated by TechStat Vanguard, where parameters must be interpreted through actual operating conditions. Numbers matter, but only when linked to the scenario in which they were measured and the scenario in which they will be used.
What collaborative robots repeatability benchmarks actually measure
Repeatability describes how closely a cobot can return to the same taught point over multiple cycles. It does not necessarily describe whether the robot can reach the true intended coordinate from an absolute reference without calibration error. That distinction is critical for operators.
In practical terms, repeatability answers this question: if the robot performs the same motion many times, how tightly does the endpoint cluster? Accuracy answers a different question: how close is that endpoint to the exact target location in the world coordinate system? A robot may be highly repeatable but still require offset correction, vision compensation, or fixture tuning to hit the true target consistently.
Most collaborative robots repeatability benchmarks are generated under controlled test conditions. These often include a defined payload, a specific arm posture, a stable room temperature, low external vibration, and a standard tool setup. Once real production introduces longer cycle paths, offset tooling, frequent starts and stops, or mixed part tolerances, benchmark values may no longer reflect actual station performance.
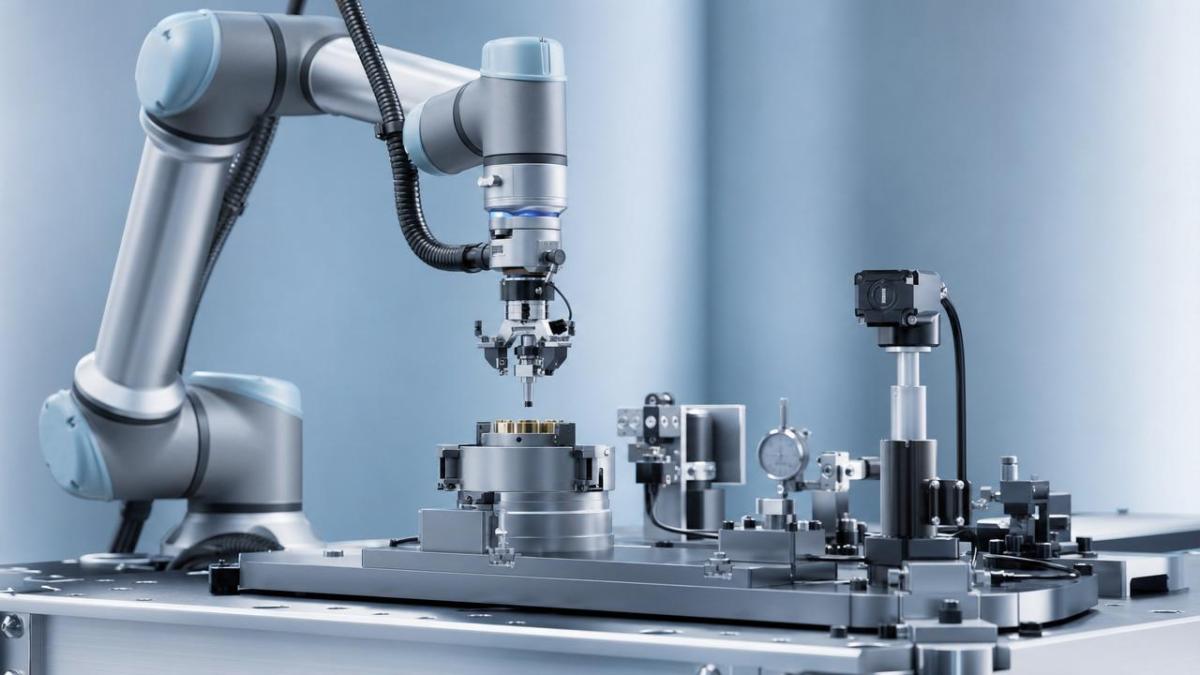
Scenario-based comparison: the same number means different things in different jobs
To make collaborative robots repeatability benchmarks useful, operators should translate them into process demands. The table below shows how common applications interpret the same specification differently.
Typical operating scenarios and what to check in each one
High-mix pick-and-place: repeatability helps, but part variation dominates
In mixed-part environments, operators often look at collaborative robots repeatability benchmarks first. That is reasonable, but not sufficient. If parts arrive in inconsistent orientations, if trays deform, or if bins allow shifting, the robot’s return-to-point performance becomes only one variable. In this scenario, gripper design and sensing strategy often matter more than chasing an ultra-tight specification.
A practical judgment rule is simple: if the incoming part location varies more than the robot’s repeatability by a large margin, improving repeatability alone will not fix missed picks. Operators should instead verify fixture condition, part presentation, vacuum cup wear, and vision system update rates.
Machine tending: benchmark numbers must survive thermal and mechanical reality
Machine tending looks straightforward on paper, yet it is one of the easiest places to misread collaborative robots repeatability benchmarks. The robot may repeatedly return to a point, but if the chuck expands with heat, the machine door stops slightly short, or the gripper fingers wear unevenly, insertion quality still drops over the shift.
Operators in this scenario should pay close attention to approach direction repeatability, not just point repeatability. Coming into a fixture from the same vector with the same speed can matter more than the static number in the brochure. If jams occur only after warm-up, thermal behavior across the entire cell should be investigated before blaming the cobot itself.
Screwdriving and fastening: alignment quality is more than endpoint clustering
Operators often assume a strong repeatability value guarantees smooth thread engagement. In practice, fastening requires good coaxiality between the bit and the screw, controlled downward force, and tolerance for part-to-part variation. A robot that repeats the same small position error may still cross-thread if the process has no compliance.
For this application, collaborative robots repeatability benchmarks should be read together with end-effector rigidity, reaction torque handling, and tool center point calibration discipline. Even a well-rated cobot may need a floating screwdriver mount or force-based search routine to achieve robust production results.
Dispensing, sealing, and gluing: path consistency matters as much as point repeatability
In dispensing tasks, operators can be misled by point-based benchmarks because the quality issue often appears along a path rather than at a single location. A uniform glue bead depends on robot motion smoothness, speed stability, acceleration tuning, nozzle distance, and material pressure control. A cobot may return to start and end points accurately while still producing uneven bead geometry on curves or corners.
This is why collaborative robots repeatability benchmarks should be treated as an entry filter, not a final decision tool. For dispensing stations, path test samples under actual cycle speeds are far more informative than a datasheet value alone.
What changes benchmark results in the real world
Operators and line leaders should know the main factors that can widen the gap between lab-tested numbers and floor performance:
- Payload near the upper limit, especially with long or offset tools
- Reach extension, where arm posture becomes less rigid
- Fast acceleration and abrupt direction changes
- Flexible tables, mobile bases, or nearby vibration sources
- Temperature shifts over long operating hours
- Wear in grippers, fingertips, screw bits, or nozzles
- Inconsistent calibration of tool center point and work object frames
These variables explain why two plants using the same cobot model can report very different results. Collaborative robots repeatability benchmarks are most valuable when operators compare them against their own process envelope rather than treating them as fixed truth.
A practical checklist for operators before trusting the spec
If you are responsible for setup, operation, or first-line troubleshooting, use the following checks before concluding that a repeatability number is good enough for your station:
- What is the actual tolerance window of the process, not just the robot?
- Is the part location variation larger than the published repeatability?
- Will the robot run close to maximum reach or payload?
- Does the task depend on path quality, insertion angle, or force control?
- Can fixtures, tables, or machine interfaces move during the shift?
- Is there a need for vision correction, compliance, or periodic recalibration?
- Have real sample parts been tested over enough cycles to reveal drift?
This operator-level discipline turns collaborative robots repeatability benchmarks into a useful decision aid instead of a marketing shortcut.
Common misjudgments in repeatability-based cobot selection
One common error is buying a tighter-spec robot for a process that actually suffers from fixture inconsistency. Another is rejecting a cobot because its benchmark number looks weaker, even though the application relies more on vision guidance and compliance than on pure endpoint repeatability. A third is testing the robot empty-handed, then adding a heavier tool and expecting identical results.
Operators should also watch for confusion between repeatability and calibration quality. If a station slowly shifts after maintenance, the issue may be tool center point setup, workpiece reference loss, or end-effector replacement rather than robot mechanical degradation. The benchmark did not change; the process condition did.
How to use collaborative robots repeatability benchmarks the right way
The best use of collaborative robots repeatability benchmarks is comparative and scenario-based. Use them to narrow options, then validate under real payload, real tooling, real parts, and real cycle times. For a low-risk pick-and-place task, a moderate benchmark may be completely sufficient. For precision dispensing or tightly guided insertion, you need deeper validation of path stability, frame calibration, and station rigidity.
That approach aligns with TSV’s engineering-first philosophy: parameters do not lie, but they must be read in context. Operators who understand what the number measures, what it does not measure, and how their own workflow stresses the robot are far more likely to achieve stable output and lower rework.
FAQ for users comparing cobot performance
Is lower repeatability always better?
Only if your process can actually use that tighter performance. If fixtures, parts, or tools vary more than the robot does, a better number may deliver little practical gain.
Can a highly repeatable cobot still miss targets?
Yes. It may repeatedly return to the same wrong point if calibration, work offsets, or part presentation are incorrect.
Should operators ask suppliers how collaborative robots repeatability benchmarks were tested?
Absolutely. Ask about payload, speed, reach, posture, temperature, mounting condition, and whether tooling was included. Test context is part of the number.
Final takeaway for real production decisions
For operators, the most useful question is not “What is the repeatability value?” but “Is this value meaningful for my task, my tooling, and my tolerance chain?” Collaborative robots repeatability benchmarks remain essential, but they work best when tied to the application scenario: pick-and-place, machine tending, fastening, dispensing, or inspection. Read the benchmark, then test the process around it.
If your team is evaluating cobots, build a short validation plan around your own station conditions. Measure actual part variation, confirm tool center point stability, and run enough cycles to expose drift. That is how repeatability becomes operational insight rather than a line in a brochure.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Sep 28, 2026Spindle Runout Measurement in Germany: DIN Standards, Methods, and Acceptance LimitsSpindle runout measurement Germany: explore DIN standards, proven methods, acceptance limits, and audit-ready practices for reliable machining quality.Dr. Marcus Vance
 Sep 27, 2026How to Select Wall-Mount Edge Devices for Space-Constrained Factory NetworksWall mount edge devices for space-constrained factories: evaluate workload, thermal design, power resilience, cable access, and network reliability for smarter deployments.TSV Data Lab
 Sep 26, 2026Machining Tolerance Analysis: How to Set Limits That Meet Function and Cost TargetsMachining tolerance analysis: learn how to set functional limits, control tolerance stacks, reduce inspection risk, and balance precision with production cost.Dr. Marcus Vance
 Sep 25, 2026How to Evaluate an Industrial Infrastructure Data Platform for Multi-Site OperationsIndustrial infrastructure data platform evaluation guide for multi-site operations: compare data quality, edge resilience, interoperability, governance, and scalable proof-of-value criteria.Victor Lin (Chief Software Architect)
 Sep 24, 2026How to Select Machine Vision Optics for Accurate Inspection at Different Working DistancesMachine vision optics selection guide for accurate inspection at every working distance. Compare FOV, pixel scale, DOF, distortion, lighting, and telecentric options.TSV Data Lab
 Sep 23, 2026How to Evaluate a Machine Vision System Integrator for High-Speed Inspection LinesChoose a machine vision system integrator with proven expertise in high-speed inspection, reliable reject timing, robust optics, and measurable acceptance criteria.TSV Data Lab
 Sep 28, 2026When is a SCADA API the right choice for connecting plant systems?SCADA API guide: learn when governed plant data integration improves traceability, security, and scalability—without compromising real-time control.Victor Lin (Chief Software Architect)
 Sep 27, 2026How SCADA data integration improves traceability across production linesSCADA data integration connects production-line data to improve traceability, accelerate quality investigations, and strengthen safety decisions.Victor Lin (Chief Software Architect)
 Sep 26, 2026What to define before starting SCADA integration planningSCADA integration planning starts with clear scope, control boundaries, data models, cybersecurity, and testing. Discover the definitions that reduce risk and costly rework.Victor Lin (Chief Software Architect)
 Sep 25, 2026How a smart factory with Industrial IoT reduces production blind spotsDiscover how a smart factory with Industrial IoT turns real-time machine, quality, and workflow data into actionable insights that reduce production blind spots and delivery risks.Victor Lin (Chief Software Architect)
 Sep 24, 2026When does Industrial IoT make smart manufacturing easier to scale?Smart manufacturing Industrial IoT scales when trusted data, interoperable systems, and secure workflows turn connected assets into measurable gains.TSV Data Lab
 Sep 23, 2026What drives ultra-precision machining cost at 1-micron tolerance?Ultra precision machining cost per part at 1 micron tolerance depends on process, material, metrology, and yield. Learn how to compare quotes confidently.Dr. Marcus Vance
 Sep 22, 2026Drone Engine-T550CC Applications: Build the UAV Power System Around the MissionAn application guide for Drone Engine-T550CC integration, covering payload planning, airframe matching, cooling, fuel, vibration, test procedures, documentation, and service preparation.Elena Rostova (UAV Systems Researcher)
 Sep 22, 2026How to Evaluate Industrial Edge Computing Vendors for Factory DeploymentIndustrial edge computing vendor evaluation guide for factories: compare latency, protocol fit, reliability, security, and lifecycle support before deployment.TSV Data Lab
 Sep 21, 2026Drone Payload Integration: Matching Power, Data, and Center of Gravity for Reliable FlightsDrone payload integration made practical: balance power, data, center of gravity, and endurance to build safer, more reliable mission-ready flights.Elena Rostova (UAV Systems Researcher)
 Sep 20, 2026Autonomous Navigation Pricing: Cost Drivers and Budget Benchmarks for AMR ProjectsAutonomous navigation price explained: compare AMR cost drivers, software, sensors, integration, safety, and lifecycle budgets to build a scalable project plan.Chen Wei (Automation Lead Engineer)
 Sep 19, 2026How to Scope Automation Integration Services for Multi-System Factory ProjectsAutomation integration services: learn how to scope multi-system factory projects with clear workflows, interface contracts, safety boundaries, and acceptance criteria.Victor Lin (Chief Software Architect)























