
Are Cobot Repeatability Claims Good Enough for Precision Tasks?
Publication Date
author
For technical evaluators, vendor claims on cobot precision often sound sufficient—until real-world tolerances, payload shifts, and mounting conditions expose the gap between brochures and production reality. This article examines whether collaborative robots repeatability benchmarks truly support precision tasks, helping engineers separate nominal specs from decision-grade performance data before qualification, deployment, or supplier comparison.
In advanced manufacturing, repeatability is one of the first numbers buyers compare, but it is rarely the last number that determines success. A cobot promoted at ±0.02 mm may perform adequately for light pick-and-place, yet struggle when a process demands stable path quality, off-axis loading, or fixture-to-tool consistency across 8-hour to 24-hour production windows. For teams building supplier shortlists, collaborative robots repeatability benchmarks must be interpreted as a starting point rather than a complete precision qualification.
At TechStat Vanguard, the key question is not whether a claim looks competitive on paper. The real question is whether the benchmark reflects usable engineering truth under production conditions: real payloads, real cycle times, real mounting orientations, and real tolerance stacks. That distinction matters when one failed assumption can extend commissioning by 2 to 6 weeks or trigger costly rework in aerospace, electronics, medical, or precision machining workflows.
Why Repeatability Claims Can Mislead Precision Evaluations
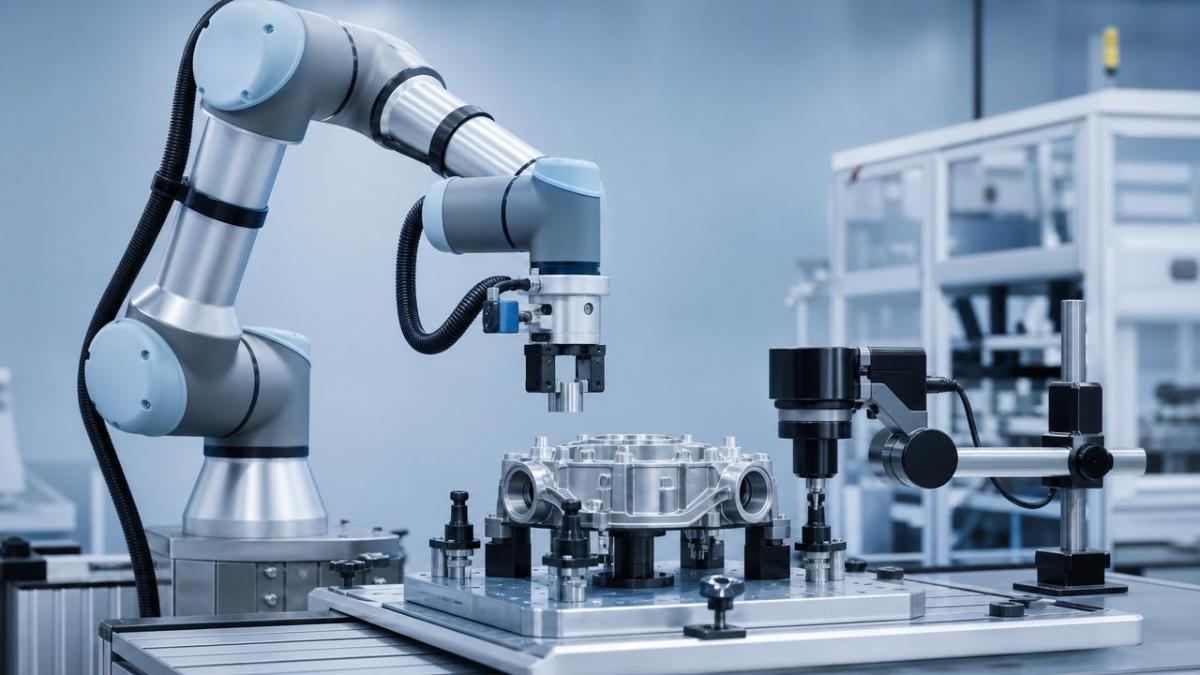
Cobot suppliers usually publish repeatability as a single value, often measured near ideal conditions: a controlled environment, a defined payload, a limited working envelope, and a standardized test cycle. That figure is useful, but it does not automatically predict process capability. For technical evaluators, collaborative robots repeatability benchmarks need context around how the number was measured, where in the workspace it was measured, and what happens when the arm is exposed to vibration, heat drift, or changing inertial loads.
Repeatability is not the same as accuracy
A robot can return to the same point repeatedly and still miss the true target location. Repeatability describes how consistently the robot reaches a taught position, while accuracy describes how close that position is to the intended coordinate. In tasks such as dispensing, screwdriving, laser alignment, or machine tending with tight datum requirements, a system may require both low positional scatter and reliable absolute positioning. A ±0.03 mm repeatability spec alone cannot guarantee either.
Why this difference matters on the factory floor
- For insertion tasks, 0.05 mm to 0.10 mm hole clearance can leave little margin for tool deflection.
- For adhesive or sealant application, path deviation over 300 mm to 800 mm may matter more than point return.
- For vision-guided operations, calibration drift between robot, camera, and fixture can dominate the final result.
- For metrology-adjacent handling, thermal change of only 3°C to 5°C may alter precision enough to fail repeat runs.
This is why decision-makers should read collaborative robots repeatability benchmarks together with accuracy, path performance, backlash behavior, compliance under load, and recalibration frequency. A brochure-friendly number can still mask a weak fit for precision workflows if the robot behaves differently at 20% payload versus 80% payload, or at 30% reach versus near maximum extension.
The hidden variables behind a published specification
Most vendor claims do not fully describe the test envelope. Even a credible repeatability figure should be checked against six variables: payload, tool center point offset, mounting orientation, duty cycle, speed profile, and environmental stability. In practice, moving from a benchtop demonstration to a ceiling mount or mobile pedestal can change system stiffness enough to affect results.
The table below shows how common production variables can widen the gap between nominal specification and usable precision during evaluation.
The main takeaway is simple: a single benchmark number without test conditions is incomplete. For precision tasks, the evaluation target should be a performance window, not only a best-case value. That is the standard TSV recommends when comparing collaborative robots repeatability benchmarks across suppliers.
Which tasks are most exposed to over-optimistic claims?
Not all cobot applications need the same level of rigor. Carton loading, kitting, and basic transfer may tolerate wider variation. Precision sanding, micro-dispensing, test probe placement, and machine loading into tightly toleranced fixtures usually cannot. If your process tolerance stack is below ±0.15 mm, or if tool-to-feature alignment must stay stable over 500 to 2,000 cycles per shift, repeatability claims should be independently stress-tested before purchase approval.
- High-mix assembly with frequent recipe changes and retaught waypoints.
- Force-sensitive insertion where minor angular error causes part damage or jamming.
- Surface processing where path smoothness affects finish quality over long trajectories.
- Fixture-dependent machine tending where tolerance stack-up includes robot, gripper, part, and chucking variation.
How Technical Evaluators Should Benchmark Cobots for Precision Tasks
A strong evaluation framework replaces marketing adjectives with measurable pass-fail criteria. Instead of asking whether a cobot has “good repeatability,” ask whether it holds the required process capability under your actual task envelope. In many projects, that means running 3 to 5 benchmark routines, across 2 or more payload states, over at least 500 consecutive cycles, with measurement at multiple points in the workspace.
A practical 5-step validation sequence
- Define the task tolerance stack, including part tolerance, gripper tolerance, fixture repeatability, and robot contribution.
- Test at minimum, nominal, and near-maximum payload conditions where applicable.
- Measure performance at center reach and edge-of-envelope positions.
- Run short-cycle and endurance-cycle tests, such as 50 cycles and 1,000 cycles.
- Record recovery after stop-start events, teach updates, and thermal stabilization over 1 to 3 hours.
This approach produces decision-grade evidence rather than a demo impression. It also helps procurement and engineering teams align on a common approval language. A robot that passes only under one gripper, one speed, and one mounting setup may still be too risky for scaled deployment across multiple lines or regions.
Key metrics beyond the headline spec
When building supplier comparisons, evaluators should expand collaborative robots repeatability benchmarks into a broader scorecard. Precision suitability usually depends on several linked metrics, not one.
Using this wider metric set often changes the ranking of shortlisted robots. A model with a slightly weaker brochure figure may outperform a nominally tighter competitor once path quality, drift behavior, and payload sensitivity are included. That is exactly why collaborative robots repeatability benchmarks should be normalized against application conditions, not copied directly into a sourcing matrix.
Benchmark acceptance criteria by task type
Acceptance thresholds should follow process criticality. There is no universal “precision-ready” number. A cobot for packaging can tolerate looser scatter than one used for electronics handling or fine finishing. The important step is to convert process risk into measurable gates before factory trials begin.
Typical qualification logic
- Low-risk handling: qualify around stable cycle consistency and uptime behavior.
- Medium-precision assembly: evaluate point repeatability, stop accuracy, and fixture interaction.
- High-precision process tasks: add path deviation, drift analysis, and endurance testing under full tooling load.
- Regulated or traceable production: require documented test methods, revision-controlled parameters, and repeatable acceptance reports.
For many technical teams, the most effective rule is to reserve at least 20% to 30% of the total tolerance budget for unexpected integration effects. That protects the project from hidden losses introduced by end-of-arm tooling, vision registration, base flatness, cable drag, or fixture wear over time.
Common Procurement Mistakes and a More Reliable Supplier Comparison Method
Cobot sourcing decisions often fail not because the robot is poor, but because the comparison method is too shallow. When procurement teams focus on price, payload, and a single repeatability spec, they may overlook the exact factors that create downstream engineering cost. For precision use cases, a lower upfront price can be offset quickly by 3 hidden penalties: longer validation time, more fixture redesign, and lower first-pass yield during launch.
Three frequent mistakes in supplier review
- Comparing published repeatability numbers without matching the test conditions.
- Ignoring the stiffness and tolerance of the mounting structure, pedestal, or mobile base.
- Accepting demo success without cycle-count evidence or shift-length drift data.
Another common issue is failing to separate robot capability from system capability. The gripper, sensor stack, cable routing, PLC timing, and fixture interface can each contribute enough variation to turn a “qualified” robot into a weak production cell. In TSV-style evaluation, collaborative robots repeatability benchmarks are only meaningful when system-level contributors are logged and controlled.
A procurement-oriented comparison framework
A more reliable sourcing matrix weights measurable engineering outcomes. For example, a technical team may assign 30% to precision performance, 20% to integration flexibility, 20% to maintainability, 15% to documentation quality, and 15% to commercial factors such as lead time and support response. This structure avoids overvaluing one attractive spec while underestimating deployment risk.
- Precision performance: point repeatability, path quality, drift, and recovery consistency.
- Integration flexibility: fieldbus support, vision compatibility, mounting options, and safety I/O.
- Maintainability: calibration stability, spare availability, and service interval guidance.
- Documentation quality: test method clarity, parameter traceability, and application notes.
- Commercial viability: lead time ranges such as 4 to 12 weeks and support escalation timelines.
Questions evaluators should ask every vendor
Ask for the repeatability test standard used, the payload during testing, the tool center point offset, the number of cycles recorded, the ambient temperature range, and the mounting configuration. Also ask whether the vendor can support acceptance testing at your target throughput. If the application needs 12 picks per minute or a 45-second machine tending cycle, the benchmark should reflect that pace rather than a slower demonstration profile.
For organizations managing multi-site sourcing, consistency of documentation is as important as the robot itself. If one supplier provides clear measurement methods and another offers only brochure figures, the first supplier often presents lower lifecycle risk even before physical trials begin.
What “Good Enough” Really Means for Precision Work
The phrase “good enough” should never be defined by the vendor alone. It should be defined by the task, the tolerance stack, and the cost of failure. In some operations, a cobot with moderate repeatability is entirely suitable when paired with compliant tooling, vision compensation, or adaptive fixturing. In others, no amount of software compensation will overcome mechanical limits near the required threshold.
When a cobot is a strong fit
Cobots are often a strong choice when the process benefits from safe human collaboration, moderate force interaction, fast deployment, and flexible cell layout. They can perform very well in precision-adjacent operations where tolerances are controlled through fixtures, compliance devices, or sensor feedback. In such cases, collaborative robots repeatability benchmarks may be fully adequate if validated under realistic conditions.
When a higher-rigidity platform may be necessary
If the task requires sustained micron-level consistency, aggressive cycle speeds with heavy tooling, or highly stable path execution over long reaches, an industrial robot or a specialized motion platform may be more appropriate. Technical evaluators should resist forcing a collaborative robot into an application just because the safety model or footprint is attractive. The cost of misfit can exceed the savings from easier deployment.
For engineering teams building qualification standards, the most defensible answer is this: cobot repeatability claims are useful, but rarely sufficient on their own for precision tasks. The decision should come from application-specific benchmarking, system-level tolerance analysis, and transparent supplier documentation. That is how nominal precision becomes decision-grade precision.
TechStat Vanguard supports evaluators who need engineering clarity rather than marketing shorthand. If your team is comparing cobot platforms, reviewing collaborative robots repeatability benchmarks, or drafting supplier acceptance criteria for a precision application, contact us to discuss a data-driven evaluation framework, request a tailored benchmark checklist, or explore deeper hard-tech sourcing insights.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Sep 29, 2026ISO 9283 Repeatability: How to Evaluate Cobot Positioning PerformanceISO 9283 cobot repeatability explained: learn how payload, reach, approach direction, and test conditions affect positioning performance and cell capability.Chen Wei (Automation Lead Engineer)
 Sep 28, 2026Spindle Runout Measurement in Germany: DIN Standards, Methods, and Acceptance LimitsSpindle runout measurement Germany: explore DIN standards, proven methods, acceptance limits, and audit-ready practices for reliable machining quality.Dr. Marcus Vance
 Sep 27, 2026How to Select Wall-Mount Edge Devices for Space-Constrained Factory NetworksWall mount edge devices for space-constrained factories: evaluate workload, thermal design, power resilience, cable access, and network reliability for smarter deployments.TSV Data Lab
 Sep 26, 2026Machining Tolerance Analysis: How to Set Limits That Meet Function and Cost TargetsMachining tolerance analysis: learn how to set functional limits, control tolerance stacks, reduce inspection risk, and balance precision with production cost.Dr. Marcus Vance
 Sep 25, 2026How to Evaluate an Industrial Infrastructure Data Platform for Multi-Site OperationsIndustrial infrastructure data platform evaluation guide for multi-site operations: compare data quality, edge resilience, interoperability, governance, and scalable proof-of-value criteria.Victor Lin (Chief Software Architect)
 Sep 24, 2026How to Select Machine Vision Optics for Accurate Inspection at Different Working DistancesMachine vision optics selection guide for accurate inspection at every working distance. Compare FOV, pixel scale, DOF, distortion, lighting, and telecentric options.TSV Data Lab
 Sep 23, 2026How to Evaluate a Machine Vision System Integrator for High-Speed Inspection LinesChoose a machine vision system integrator with proven expertise in high-speed inspection, reliable reject timing, robust optics, and measurable acceptance criteria.TSV Data Lab
 Sep 28, 2026When is a SCADA API the right choice for connecting plant systems?SCADA API guide: learn when governed plant data integration improves traceability, security, and scalability—without compromising real-time control.Victor Lin (Chief Software Architect)
 Sep 27, 2026How SCADA data integration improves traceability across production linesSCADA data integration connects production-line data to improve traceability, accelerate quality investigations, and strengthen safety decisions.Victor Lin (Chief Software Architect)
 Sep 26, 2026What to define before starting SCADA integration planningSCADA integration planning starts with clear scope, control boundaries, data models, cybersecurity, and testing. Discover the definitions that reduce risk and costly rework.Victor Lin (Chief Software Architect)
 Sep 25, 2026How a smart factory with Industrial IoT reduces production blind spotsDiscover how a smart factory with Industrial IoT turns real-time machine, quality, and workflow data into actionable insights that reduce production blind spots and delivery risks.Victor Lin (Chief Software Architect)
 Sep 24, 2026When does Industrial IoT make smart manufacturing easier to scale?Smart manufacturing Industrial IoT scales when trusted data, interoperable systems, and secure workflows turn connected assets into measurable gains.TSV Data Lab
 Sep 23, 2026What drives ultra-precision machining cost at 1-micron tolerance?Ultra precision machining cost per part at 1 micron tolerance depends on process, material, metrology, and yield. Learn how to compare quotes confidently.Dr. Marcus Vance
 Sep 22, 2026Drone Engine-T550CC Applications: Build the UAV Power System Around the MissionAn application guide for Drone Engine-T550CC integration, covering payload planning, airframe matching, cooling, fuel, vibration, test procedures, documentation, and service preparation.Elena Rostova (UAV Systems Researcher)
 Sep 22, 2026How to Evaluate Industrial Edge Computing Vendors for Factory DeploymentIndustrial edge computing vendor evaluation guide for factories: compare latency, protocol fit, reliability, security, and lifecycle support before deployment.TSV Data Lab
 Sep 21, 2026Drone Payload Integration: Matching Power, Data, and Center of Gravity for Reliable FlightsDrone payload integration made practical: balance power, data, center of gravity, and endurance to build safer, more reliable mission-ready flights.Elena Rostova (UAV Systems Researcher)
 Sep 20, 2026Autonomous Navigation Pricing: Cost Drivers and Budget Benchmarks for AMR ProjectsAutonomous navigation price explained: compare AMR cost drivers, software, sensors, integration, safety, and lifecycle budgets to build a scalable project plan.Chen Wei (Automation Lead Engineer)























