
Repeatability Benchmarks That Mislead Cobot Selection
Publication Date
author
Procurement teams often rely on collaborative robots repeatability benchmarks as a shortcut for comparing cobots, yet those headline numbers rarely predict deployment success on their own. The core search intent behind this topic is practical: buyers want to know whether published repeatability figures are trustworthy, what they actually mean in production, and how to avoid choosing the wrong robot based on an impressive but incomplete spec.
For procurement readers, the real concern is not academic metrology. It is commercial risk. A cobot with a tighter quoted repeatability value may still create integration delays, fixture redesign costs, process instability, or unexpected maintenance overhead. The most helpful answer, therefore, is not a generic explanation of repeatability. It is a decision framework that separates marketing shorthand from engineering-relevant buying criteria.
In practice, the most valuable content for this audience includes: how repeatability is measured, why test conditions matter, which adjacent metrics affect actual application performance, where suppliers can present numbers that are technically correct but commercially misleading, and how buyers can compare systems using a more complete sourcing checklist. That is where this article focuses.
Why published repeatability numbers can mislead cobot selection
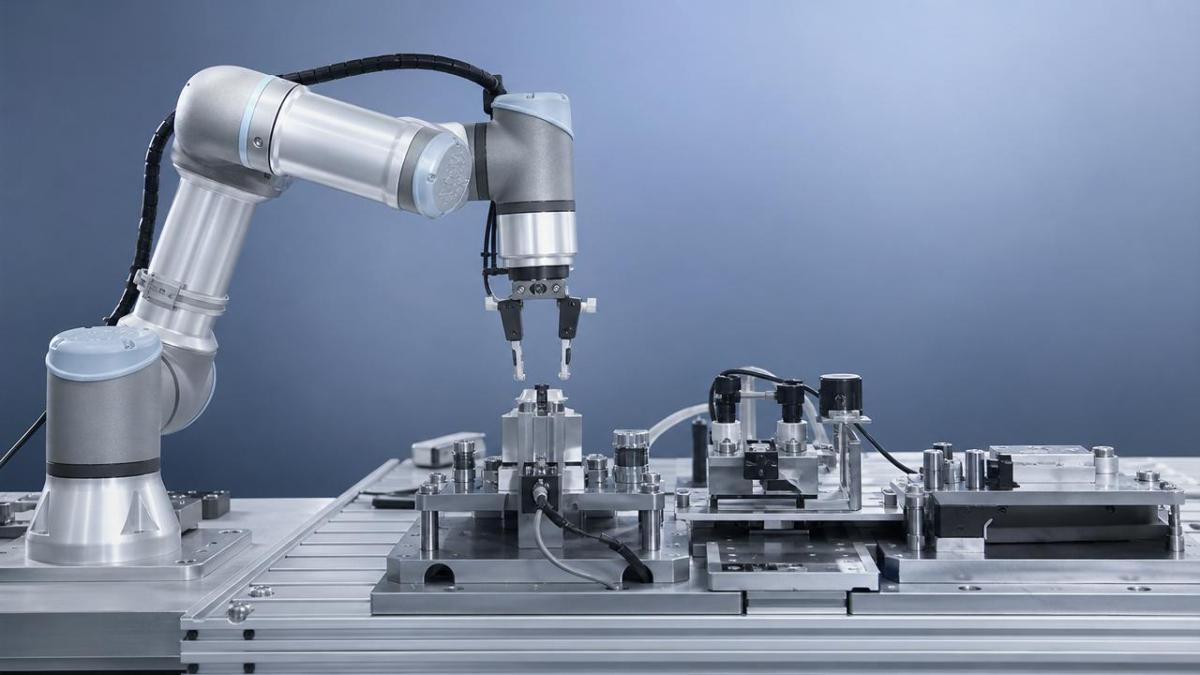
Repeatability is an important metric, but it is not the same as accuracy, process capability, or application success. A cobot may return to the same taught point consistently under a controlled test and still perform poorly in a real production cell. For procurement teams, that distinction matters because most vendor datasheets present repeatability as if it were a universal proxy for precision.
In simple terms, repeatability describes how consistently the robot can return to a programmed position under defined conditions. It does not automatically tell you whether the robot will hit the correct absolute position after relocation, maintain path quality during dynamic motion, compensate for payload variation, or hold performance after months of thermal cycling and wear.
That gap between the spec sheet and the shop floor is where many sourcing mistakes happen. Buyers often compare one cobot listed at ±0.02 mm with another listed at ±0.04 mm and assume the first machine is the better engineering choice. In reality, the second robot may deliver a more stable process if its controller, stiffness, calibration routine, tool integration, and support ecosystem fit the task better.
This is why collaborative robots repeatability benchmarks should be treated as one data point, not the decision itself. When procurement uses repeatability as a shortcut, it can overweight a clean number and underweight the conditions that produce real-world output quality, line uptime, and total cost of ownership.
What procurement teams are really trying to reduce
Most procurement decisions in robotics are framed as a price-versus-performance comparison, but that is only part of the story. The deeper objective is to reduce uncertainty. Buyers want to avoid three expensive outcomes: buying a robot that cannot hold the process window, buying a robot that requires hidden integration work, or buying a robot that looks economical until support, downtime, and engineering modifications are included.
From that perspective, repeatability benchmarks matter because they appear to simplify technical risk. A single small number feels objective, comparable, and easy to defend internally. It helps with vendor shortlisting, management presentations, and initial technical scoring. The problem is that the number often arrives stripped of context.
Procurement teams typically care about questions such as: Will this cobot meet cycle and quality targets in our application? How sensitive is performance to payload, speed, mounting orientation, and ambient conditions? How much commissioning effort will be required? What happens when operators change grippers, fixtures, or part variants? How often will recalibration or service intervention be needed?
Those are smarter buying questions than “Which robot has the best repeatability spec?” Because in operations, the commercial consequence is not missing a brochure metric. It is missing production output, customer quality requirements, and ROI assumptions.
How repeatability is measured—and where comparisons break down
One reason collaborative robots repeatability benchmarks mislead selection is that many buyers assume all suppliers measure repeatability in the same way. They often do not. Even when vendors reference recognized testing methods, test setup choices can materially affect the final value presented in the datasheet.
Variables may include payload percentage, arm extension, path direction, speed, acceleration, mounting method, end-effector mass distribution, ambient temperature, and the exact number of measurement cycles. A robot tested with a light payload near an ideal posture can appear more repeatable than it would be in a long-reach dispensing or screwdriving application.
Another issue is that repeatability often reflects point-to-point behavior, not process behavior. For example, welding, gluing, polishing, vision-guided picking, and force-sensitive assembly depend on more than returning to one static point. They depend on path smoothness, vibration control, compliance behavior, controller tuning, and interaction with external equipment.
There is also a difference between a lab benchmark and a production benchmark. In a controlled environment, floor vibration may be low, thermal drift minimal, fixtures stable, and maintenance conditions ideal. On the shop floor, the cobot may be mounted on a mobile stand, adjacent to other machinery, or tasked with frequent part changeovers. If your sourcing model ignores that context, repeatability numbers become less predictive.
Procurement should therefore ask every supplier the same basic question: under what exact conditions was this repeatability figure obtained, and how close are those conditions to our use case? Without that answer, direct comparison is weak.
Repeatability is not accuracy, and buyers often pay for the confusion
One of the most common sourcing errors is conflating repeatability with accuracy. Repeatability means the robot returns to the same point consistently. Accuracy means it reaches the intended true point in space. A cobot can be highly repeatable and still be offset from the desired position if calibration, base definition, tooling, or kinematic compensation are not managed properly.
Why does that matter commercially? Because some applications can tolerate a consistent offset that is corrected through teaching or fixture design, while others cannot. If the robot is moved between stations, redeployed across product lines, or used with vision systems requiring coordinate alignment, poor absolute accuracy can increase setup time and engineering labor.
For procurement teams, this means the “best” repeatability number does not automatically produce the lowest implementation cost. If one vendor offers stronger calibration tools, better frame management, easier TCP setup, and better support for vision or force control, that platform may outperform a nominally tighter robot in practical deployment speed and process reliability.
In other words, a spec can be true and still be misleading. The purchasing error occurs when a valid technical metric is treated as a complete buying answer.
The metrics that usually matter more in real applications
If repeatability should not dominate cobot selection, what should procurement evaluate alongside it? The answer depends on the process, but several metrics often predict performance better than a standalone repeatability benchmark.
Payload behavior under full working conditions is critical. Many cobots show acceptable results with modest loads, but application performance changes when the gripper, tooling, cable dress package, and workpiece approach the upper payload range. Ask for performance evidence at your actual payload, not just rated capacity.
Reach-dependent stiffness also matters. A robot can behave differently at compact postures versus near full extension. For machine tending, palletizing, dispensing, and screwdriving, deflection and stability at the edge of the workspace can affect quality more than brochure repeatability.
Path accuracy and motion smoothness are often more relevant than point repeatability for process applications. Bonding, polishing, inspection, and welding require controlled continuous motion. A robot that is “repeatable” at taught points but unstable during trajectory execution may create scrap or rework.
Cycle-time consistency is another underappreciated metric. Procurement usually reviews maximum speed, but operations suffer more from variation than from slightly slower nominal performance. If the controller throttles motion under certain loads or safety modes, throughput projections may fail.
Thermal stability and drift behavior should be considered for precision work. Some systems change behavior as joints warm up or as the environment shifts. A vendor willing to discuss thermal compensation, warm-up requirements, and long-duration performance is often more credible than one that only quotes a single static value.
Controller ecosystem and integration maturity may produce the largest practical difference of all. Vision libraries, fieldbus support, programming model, diagnostics, remote support, and tool compatibility can determine whether the cell launches in weeks or stalls in commissioning.
Application-specific reality: when repeatability matters a lot, and when it matters less
Procurement should not swing to the opposite extreme and ignore repeatability. It still matters. The key is to weight it according to the application rather than using it as a universal ranking tool.
For precision assembly, small-part insertion, electronics handling, or metrology-adjacent tasks, repeatability can be highly relevant, especially when tolerances are narrow and fixtures are unforgiving. In such cases, benchmark quality, calibration options, compliance control, and end-of-arm tooling all need close review.
For palletizing, simple pick-and-place, machine tending with generous fixture tolerance, or packaging tasks, ultra-tight repeatability may provide little business advantage once the process threshold is already met. Buying excess precision here can mean paying for capability that never converts into higher output or lower defect rates.
For vision-guided applications, the interaction between robot performance, camera calibration, lighting, and software compensation often matters more than brochure repeatability alone. A robot with average headline metrics but superior integration tools can outperform a tighter robot in overall cell performance.
For force-controlled operations such as sanding, polishing, insertion, or deburring, compliance behavior and control response may be more decisive than point repeatability. That is why process context must drive sourcing criteria.
How vendors make repeatability look stronger than your use case
Not all misleading benchmarks are dishonest. Some simply reflect best-case engineering conditions that buyers fail to interrogate. Still, procurement should recognize the common presentation patterns that make cobot specs look more favorable than field reality.
First, vendors may publish the smallest number achieved under ideal load and posture conditions, while your application uses larger moments, off-center mass, or extended reach. Second, the benchmark may not reflect the actual end-of-arm tooling package, which can introduce vibration, cable drag, or inertia effects.
Third, performance may be shown without discussing mounting rigidity. A cobot on a rigid industrial base can behave very differently from the same robot on a lightweight cart or a shared workstation frame. Fourth, repeatability may be emphasized to shift attention away from weaker areas such as software limitations, service footprint, or path quality.
Finally, some comparisons are distorted by selective competitor framing. One robot may be compared on repeatability, another on payload, another on speed, without equalized test conditions. Procurement should be wary of any sales narrative that compares unlike conditions while implying engineering equivalence.
A better procurement framework for collaborative robot evaluation
The strongest sourcing approach is to use collaborative robots repeatability benchmarks as a screening input, then move quickly to application-based validation. Instead of asking which cobot is “most repeatable,” ask which cobot can hold your actual process window with the lowest implementation and lifecycle risk.
Start with a requirement matrix. Define tolerance needs, payload including tooling, reach envelope, mounting orientation, speed targets, quality thresholds, environmental conditions, safety architecture, communication protocols, and changeover frequency. Then map each vendor’s claims against those conditions.
Next, require benchmark transparency. Ask suppliers for the test standard used, the payload level, reach position, cycle count, environmental conditions, and whether the figure reflects bare arm performance or application-level setup. If they cannot explain the number clearly, treat the spec cautiously.
Then request a proof-of-application, not just a demo. A generic showroom pick-and-place routine offers limited procurement value. What matters is your part, your tooling, your cycle logic, and your tolerance band. A short, structured application trial often reveals more than multiple rounds of brochure comparisons.
Procurement should also score integration friction. Evaluate software usability, training burden, end-effector compatibility, field service reach, spare parts availability, and local applications engineering support. These factors frequently outweigh a marginal spec advantage in repeatability.
Finally, model total cost of ownership over the expected life of the cell. Include commissioning effort, external sensors, fixturing changes, maintenance intervals, downtime exposure, vendor support responsiveness, and redeployment flexibility. A robot that looks technically superior in a narrow metric can become the more expensive asset over time.
Questions procurement should ask before accepting any repeatability claim
A disciplined buying team can avoid most benchmark traps by asking a short set of direct questions during supplier evaluation.
What test method was used to establish the published repeatability value? At what payload, speed, reach, and mounting condition was it measured? How does performance change at maximum practical reach and near rated payload? What evidence do you have from comparable applications in the field? How much drift occurs over a shift or after thermal warm-up?
Also ask whether the value represents robot-only performance or full-cell performance with tooling. How frequently is recalibration required in real deployments? What support exists for offline programming, vision, force control, and frame management? What is the expected commissioning timeline for an application similar to yours?
These questions do two things. They improve your technical understanding, and they test supplier maturity. Vendors that can answer precisely tend to be more reliable partners than those who rely on broad marketing statements.
Conclusion: buy process capability, not just a benchmark number
The main takeaway is simple: collaborative robots repeatability benchmarks are useful, but they are often overvalued in procurement decisions. A tight repeatability number can indicate good potential, yet it does not guarantee process capability, low integration risk, or favorable total cost of ownership.
For procurement teams, the better strategy is to treat repeatability as a starting filter, then evaluate the conditions behind the metric, the application context, and the broader performance system around the robot. Accuracy, stiffness, path quality, thermal behavior, controller maturity, service support, and proof-of-application usually tell you more about whether the cobot will succeed in your factory.
In hard-tech sourcing, the safest decisions come from engineering context, not headline specs. When buyers shift from comparing isolated brochure numbers to validating process-fit performance, cobot selection becomes more defensible, more predictable, and far less vulnerable to misleading benchmarks.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Sep 29, 2026ISO 9283 Repeatability: How to Evaluate Cobot Positioning PerformanceISO 9283 cobot repeatability explained: learn how payload, reach, approach direction, and test conditions affect positioning performance and cell capability.Chen Wei (Automation Lead Engineer)
 Sep 28, 2026Spindle Runout Measurement in Germany: DIN Standards, Methods, and Acceptance LimitsSpindle runout measurement Germany: explore DIN standards, proven methods, acceptance limits, and audit-ready practices for reliable machining quality.Dr. Marcus Vance
 Sep 27, 2026How to Select Wall-Mount Edge Devices for Space-Constrained Factory NetworksWall mount edge devices for space-constrained factories: evaluate workload, thermal design, power resilience, cable access, and network reliability for smarter deployments.TSV Data Lab
 Sep 26, 2026Machining Tolerance Analysis: How to Set Limits That Meet Function and Cost TargetsMachining tolerance analysis: learn how to set functional limits, control tolerance stacks, reduce inspection risk, and balance precision with production cost.Dr. Marcus Vance
 Sep 25, 2026How to Evaluate an Industrial Infrastructure Data Platform for Multi-Site OperationsIndustrial infrastructure data platform evaluation guide for multi-site operations: compare data quality, edge resilience, interoperability, governance, and scalable proof-of-value criteria.Victor Lin (Chief Software Architect)
 Sep 24, 2026How to Select Machine Vision Optics for Accurate Inspection at Different Working DistancesMachine vision optics selection guide for accurate inspection at every working distance. Compare FOV, pixel scale, DOF, distortion, lighting, and telecentric options.TSV Data Lab
 Sep 23, 2026How to Evaluate a Machine Vision System Integrator for High-Speed Inspection LinesChoose a machine vision system integrator with proven expertise in high-speed inspection, reliable reject timing, robust optics, and measurable acceptance criteria.TSV Data Lab
 Sep 28, 2026When is a SCADA API the right choice for connecting plant systems?SCADA API guide: learn when governed plant data integration improves traceability, security, and scalability—without compromising real-time control.Victor Lin (Chief Software Architect)
 Sep 27, 2026How SCADA data integration improves traceability across production linesSCADA data integration connects production-line data to improve traceability, accelerate quality investigations, and strengthen safety decisions.Victor Lin (Chief Software Architect)
 Sep 26, 2026What to define before starting SCADA integration planningSCADA integration planning starts with clear scope, control boundaries, data models, cybersecurity, and testing. Discover the definitions that reduce risk and costly rework.Victor Lin (Chief Software Architect)
 Sep 25, 2026How a smart factory with Industrial IoT reduces production blind spotsDiscover how a smart factory with Industrial IoT turns real-time machine, quality, and workflow data into actionable insights that reduce production blind spots and delivery risks.Victor Lin (Chief Software Architect)
 Sep 24, 2026When does Industrial IoT make smart manufacturing easier to scale?Smart manufacturing Industrial IoT scales when trusted data, interoperable systems, and secure workflows turn connected assets into measurable gains.TSV Data Lab
 Sep 23, 2026What drives ultra-precision machining cost at 1-micron tolerance?Ultra precision machining cost per part at 1 micron tolerance depends on process, material, metrology, and yield. Learn how to compare quotes confidently.Dr. Marcus Vance
 Sep 22, 2026Drone Engine-T550CC Applications: Build the UAV Power System Around the MissionAn application guide for Drone Engine-T550CC integration, covering payload planning, airframe matching, cooling, fuel, vibration, test procedures, documentation, and service preparation.Elena Rostova (UAV Systems Researcher)
 Sep 22, 2026How to Evaluate Industrial Edge Computing Vendors for Factory DeploymentIndustrial edge computing vendor evaluation guide for factories: compare latency, protocol fit, reliability, security, and lifecycle support before deployment.TSV Data Lab
 Sep 21, 2026Drone Payload Integration: Matching Power, Data, and Center of Gravity for Reliable FlightsDrone payload integration made practical: balance power, data, center of gravity, and endurance to build safer, more reliable mission-ready flights.Elena Rostova (UAV Systems Researcher)
 Sep 20, 2026Autonomous Navigation Pricing: Cost Drivers and Budget Benchmarks for AMR ProjectsAutonomous navigation price explained: compare AMR cost drivers, software, sensors, integration, safety, and lifecycle budgets to build a scalable project plan.Chen Wei (Automation Lead Engineer)























