How Do You Measure a Machine Vision System's False Reject Rate?
Publication Date
author
How Do You Measure a Machine Vision System's False Reject Rate?
Every good part incorrectly rejected by an automated inspection system creates avoidable scrap, rework, or review costs—but measuring that loss requires more than counting rejects. The machine vision false reject rate is the percentage of independently verified acceptable parts that the system incorrectly rejects under defined test conditions. For engineers and procurement teams, a defensible benchmark starts with reliable ground truth, representative production samples, and clear acceptance criteria.
The calculation is straightforward. The difficult work is establishing which parts are genuinely acceptable, whether the test represents production, and how much confidence the result deserves. A low number from a curated demonstration is not necessarily a low number on a running line.
Start with the right denominator
False reject rate (%) = acceptable parts incorrectly rejected ÷ all independently verified acceptable parts tested × 100.
The denominator includes both acceptable parts that passed and acceptable parts that failed inspection. It does not include defective parts. Nor is it limited to the contents of the reject bin.
For a hypothetical calculation, suppose a validation run contains 10,000 independently verified acceptable parts, and the system rejects 40 of them. The false reject rate is 0.4%. This is an arithmetic example, not a claimed industry benchmark or supplier result.
Total rejection rate answers a different question: what fraction of all inspected parts was rejected? It combines correct and incorrect rejections. Reviewing only rejected parts can establish what share of that bin is actually good, but that percentage is not the false reject rate. You still need the total number of acceptable parts in the evaluated population.
Terminology also varies. Some software treats “defective” as the positive class, making a false rejection a false positive. Other systems use the opposite convention. In test reports, plain-language labels are safer than unexplained FP or FN abbreviations.
Ground truth must be independent of the vision system
A vision system cannot validate itself. Its classifications need comparison against an independent reference appropriate to the inspected characteristic: calibrated dimensional measurement, microscopy, functional testing, or a documented visual standard with qualified reviewers.
Define acceptable before collecting results. For a machined component, this may mean a drawing tolerance and an agreed measurement method. For packaging, it may involve print legibility, label position, or seal appearance. Cosmetic inspection needs especially careful boundary definitions; “looks wrong” is not a reproducible acceptance criterion.
Where human judgment supplies the reference, reviewers should ideally be blinded to the machine decision. Otherwise, a reject label can influence their assessment. Disagreements should follow a predefined adjudication process rather than being resolved in whichever way improves the system's reported score.
Near a specification limit, reference measurement uncertainty matters. Establish a decision rule for borderline parts and record unresolved classifications. Do not silently remove difficult samples. If they cannot be classified confidently, report their number and explain how their exclusion limits the benchmark.
Build a test that resembles the line—not the demonstration
A tray of clean, centrally positioned parts can establish basic capability. It cannot establish production performance. A useful validation set includes acceptable variation that the process actually permits: surface finish differences, material lots, cavity variation, part orientation, and legitimate dimensional values near acceptance limits.
Use two complementary sample groups. A production-representative sample estimates routine performance. A challenge set deliberately includes difficult but acceptable parts and relevant defects. Keep their results distinguishable: an enriched challenge set is useful for exposing weaknesses, but its pooled rate may not represent the normal production mix.
A practical validation sequence is:
- Assign traceable part identifiers and establish independent reference labels.
- Separate setup and tuning samples from the final evaluation set.
- Freeze the inspection recipe, model version, optics, lighting, and decision thresholds.
- Run at specified production speeds and record decisions against part identifiers.
- Reconcile machine results with reference labels, including missing images and no-decisions.
- Report aggregate results and results by relevant operating condition.
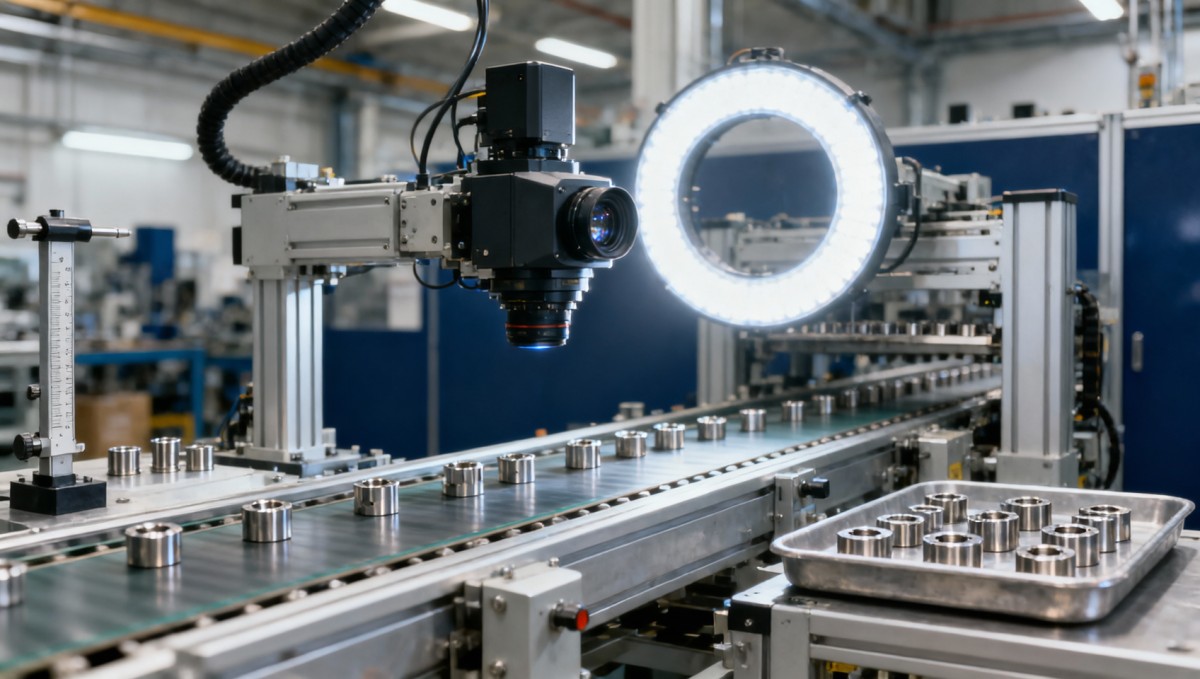
Testing the same part repeatedly helps assess repeatability, but those passes are not equivalent to independent parts. A thousand images of a few easy components provide weak evidence about variation across a thousand different components. Report unique-part counts separately from inspection-cycle counts.
Avoid tuning on the final evaluation set. Once its failures influence threshold changes or model retraining, it has become development data. Confirm the revised configuration on a fresh held-out set.
Report uncertainty, especially when no false rejects appear
An observed rate is an estimate, not a guarantee. Always report the false rejection count, acceptable-part denominator, and confidence interval. “Zero false rejects” without a sample size tells a buyer very little.
For zero observed events in independent trials with a consistent underlying probability, the statistical “rule of three” gives an approximate one-sided 95% upper bound of 3/n. Zero false rejects among 300 acceptable parts therefore suggests an upper bound near 1%, not proof that the true rate is zero. Demonstrating an upper bound near 0.1% requires roughly 3,000 acceptable parts with zero events under those assumptions.
When false rejects occur, use an appropriate binomial interval, such as a Wilson or exact interval. If results cluster by batch, shift, or repeated part, a simple independent-trial model may understate uncertainty. The sampling design and statistical treatment should account for that dependence.
Set the acceptance rule before testing. A requirement based on an upper confidence bound is more demanding than one based only on the observed percentage. Neither is universally correct; the choice depends on production economics, defect consequences, and the evidence required for qualification.
Separate classification errors from handling failures
A good part in the reject bin does not automatically mean the image classifier made a mistake. The camera may have accepted it while an incorrectly timed ejector removed it. Conversely, the software may reject a part that the handling system fails to divert.
Measure the image-decision false reject rate and the end-to-end good-part diversion rate separately. Both affect operations, but they point to different corrective actions. Traceability between trigger, image, decision, encoder position, and physical disposition is what makes this distinction possible.
No-read, timeout, and missing-image events also need explicit treatment. If the line automatically diverts these parts, count verified good parts among them in the operational loss metric while reporting the event category separately. Excluding them from classifier statistics may be reasonable, provided the exclusion is visible and does not conceal production losses.
Useful diagnostic records include exposure settings, illumination configuration, inspection scores, failure reasons, recipe versions, and line speed. Segment results by product variant and operating condition. An acceptable average can hide a persistent problem with one finish, one cavity, or one shift.
A lower false reject rate can hide a worse inspection system
Relaxing a decision threshold may recover acceptable parts while allowing defects through. Compare the machine vision false reject rate alongside the false acceptance rate: defective parts accepted divided by all independently verified defective parts tested.
Defective samples should cover relevant failure modes and severity levels, not just obvious defects. Results from grossly damaged parts do not establish sensitivity to a subtle crack, marginal print defect, or small assembly error. Where consequences differ, report detection performance by defect type rather than relying on a single average.
Before changing thresholds, inspect the imaging chain. Glare can obscure surface features; motion blur can reduce edge contrast; fixture variation can shift the inspection region. Better lighting geometry, exposure control, or positioning may reduce false rejects without sacrificing defect detection. Threshold relaxation cannot recover information that the image never captured.
Turn the benchmark into a qualification requirement
There is no universal acceptable false reject rate across manufacturing. A recoverable diversion to manual review has different economics from scrapping a finished precision assembly. Estimate the burden using expected acceptable-part volume, the measured rate, and the actual disposition cost—including review labor, handling, reinspection, and unrecoverable material loss.
For supplier comparisons, require the same part populations, reference criteria, throughput, and statistical acceptance rules. Request the underlying counts and configuration records, not just a percentage. Laboratory image replay is useful for algorithm comparisons, but installed-line qualification must also exercise acquisition, triggering, and rejection hardware.
This is consistent with TechStat Vanguard's approach to engineering benchmarking: replace broad performance claims with traceable parameters and reproducible evidence. “Engineering Truth Through Data” means asking what was measured, under which conditions, and with what uncertainty—not treating a polished demonstration as qualification.
Before signing off, document the allowed false reject rate, missed-defect limits, sample requirements, and change-control rules. Revalidation should be considered when material, optics, lighting, models, or production speed change. The number worth trusting is the one tied to a defined configuration and a test that represents the parts your line will actually inspect.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Oct 24, 2026Guotai Haitong: Global Entry-Level 3D Printer Shipments Rose 39% in Q1 2026Entry-level 3D printer shipments rose 39% in Q1 2026, Guotai Haitong reports. Explore how AI, multicolor printing and print farms are shaping market growth.Dr. Marcus Vance
 Oct 24, 2026Choosing an Industrial Vision Inspection Supplier: Acceptance Tests That MatterChoose an industrial vision inspection supplier with confidence. Discover acceptance tests for defect detection, false rejects, production speed, and reliable part rejection before you buy.TSV Data Lab
 Oct 23, 2026US Navy Raises Gecko Robotics Contract Ceiling to $300M for Robotic Fleet MaintenanceUS Navy raises Gecko Robotics’ contract ceiling to $300M for Pacific Fleet robotic inspections. Explore potential opportunities for maintenance suppliers and key procurement considerations.Chen Wei (Automation Lead Engineer)
 Oct 23, 2026Choosing Industrial Sensing Systems for Global Plants: Protocol CompatibilityCompare industrial sensing systems international buyers can trust. Explore protocol compatibility, reduce integration risks, and select proven configurations for reliable global plant deployments.TSV Data Lab
 Oct 22, 2026KUKA Showcases Physical AI and iiQKA.AI Vision at NVIDIA GTC BerlinExplore KUKA’s Physical AI showcase at NVIDIA GTC Berlin and discover how iiQKA.AI Vision aims to simplify robotic vision integration and improve 2D and 3D scene recognition.TSV Data Lab
 Oct 22, 2026Robotic Machining of Advanced Composites: What Tolerances Are Achievable?Explore advanced materials machining robotics: discover what drives achievable composite tolerances and how to validate accuracy before investing in your next machining system.Dr. Marcus Vance
 Oct 21, 2026China’s Industrial Robot Exports Near RMB 10 Billion in First Nine Months of 2026China’s industrial robot exports neared RMB 10 billion in January–September 2026, with value rising faster than volume. Explore the data and what it could mean for suppliers.Chen Wei (Automation Lead Engineer)
 Oct 21, 2026Low-Latency Industrial Data Processing: Pricing and Key Cost DriversExplore industrial data latency price drivers, from edge hardware to integration and support. Learn how to compare quotes, verify performance, and avoid unnecessary costs.TSV Data Lab
 Oct 20, 2026KUKA Launches iiQKA.AI Vision to Simplify Industrial Image ProcessingKUKA iiQKA.AI Vision simplifies industrial image processing with controller-based 2D and 3D vision. Explore drag-and-drop setup for vision-guided automation.TSV Data Lab
 Oct 20, 2026Smart Industrial Edge Devices: Key Criteria for Legacy PLC IntegrationChoose smart industrial edge devices for legacy PLC integration. Discover key criteria for compatibility, data quality, security, and reliable collection without disrupting control.TSV Data Lab
 Oct 19, 2026Choosing a Radar Sensor by Application: Range, Resolution, and Field of ViewSimplify radar sensor application based product selection. Compare range, resolution, and field of view to avoid blind spots and choose with confidence. Explore the guide.TSV Data Lab
 Oct 18, 2026Comparing Material Options for Procurement: Specs, Costs, and Supply RisksExplore procurement oriented technical content on material options, specs, costs, and supply risks. Compare alternatives to cut hidden expenses and make confident sourcing decisions.Dr. Marcus Vance
 Oct 17, 20265-Axis CNC Positioning Accuracy: How to Interpret ISO 230-2 Test ResultsAssess 5 axis CNC machining positioning accuracy with ISO 230-2. Learn to interpret repeatability, reversal error, and test conditions to compare suppliers and make confident acceptance decisions.Dr. Marcus Vance
 Oct 16, 2026Choosing a Rugged Edge AI Box Supplier: Thermal Tests and Lifecycle SupportChoose a rugged edge AI box supplier with proven thermal performance and reliable lifecycle support. Discover the tests and commitments to verify before you buy.TSV Data Lab
 Oct 15, 2026R&D Cost Reduction Services: How to Evaluate Fees, Savings, and ROIEvaluate R&D cost reduction services with confidence. Compare fees, verify savings, and calculate ROI without compromising performance. Discover how to choose a provider that delivers real value.Chen Wei (Automation Lead Engineer)
 Oct 24, 2026How Do You Measure a Machine Vision System's False Reject Rate?Measure machine vision false reject rate with the right formula, independent ground truth, and confidence intervals. Learn how to validate performance and reduce costly good-part losses.TSV Data Lab
 Oct 23, 2026How Do You Evaluate Solid-State LiDAR Point Cloud Density?Evaluate solid-state LiDAR point cloud density using valid returns, angular spacing, and real-world coverage. Discover how to compare sensors and choose the right fit for your application.TSV Data Lab