
Why vision inspection software misses rare defects
Publication Date
author
Why does vision based quality inspection software still miss rare defects even in highly automated lines? For engineers, buyers, and plant leaders, the issue goes beyond model accuracy into data scarcity, edge ai inference latency industrial constraints, opc ua server response time, and mes integration with sap erp. This article explains where failures emerge, how to verify them with engineering data, and what to ask before investing in machine vision software.
In real factories, a missed defect is rarely caused by one bad algorithm alone. It is more often the result of a chain: limited defect samples, unstable lighting, camera-to-PLC timing gaps, compressed inference cycles at the edge, and weak feedback loops between quality systems and production systems. Rare defects expose the gap between demo performance and production performance.
For procurement teams and decision-makers, this matters because machine vision software is increasingly evaluated as part of a broader automation stack, not as an isolated tool. A system that performs at 99.5% on common defects can still create high downstream cost if it misses the 0.05% anomaly that triggers recalls, field failures, or rework across multi-site production.
Consistent with TechStat Vanguard’s engineering-first perspective, the right question is not whether a supplier claims “high accuracy.” The right question is which defect classes were validated, under what cycle time, with what latency budget, on what data distribution, and how the result is tied into MES, ERP, and traceability workflows.
Rare defects are statistical outliers, not routine vision tasks
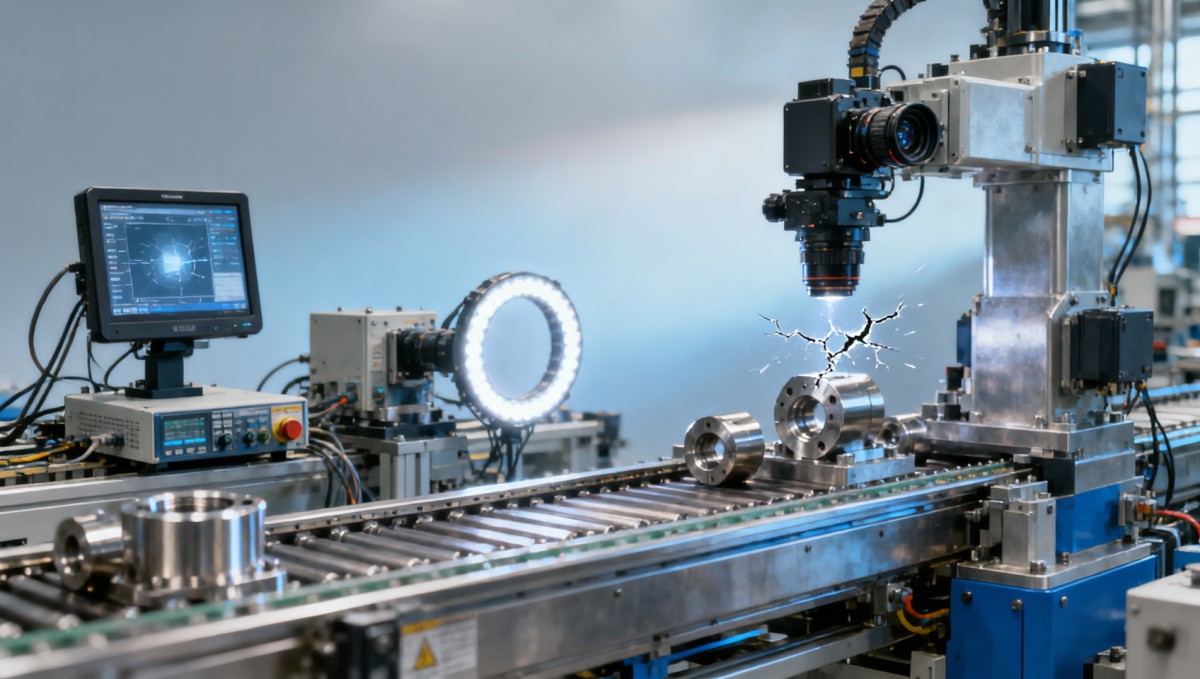
Most vision inspection software is optimized around frequent, repeatable patterns. In production, however, rare defects are low-frequency events that may appear once in 10,000 parts, once per shift, or only under a narrow process drift window such as a 3°C thermal rise, a tooling wear threshold, or a lot-specific material variation. This makes them fundamentally different from common scratches, missing features, or basic dimensional errors.
A model trained on 50,000 normal images and 300 common defect images may still be weak on a defect class represented by only 12 verified samples. Even with augmentation, synthetic replication does not always capture the physical signature of true anomalies such as micro-cracks, specular contamination, fiber pull-out, void edge blur, or intermittent solder wetting irregularities.
Another issue is class imbalance. If the defect prevalence is 0.01% to 0.1%, a model can post excellent overall accuracy while still failing where quality risk lives. Plant managers should therefore monitor recall, false-negative rate, and confidence distribution by defect subtype, not only top-line pass/fail accuracy.
In sectors ranging from precision machining to electronics assembly and aerospace subcomponents, the commercial impact is uneven. Missing one burr on a cosmetic part is not the same as missing one porosity signature in a safety-critical component. Inspection software must therefore be validated against severity-weighted defect taxonomy, not a single blended metric.
Why production data differs from pilot data
Pilot projects often run for 2 to 6 weeks in controlled conditions, with cleaned optics, stable operators, and selected SKUs. Production runs for 24/7 cycles, shift changes, lens contamination, fixture wear, conveyor vibration, and upstream process variation. Rare defects often emerge only after these variables interact over time.
This is why engineering teams should build a defect capture plan before deployment. A typical plan includes 4 layers: controlled defect library, live reject review, operator escalation workflow, and periodic model retraining based on verified field samples.
Core indicators to watch
- Defect prevalence per SKU or process step, for example 1 in 5,000 versus 1 in 50,000.
- False-negative rate on critical defects, ideally tracked by severity level 1, 2, and 3.
- Image drift across 30-day, 60-day, and 90-day windows.
- Sample verification cycle, such as whether quality engineers confirm suspicious images within 8 to 24 hours.
The table below shows why standard reporting can hide production risk when rare defects are grouped into generic performance summaries.
The key takeaway is simple: rare defect control requires distribution-aware validation. Buyers should ask for defect-level performance, not only aggregate numbers. That one change often separates marketing claims from engineering reality.
Where failures emerge in the real inspection stack
A vision inspection system is a chain of dependencies: optics, illumination, triggering, compute hardware, model runtime, PLC handshakes, OPC UA communication, data storage, and MES or ERP feedback. When rare defects are missed, the root cause may sit outside the model. In many lines, the defect image is never captured clearly enough for the software to decide correctly.
Edge AI inference latency is a common bottleneck. If the line takt time is 180 to 250 milliseconds per unit, but image preprocessing plus model inference plus PLC response consumes 220 milliseconds under peak load, the system may lower image resolution, skip secondary checks, or accept lower confidence thresholds to keep up. This creates blind spots exactly when product flow is fastest.
OPC UA server response time also matters more than many buyers expect. A 20 to 40 millisecond average response may sound acceptable, but intermittent spikes to 120 milliseconds can disrupt reject timing, serializer matching, or result logging. Rare defects are then not only missed visually; they may also be misattributed to the wrong part, batch, or carrier position.
MES integration with SAP ERP creates another failure mode. If inspection results are not written back with lot, machine, operator, and timestamp context, engineers lose the ability to trace defect recurrence patterns over 7-day or 30-day periods. Without that loop, software never improves because the plant cannot build a reliable retraining dataset tied to process events.
Four operational constraints that reduce detection reliability
- Lighting instability, including LED aging, angle drift, and reflection changes across matte versus glossy surfaces.
- Motion blur or positional variation when conveyors run above 0.5 to 1.2 meters per second without synchronized triggering.
- Compute throttling at the edge when a shared industrial PC handles inference, HMI tasks, and local storage simultaneously.
- Weak system integration, where defect events are stored as images but not connected to batch genealogy, maintenance logs, or ERP quality holds.
How different bottlenecks show up on the line
The table below maps common technical bottlenecks to what operators and engineers actually observe in production.
This is why TSV-style benchmarking should include end-to-end latency, not just model metrics. If a supplier cannot separate capture time, preprocessing time, inference time, handshake time, and result write-back time, the plant does not yet have an engineering-grade performance baseline.
A practical diagnostic sequence
- Verify whether the defect was optically visible in the raw image at full resolution.
- Measure total decision latency across 100 to 1,000 consecutive cycles, not only a single test run.
- Check whether reject timing aligns with conveyor position and serializer mapping.
- Review whether MES and SAP ERP preserve part identity, lot data, and image references for root-cause analysis.
How to validate machine vision software with engineering data
Validation should be built around operational risk, not brochure metrics. For rare defects, that means separate testing for known rare classes, unknown anomaly detection, environmental drift, and system latency. A credible factory acceptance plan often runs in 3 stages: controlled offline testing, shadow-mode production testing, and gated live release.
In the offline phase, teams should test at least 3 sample groups: normal production images, verified defect images, and hard negatives that visually resemble defects but are acceptable. This helps reveal whether the software is merely memorizing obvious patterns or can distinguish edge cases under realistic variation.
In shadow mode, the system runs without controlling rejection for 2 to 4 weeks while comparing software decisions against human inspectors and downstream inspection results. This phase is critical because many rare defects only emerge when the line reaches stable throughput, full SKU mix, and actual operator routines.
A mature validation plan also defines acceptance thresholds by defect severity. For example, a cosmetic anomaly may tolerate a higher false-positive rate, while a functional or safety-relevant defect may require extremely low false negatives, even if manual review is added for uncertain cases.
Recommended validation metrics for buyers and engineers
The following framework is more useful than generic “AI accuracy” claims because it links software performance to production control and supplier qualification.
A supplier that supports this level of validation is generally more prepared for real manufacturing deployment. If they only provide a single F1 score, without the underlying defect taxonomy and operating conditions, the buyer still lacks enough evidence for a capital decision.
Questions to include in a technical review
- How many verified samples exist for each critical rare defect, and how were they labeled?
- What is the end-to-end cycle time under peak load, for example at 85% to 95% line capacity?
- How is confidence handled: auto-reject, manual review, or hold-for-inspection?
- What retraining cadence is realistic, such as every 4 weeks, 8 weeks, or per process change event?
For procurement leaders, this transforms the buying process. Instead of comparing broad claims, you compare engineering evidence: defect coverage, validation design, integration depth, and operational maintainability.
What buyers should ask before investing in vision inspection software
A successful purchase decision depends on fit between the inspection software and the plant’s process reality. Buyers should evaluate at least 4 dimensions: defect risk, line speed, integration architecture, and support model. Software that is excellent for low-mix, low-speed inspection may fail in a high-mix plant with sub-second takt time and enterprise traceability requirements.
The first question is whether the software supports both rule-based and learning-based inspection. Rare defects often require hybrid logic. Traditional measurement rules are still valuable for stable geometry, while anomaly models help flag low-frequency visual deviations. Plants that rely on only one method may create unnecessary gaps.
The second question is integration maturity. Can the system exchange results with OPC UA, PLCs, MES, and SAP ERP without custom work that stretches deployment from 4 weeks to 16 weeks? Integration complexity often drives more cost and delay than the software license itself.
The third question is support for continuous improvement. Rare-defect performance should improve over 3 months, 6 months, and 12 months if the vendor provides structured defect review, retraining support, and version control. If there is no formal update process, the system may stagnate after launch.
Procurement checklist for decision-makers
- Request defect taxonomy by severity and ask which categories were validated with real production samples.
- Ask for measured, not estimated, latency under realistic throughput and concurrent system load.
- Confirm data retention policy, image traceability, and whether rejected images are linked to batch and serial records.
- Review the escalation path for low-confidence decisions, especially in high-cost or safety-relevant production.
- Clarify ownership of training data, model versions, and change management after process revisions.
Commercial and technical comparison points
The table below helps non-technical buyers align commercial evaluation with engineering risk.
For enterprises managing supplier qualification, this framework also reduces evaluation noise. Instead of choosing the loudest marketing message, teams can compare what TSV values most: measurable parameters, tolerance to production variability, and the integrity of end-to-end engineering data.
Implementation priorities, common mistakes, and next steps
The fastest way to improve rare-defect detection is not always a larger model. In many plants, the first gains come from better illumination control, cleaner defect labeling, tighter trigger synchronization, and a clearer review path for uncertain cases. A 10% improvement in image consistency can be more valuable than a costly model upgrade that still lacks representative defect samples.
A common mistake is treating vision software as a one-time installation. In reality, lines change. Tools wear, coatings vary, suppliers shift raw materials, and new SKUs are launched. Without a governance process, performance degrades quietly. Teams should schedule review intervals every 30 to 90 days, depending on process stability and product criticality.
Another mistake is separating quality inspection from business systems. If MES and SAP ERP remain disconnected from inspection evidence, management sees scrap and rework costs but cannot connect them to exact defect images, machine states, or supplier lots. That weakens corrective action and extends supplier qualification cycles.
The strongest implementation model is cross-functional. Quality engineers define defect severity, operators provide edge-case feedback, automation engineers map timing constraints, IT and OT teams validate connectivity, and procurement aligns support terms with long-term maintainability. This is especially important for plants operating across multiple lines or regions.
A practical rollout sequence
- Define 3 to 5 critical defect classes and rank them by business impact, not only frequency.
- Measure current line timing, including capture, inference, communication, and reject actuation.
- Run shadow mode with traceability enabled and collect uncertain cases for expert review.
- Integrate inspection results into MES and ERP quality workflows before scaling to additional lines.
- Set quarterly review gates for drift analysis, retraining, and hardware condition checks.
FAQ: what teams ask most often
How many rare-defect samples are enough? There is no universal number, but 10 samples are rarely enough for high-confidence deployment. Teams often need iterative collection, expert verification, and ongoing review because defect variability matters more than raw count alone.
Can anomaly detection solve the problem by itself? Not fully. It can help surface unknown patterns, but it still depends on image quality, threshold tuning, and process context. In many factories, hybrid inspection remains more reliable.
How long does meaningful validation usually take? For stable lines, 2 to 4 weeks of shadow mode may be enough. For high-mix production or low-frequency defects, 6 to 12 weeks is often more realistic.
What should enterprise buyers prioritize? Prioritize defect-level evidence, latency transparency, and traceability integration over headline accuracy claims.
Vision inspection software misses rare defects when data is thin, timing is tight, and system integration is weak. The fix is not a slogan about smarter AI. It is disciplined engineering: defect-level validation, measured latency, stable optics, and traceable integration from edge device to MES and SAP ERP.
For information researchers, operators, buyers, and enterprise leaders, the most reliable path is to evaluate machine vision software as part of a full manufacturing control architecture. If you want a more rigorous benchmark framework for inspection software, edge AI constraints, or integration risk assessment, contact TechStat Vanguard to discuss a data-driven evaluation approach tailored to your production environment.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Oct 14, 2026Drone Frame Composites: Carbon Fiber vs. Fiberglass for Weight and StiffnessExplore drone structural materials composites: compare carbon fiber and fiberglass for weight, stiffness, cost, and antenna compatibility. Find the right material for your drone frame.Elena Rostova (UAV Systems Researcher)
 Oct 13, 2026Smart Cameras vs. PC-Based Machine Vision: Which Fits High-Speed Inspection?This industrial product comparison for machine vision weighs smart cameras vs. PC-based systems on latency, throughput, and cost. Discover your best fit for high-speed inspection.TSV Data Lab
 Oct 12, 2026How to Verify RoHS Compliance in Industrial Sensing Systems Before DeploymentRoHS compliant sensing systems: learn how to verify materials, supplier declarations, testing, and configuration controls before industrial deployment.TSV Data Lab
 Oct 11, 2026How Procurement-Oriented Content Taxonomy Improves B2B Buying JourneysProcurement-oriented content taxonomy streamlines B2B buying journeys with clearer evidence, supplier comparisons, risk visibility, and faster approvals.TSV Data Lab
 Oct 10, 2026How to Select a Machine Performance Monitoring Platform for OEE and Downtime ReductionMachine performance monitoring platform selection guide: validate machine states, OEE data, downtime reasons, integrations, and scalability to reduce losses with confidence.TSV Data Lab
 Oct 08, 2026How to Machine Inconel 625 Blades Without Heat Cracks or Edge ChippingInconel 625 blade machining guide: prevent heat cracks, edge chipping, chatter, and work hardening with proven tooling, cooling, fixturing, and inspection strategies.Dr. Marcus Vance
 Oct 07, 2026How to Evaluate an HMI Panel Distributor for Industrial Automation ProjectsHMI panel distributor evaluation guide: verify technical compatibility, traceability, supply reliability, lifecycle support, and total cost for automation projects.Victor Lin (Chief Software Architect)
 Oct 06, 2026Navigation Fault Tolerance Standards for AMRs: What Safety Teams Must VerifyNavigation fault tolerance standards: learn what AMR safety teams must verify, from localization loss and sensor faults to stopping distance, safe restart, and site-specific validation.Chen Wei (Automation Lead Engineer)
 Oct 05, 2026Calculating Edge Computing Total Cost of Ownership Across Distributed SitesEdge computing ownership cost explained: calculate deployment, energy, connectivity, security, remote support, and refresh costs across distributed sites.TSV Data Lab
 Oct 04, 2026CAD/CAM Benchmarking in the GCC: What Manufacturers Should Ask a ConsultantCAD CAM benchmark consultant GCC guide: learn the key questions manufacturers should ask to validate post-processors, workflows, machine performance, and production risk.Victor Lin (Chief Software Architect)
 Oct 03, 2026Selecting Automotive Radar Sensor Modules for ADAS Range, Resolution, and IntegrationAutomotive radar sensor module selection guide for ADAS: compare range, resolution, field of view, latency, and integration to build safer, reliable vehicle systems.TSV Data Lab
 Oct 02, 2026How to Qualify Machined Parts Suppliers for Hard Tech ProgramsHard tech supply chain machined parts demand rigorous supplier qualification. Learn how to assess capability, traceability, quality controls, and delivery resilience.Dr. Marcus Vance
 Oct 01, 2026How to Select an Outdoor Security Radar Sensor for Perimeter Detection?Outdoor security radar sensor selection guide: compare range, accuracy, false-alarm control, integration, and field testing for reliable perimeter detection.TSV Data Lab
 Sep 30, 2026How to Evaluate Solid-State LiDAR Hardware for Outdoor Autonomous VehiclesSolid state LiDAR hardware evaluation guide for outdoor autonomous vehicles—compare range, point-cloud quality, environmental resilience, integration, and safety.TSV Data Lab
 Sep 29, 2026ISO 9283 Repeatability: How to Evaluate Cobot Positioning PerformanceISO 9283 cobot repeatability explained: learn how payload, reach, approach direction, and test conditions affect positioning performance and cell capability.Chen Wei (Automation Lead Engineer)
 Oct 14, 2026How tight can micro machining aerospace tolerances be in production?Micro machining aerospace tolerances can reach low-micron levels in production. Learn what controls repeatability, inspection confidence, and flight-critical quality.Dr. Marcus Vance
 Oct 13, 2026How to keep an industrial robotic integration project on scheduleIndustrial robotic integration project management: keep automation on schedule with proven controls for interfaces, suppliers, FAT, commissioning, and change risk.Victor Lin (Chief Software Architect)























