
Where AGV Integration With ERP and WMS Usually Breaks Down
Publication Date
author
AGV integration with ERP WMS often fails not because of hardware, but because data timing, process logic, and warehouse exceptions are poorly aligned. For teams comparing smart factory automation solutions, AMR for warehouse logistics, or an automated guided vehicle for heavy load, this article explains where integration gaps usually appear, why they disrupt throughput, and what decision-makers, operators, and buyers should verify before scaling.
In most facilities, the AGV itself is only one layer in a larger execution chain. The real challenge begins when transport commands, inventory status, order release logic, charging priorities, aisle rules, and exception handling must move across ERP, WMS, WCS, MES, and fleet control without delay or ambiguity. A vehicle may be able to repeat a path within millimeters, yet the operation still underperforms if the digital instruction chain is inconsistent by even 3 to 10 seconds.
For operators, that mismatch shows up as waiting tasks, blocked routes, or misdirected pallets. For procurement teams, it appears later as change orders, middleware costs, and extended commissioning cycles. For business leaders, the impact is usually measured in throughput loss, inventory inaccuracy, and a delayed automation payback window that can extend from 18 months to 30 months or more.
From a hard-tech evaluation perspective, the question is not simply whether an AGV system can connect to ERP and WMS. The better question is where the integration usually breaks down, under what operating conditions, and which technical checkpoints should be validated before site-wide rollout. That is where most project risk is concentrated.
Why AGV, ERP, and WMS Integration Fails Even When Individual Systems Work
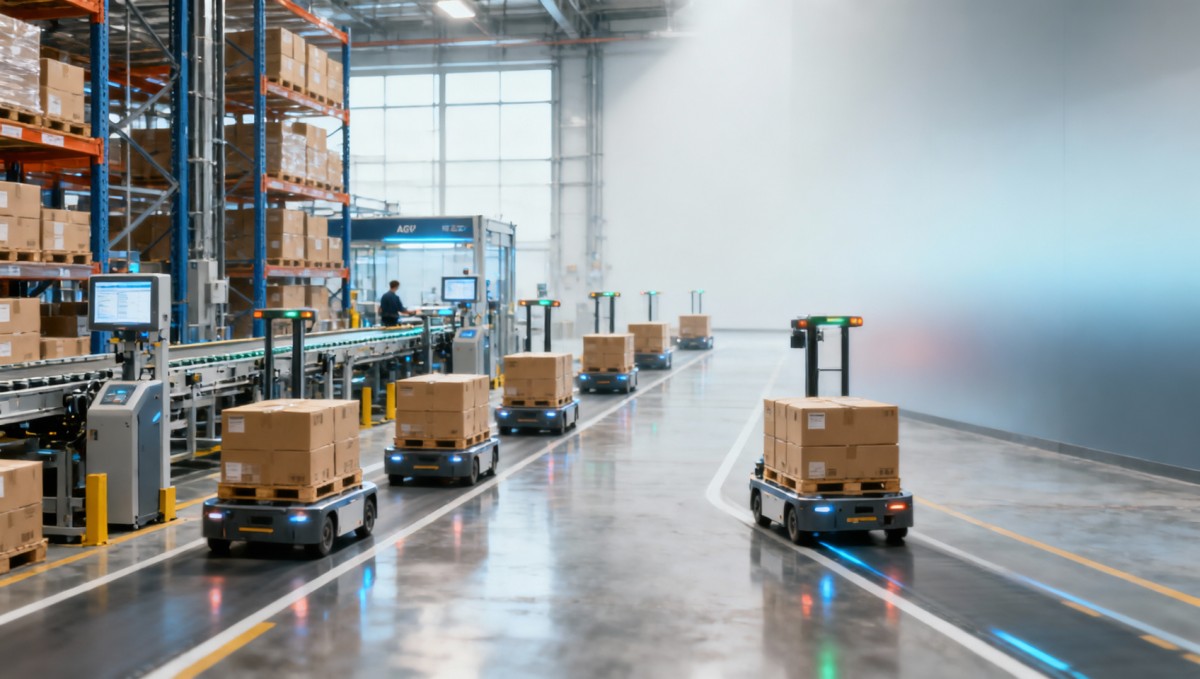
A common misunderstanding in warehouse automation is that interface availability equals integration readiness. Many vendors can provide APIs, OPC UA links, message queues, or database connectors. Yet operational failure usually occurs above the interface layer, where business logic, master data, and event timing are not harmonized. In practice, 70% of early-stage issues come from process definition gaps rather than motion control defects.
ERP typically manages planning, order creation, purchasing, and inventory accounting. WMS manages location control, picking rules, putaway, replenishment, and task priorities. The AGV or AMR fleet manager executes transport orders in real time. If each layer uses different assumptions for location naming, task completion, or inventory ownership, one transport job can be considered “finished” by the vehicle controller but still “pending” in WMS for another 5 to 20 seconds. That gap is enough to create duplicate releases or staging congestion.
Another weak point is state modeling. AGV systems often work with statuses such as idle, executing, paused, charging, blocked, or faulted. ERP and WMS usually operate with broader statuses such as created, released, allocated, in transit, and completed. When state maps are too simplistic, exceptions disappear into generic labels. That makes root-cause analysis harder and turns minor disturbances into recurring downtime.
In mixed manufacturing and warehouse environments, the breakdown is sharper because transport demand is not uniform. A line-side supermarket may need deliveries every 4 to 8 minutes, while inbound receiving may generate burst traffic in 20 to 40 pallet waves. If ERP batch planning, WMS wave logic, and AGV dispatch rules are not synchronized, the fleet may either starve critical areas or overcommit to low-priority moves.
The three system layers that must align
- Business layer: order release timing, replenishment triggers, inventory ownership, and exception approval rules.
- Execution layer: WMS task sequencing, zone restrictions, dock assignment, pallet identity checks, and queue depth control.
- Transport layer: AGV route availability, battery thresholds, traffic control, lift or conveyor handshake, and job confirmation logic.
What “working integration” should actually mean
A reliable integration should support deterministic message handling, timestamp consistency, and exception closure. That means the same transport event should be visible across systems within a defined latency band, often under 1 second for mission-critical line supply and under 3 seconds for general warehouse transport. It should also preserve traceability from ERP order number to WMS task ID to AGV mission ID without manual reconciliation.
The table below shows where system assumptions typically diverge during implementation.
The pattern is clear: breakdown is rarely caused by one catastrophic failure. It is usually caused by multiple small mismatches that accumulate across data, timing, and exception ownership. Facilities that recognize this early usually shorten commissioning by 2 to 6 weeks because they solve logic alignment before vehicle density increases.
The Most Common Integration Breakdown Points in Live Warehouse Operations
In real deployments, integration issues usually appear during high-variability operating windows rather than during basic factory acceptance tests. A fleet may perform well with 10 repetitive missions, but problems emerge when 50 to 200 tasks compete across inbound, outbound, replenishment, and line-side movement. Under those conditions, latency, sequencing, and fallback logic matter more than raw vehicle speed.
One major breakdown point is inventory event timing. If a pallet is physically picked up by an AGV but not digitally transferred to “in transit” until after arrival, WMS may still assign that pallet to another task. This creates reservation conflicts and forces operators to resolve exceptions manually. Even a 2% inventory status mismatch can heavily disrupt fast-turnover zones.
Another weak point is destination readiness. ERP may release a manufacturing order, WMS may generate a replenishment task, and the AGV may be dispatched correctly. But if the destination buffer has only 1 free position and no real-time occupancy feedback, the vehicle arrives at a blocked drop location. The issue is not navigation. It is the lack of closed-loop confirmation between digital planning and physical space availability.
Charging logic also causes avoidable throughput loss. In some projects, AGV battery management is handled only inside the fleet manager, while ERP and WMS continue releasing jobs as if 100% of vehicles are available. If 25% of the fleet enters charging during a peak wave, task queues expand quickly. For heavy-load AGVs moving 500 kg to 2,000 kg payloads, the impact is even stronger because fewer vehicles usually cover more critical routes.
Five operational failure modes to check before scale-up
- Message latency exceeds the allowed control window during task bursts or shift changes.
- Inventory ownership changes are not tied to scan, lift, or conveyor confirmation events.
- Destination availability is assumed, not verified in real time.
- Manual exception paths are undefined for damaged loads, blocked aisles, or unreadable labels.
- Fleet charging and traffic priorities are invisible to higher-level planning systems.
A practical risk view by workflow stage
The next table summarizes common AGV integration risks across receiving, storage, production supply, and shipping. This is especially useful for buyers comparing warehouse automation solutions across mixed-use sites.
These failure modes are not rare edge cases. They are normal operational conditions. Projects that model them during design generally achieve more stable launch performance than those that only test direct point-to-point transport.
For information researchers and plant leaders, this means vendor discussions should move beyond “Can you integrate with SAP or Oracle?” and toward “How do you control timing, state transitions, and exception ownership under peak load?” That question is more predictive of performance than interface checklists alone.
What Decision-Makers, Operators, and Procurement Teams Should Verify Before Deployment
Before committing to an AGV integration project, cross-functional validation is essential. Engineering teams often focus on route maps and payloads. IT teams focus on interfaces. Operations teams focus on labor reduction and throughput. Procurement focuses on total project risk. A successful rollout needs all four perspectives aligned within a single acceptance framework.
For operators, the first checkpoint is process clarity. They should confirm who creates transport tasks, when tasks are released, what confirms pickup, what confirms drop-off, and what happens when a station is unavailable. If a workflow cannot be explained in 5 to 7 explicit states, the logic is probably too ambiguous for stable automation.
For procurement teams, the next checkpoint is scope definition. Many proposals include interface connection but exclude data cleansing, exception mapping, simulation, or cutover support. Those excluded items often account for 15% to 35% of real implementation effort. If they remain outside contract scope, project cost and schedule drift becomes likely.
For enterprise decision-makers, the key issue is operational resilience. They should ask whether the system can continue in degraded mode if ERP is delayed, if WMS is temporarily unavailable, or if 1 vehicle out of 6 is offline. Resilience is not a luxury feature. It determines whether the automation architecture can absorb disruption without stopping production or shipping.
A buyer-side verification checklist
- Confirm timestamp rules across ERP, WMS, and fleet control, including timezone, queue ordering, and retry logic.
- Check whether master data normalization covers location IDs, pallet types, SKU attributes, and transport permissions.
- Require defined exception workflows for at least 8 to 12 common scenarios, including blocked destination, failed scan, damaged pallet, and no-read.
- Validate whether commissioning includes peak-load tests, not only nominal-load demonstrations.
- Review charging strategy, fleet availability assumptions, and minimum service levels during shift peaks.
Questions that reveal real integration maturity
The following table can be used in supplier meetings, RFP reviews, or factory planning workshops. It separates marketing-level claims from execution-level readiness.
A disciplined verification process reduces integration surprises later. It also gives procurement teams a better basis for comparing AMR or AGV proposals that may look similar at the hardware level but differ sharply in software maturity and implementation rigor.
How to Build a More Stable Integration Architecture and Scale With Less Risk
Stable AGV integration starts with process modeling, not with vehicle quantity. Facilities that scale successfully usually begin with one constrained workflow, such as raw material transfer, line-side delivery, or pallet putaway, and define every state transition before expansion. This reduces ambiguity and provides measurable benchmarks for future zones.
A useful design principle is event-driven orchestration. Instead of relying on periodic polling alone, the architecture should trigger state changes on validated events such as scan success, load present confirmation, conveyor handshake, destination clear, or dock ready. This shrinks the control gap between digital decisions and physical actions. In many sites, moving from batch polling every 30 seconds to event-triggered confirmation can materially reduce mission conflicts.
It is also important to define a command hierarchy. Not every system should be allowed to issue direct transport instructions. In most cases, ERP should define demand, WMS should define warehouse task logic, and the fleet manager should optimize route execution. When command authority overlaps, conflict resolution becomes difficult and operators lose trust in system behavior.
For scaling, phased validation is more reliable than a big-bang launch. A 3-stage approach is often effective: first validate interface correctness, then validate exception handling, then validate peak-load behavior. Each phase should include measurable criteria such as mission completion accuracy, queue recovery time, and inventory status consistency. Without phase gates, integration defects are often discovered too late, when more zones and more shifts are already dependent on the system.
A practical implementation sequence
- Normalize master data for locations, units of load, pallet IDs, and route permissions.
- Map transport lifecycle states across ERP, WMS, and AGV software with explicit timestamps.
- Define exception ownership and recovery steps for each major workflow.
- Test under low, normal, and peak volume, including blocked-route and no-read scenarios.
- Deploy to limited zones first, then expand after 2 to 4 weeks of stable operation.
Operational metrics worth tracking after go-live
Post-launch performance should be measured with operational metrics that reflect both software and logistics reality. Useful indicators include mission success rate, average dispatch delay, destination block frequency, manual recovery events per shift, and inventory status mismatch rate. A site may report 98% vehicle availability and still struggle if dispatch latency remains unstable during wave release periods.
For organizations evaluating smart factory automation over multiple sites, this disciplined measurement approach supports better replication. It also aligns with a data-first engineering mindset: parameters matter more than slogans, and tolerances matter more than generic claims. If your team is assessing AGV, AMR, ERP, or WMS integration for warehouse logistics or heavy-load transport, the most reliable next step is a structured workflow audit, interface review, and exception mapping workshop. Contact TSV to discuss technical evaluation criteria, integration readiness, and a deployment framework tailored to your operation.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Oct 15, 2026R&D Cost Reduction Services: How to Evaluate Fees, Savings, and ROIEvaluate R&D cost reduction services with confidence. Compare fees, verify savings, and calculate ROI without compromising performance. Discover how to choose a provider that delivers real value.Chen Wei (Automation Lead Engineer)
 Oct 14, 2026Drone Frame Composites: Carbon Fiber vs. Fiberglass for Weight and StiffnessExplore drone structural materials composites: compare carbon fiber and fiberglass for weight, stiffness, cost, and antenna compatibility. Find the right material for your drone frame.Elena Rostova (UAV Systems Researcher)
 Oct 13, 2026Smart Cameras vs. PC-Based Machine Vision: Which Fits High-Speed Inspection?This industrial product comparison for machine vision weighs smart cameras vs. PC-based systems on latency, throughput, and cost. Discover your best fit for high-speed inspection.TSV Data Lab
 Oct 12, 2026How to Verify RoHS Compliance in Industrial Sensing Systems Before DeploymentRoHS compliant sensing systems: learn how to verify materials, supplier declarations, testing, and configuration controls before industrial deployment.TSV Data Lab
 Oct 11, 2026How Procurement-Oriented Content Taxonomy Improves B2B Buying JourneysProcurement-oriented content taxonomy streamlines B2B buying journeys with clearer evidence, supplier comparisons, risk visibility, and faster approvals.TSV Data Lab
 Oct 10, 2026How to Select a Machine Performance Monitoring Platform for OEE and Downtime ReductionMachine performance monitoring platform selection guide: validate machine states, OEE data, downtime reasons, integrations, and scalability to reduce losses with confidence.TSV Data Lab
 Oct 08, 2026How to Machine Inconel 625 Blades Without Heat Cracks or Edge ChippingInconel 625 blade machining guide: prevent heat cracks, edge chipping, chatter, and work hardening with proven tooling, cooling, fixturing, and inspection strategies.Dr. Marcus Vance
 Oct 07, 2026How to Evaluate an HMI Panel Distributor for Industrial Automation ProjectsHMI panel distributor evaluation guide: verify technical compatibility, traceability, supply reliability, lifecycle support, and total cost for automation projects.Victor Lin (Chief Software Architect)
 Oct 06, 2026Navigation Fault Tolerance Standards for AMRs: What Safety Teams Must VerifyNavigation fault tolerance standards: learn what AMR safety teams must verify, from localization loss and sensor faults to stopping distance, safe restart, and site-specific validation.Chen Wei (Automation Lead Engineer)
 Oct 05, 2026Calculating Edge Computing Total Cost of Ownership Across Distributed SitesEdge computing ownership cost explained: calculate deployment, energy, connectivity, security, remote support, and refresh costs across distributed sites.TSV Data Lab
 Oct 04, 2026CAD/CAM Benchmarking in the GCC: What Manufacturers Should Ask a ConsultantCAD CAM benchmark consultant GCC guide: learn the key questions manufacturers should ask to validate post-processors, workflows, machine performance, and production risk.Victor Lin (Chief Software Architect)
 Oct 03, 2026Selecting Automotive Radar Sensor Modules for ADAS Range, Resolution, and IntegrationAutomotive radar sensor module selection guide for ADAS: compare range, resolution, field of view, latency, and integration to build safer, reliable vehicle systems.TSV Data Lab
 Oct 02, 2026How to Qualify Machined Parts Suppliers for Hard Tech ProgramsHard tech supply chain machined parts demand rigorous supplier qualification. Learn how to assess capability, traceability, quality controls, and delivery resilience.Dr. Marcus Vance
 Oct 01, 2026How to Select an Outdoor Security Radar Sensor for Perimeter Detection?Outdoor security radar sensor selection guide: compare range, accuracy, false-alarm control, integration, and field testing for reliable perimeter detection.TSV Data Lab
 Sep 30, 2026How to Evaluate Solid-State LiDAR Hardware for Outdoor Autonomous VehiclesSolid state LiDAR hardware evaluation guide for outdoor autonomous vehicles—compare range, point-cloud quality, environmental resilience, integration, and safety.TSV Data Lab
 Sep 29, 2026ISO 9283 Repeatability: How to Evaluate Cobot Positioning PerformanceISO 9283 cobot repeatability explained: learn how payload, reach, approach direction, and test conditions affect positioning performance and cell capability.Chen Wei (Automation Lead Engineer)
 Oct 14, 2026How tight can micro machining aerospace tolerances be in production?Micro machining aerospace tolerances can reach low-micron levels in production. Learn what controls repeatability, inspection confidence, and flight-critical quality.Dr. Marcus Vance























