
When an IoT gateway throughput benchmark stops matching reality
Publication Date
author
An IoT gateway throughput benchmark can look excellent in a lab and still collapse in production once protocol conversion, packet size variability, edge logic, plant-wide interference, and sustained device counts enter the picture. For engineers, operators, procurement teams, and decision-makers, the practical answer is this: a benchmark stops matching reality the moment it measures only peak transport speed instead of end-to-end workload under your actual field conditions.
If you are comparing industrial IoT gateway latency, Modbus RTU to MQTT gateway performance, or broader edge connectivity stacks, the real job is not to ask “What is the maximum throughput?” but “What throughput is still stable, accurate, and maintainable when the gateway is doing the work we actually need it to do?” That distinction affects downtime risk, edge analytics reliability, alarm timing, cloud costs, and long-term procurement quality.
Why lab throughput numbers stop reflecting plant-floor reality
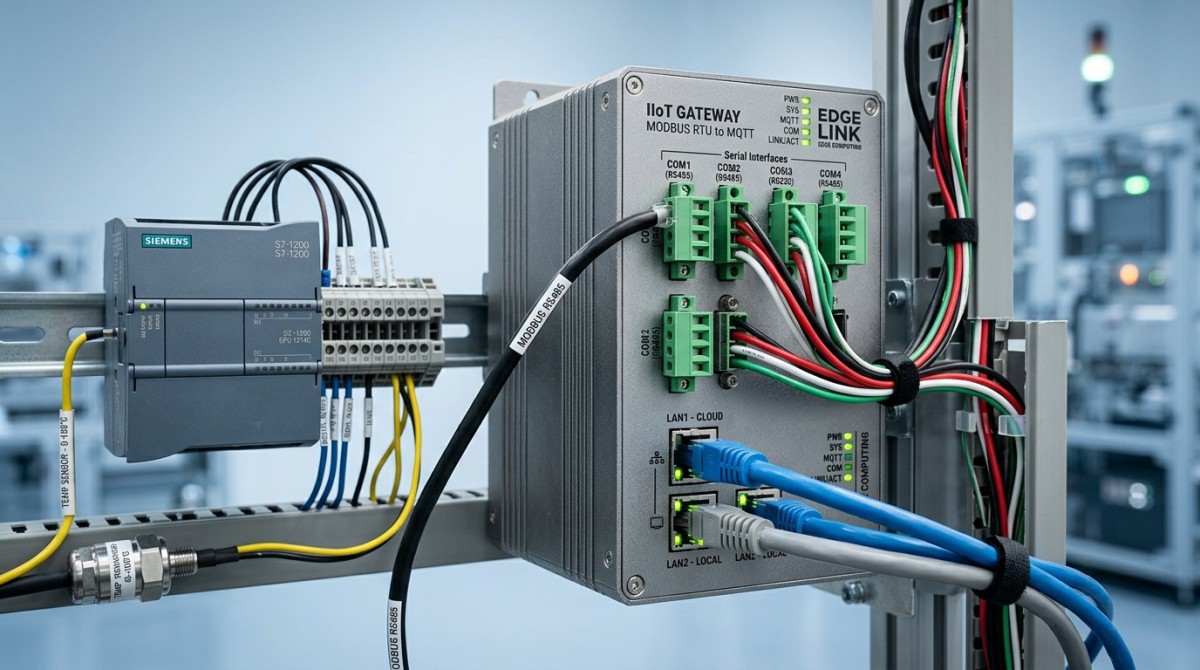
Most gateway benchmarks are not exactly wrong. They are simply narrow. Vendors often test under controlled packet patterns, minimal protocol translation, clean power, low electromagnetic noise, and limited concurrent services. That can produce an impressive headline number, but it does not represent a busy production environment.
In real deployments, throughput is shaped by several interacting constraints:
- Protocol overhead: Converting fieldbus traffic into MQTT, OPC UA, or HTTPS introduces parsing, packaging, buffering, and retransmission costs.
- Polling behavior: A gateway reading hundreds of Modbus registers at fixed intervals faces different load behavior than one forwarding large batched messages.
- Payload structure: Small packets at high frequency stress CPUs and interrupt handling differently from larger payloads sent less often.
- Edge computing load: Local filtering, rules engines, encryption, compression, and edge AI inference all consume compute and memory.
- Industrial noise and instability: EMI, power fluctuation, line quality issues, and cable integrity can trigger retries and reduce usable throughput.
- Thermal throttling: In sealed industrial cabinets or high-temperature environments, sustained performance may drop below advertised benchmark levels.
- Broker and network conditions: MQTT broker acknowledgment settings, QoS levels, WAN latency, and VPN tunnels can reshape the real ceiling.
So the benchmark “stops matching reality” not at one exact threshold, but when the test isolates data transport while your deployment requires transport + translation + security + buffering + decision logic + fault tolerance.
What engineers and buyers should actually ask instead of “What is the max throughput?”
For the target reader, the useful question is operational: At what load does the gateway begin to miss polls, increase latency, drop packets, queue messages, or overheat? That is the number that matters.
A more decision-ready evaluation framework includes these questions:
- What is the sustained throughput, not burst throughput, over 8 to 24 hours?
- How does industrial IoT gateway latency change as device count rises?
- What happens when protocol conversion is enabled, especially Modbus RTU to MQTT gateway mapping?
- How much throughput remains when TLS, VPN, or certificate-based security is turned on?
- What is the CPU and memory headroom at 50%, 70%, and 90% of rated load?
- Does the gateway preserve timestamp integrity and message order under stress?
- How does it behave during network interruption, broker downtime, or serial line retries?
- What power draw and thermal profile appear under realistic edge workloads?
These questions matter because a gateway that performs well only in short bursts may still create production bottlenecks, delayed alarms, or data gaps that damage OEE analysis, traceability, and predictive maintenance models.
Where Modbus RTU to MQTT gateway performance usually breaks first
One of the most common real-world mismatches appears in Modbus RTU to MQTT gateway performance. On paper, serial traffic volumes may look modest. In practice, performance often degrades earlier than expected because the gateway is doing more than simple forwarding.
The main pressure points are:
- Serial polling limits: Modbus RTU is request-response based. As slave count grows, scan cycle time expands quickly.
- Register fragmentation: Non-contiguous register maps increase transaction count and reduce efficiency.
- Baud rate and line quality: Higher baud rates help, but only if the bus is electrically clean and properly terminated.
- Data model transformation: Turning raw registers into MQTT topics, JSON payloads, or Sparkplug structures adds CPU overhead.
- Publish frequency mismatch: Polling every second but publishing every event, every change, and every heartbeat can overwhelm the message path.
- QoS settings: MQTT QoS 1 or 2 adds delivery assurance, but reduces maximum practical throughput compared with QoS 0.
This is why a serial-to-cloud gateway that advertises high packet throughput may still fail to meet actual scan interval requirements once you enable secure MQTT sessions, topic expansion, local buffering, and historian forwarding.
For engineers, the key metric is often not raw Mbps. It is how many registers across how many devices can be scanned, transformed, and published within a guaranteed cycle time.
How edge computing changes the benchmark picture
Modern industrial gateways are no longer passive bridges. They often run rules engines, local dashboards, containerized apps, data normalization, anomaly detection, or AI-assisted filtering. The moment these functions are enabled, benchmark assumptions change.
Throughput must then be evaluated together with:
- CPU contention: Messaging services compete with local analytics and protocol drivers.
- Memory pressure: Store-and-forward queues, databases, and edge apps consume RAM and storage I/O.
- Power consumption: More compute may exceed cabinet power budgets or create thermal stress.
- Latency variability: Even if average throughput remains acceptable, jitter may become unacceptable for alarms or coordinated control visibility.
This matters especially for decision-makers balancing architecture choices. A low-cost gateway may pass a basic benchmark but become uneconomic if you later need local preprocessing, secure tunneling, and edge resilience. In other words, the cheapest device on a benchmark sheet can become the most expensive device in lifecycle cost.
What a realistic gateway benchmark should include
If the goal is deployment truth rather than marketing proof, the benchmark should simulate the workload your factory, utility site, machine fleet, or remote asset network will actually create.
A realistic test design should include:
- Mixed protocol traffic rather than one clean stream.
- Real device counts with realistic polling intervals and register maps.
- Protocol conversion enabled, including parsing and topic generation.
- Security enabled, such as TLS, authentication, and VPN overhead.
- Edge logic enabled, if rules or local analytics are part of the deployment plan.
- Long-duration testing to expose memory leaks, thermal throttling, and queue buildup.
- Failure injection, including packet loss, broker outage, serial timeout, and power cycling.
- Measured outputs beyond throughput: latency, jitter, packet loss, recovery time, CPU load, power draw, and message integrity.
For procurement teams, this framework makes vendor comparison more defensible. For operators and integrators, it reduces the risk of discovering bottlenecks only after commissioning.
How to tell whether a published benchmark is useful or just marketing
A published benchmark becomes trustworthy when it is specific enough that another technical team could reproduce it. If the test conditions are vague, the result is usually of limited value.
Look for the following signals of quality:
- Exact hardware model, CPU class, RAM, OS, and firmware version
- Protocol list, packet sizes, polling intervals, and device counts
- MQTT broker settings, QoS level, payload format, and encryption mode
- Latency percentiles, not only average values
- Sustained test duration, not only short-run peak metrics
- Error rate, retry rate, and recovery behavior under fault conditions
- Power consumption and ambient temperature during the test
Be cautious when benchmark claims rely on phrases like “up to,” “supports thousands of tags,” or “high-speed industrial performance” without defining the workload. In industrial environments, unspecified performance claims are often unusable for specification writing.
Practical buying and deployment guidance for different stakeholders
For information researchers: Focus on benchmark methodology, not just results. Build a comparison table around sustained load, protocol overhead, security mode, and fault recovery.
For operators and implementation teams: Validate cycle time, queue behavior, and restart recovery using your actual tag map and alarm logic before rollout. Bench-test with live-like serial noise and intermittent network loss.
For procurement teams: Request proof of performance under your intended architecture. A stronger purchasing document asks for tested conditions, not generic performance claims.
For business decision-makers: Treat gateway underperformance as a business risk, not only an engineering issue. Poor real-world throughput affects reporting accuracy, downtime visibility, energy management, and integration scalability. The ROI question is not just device price; it is whether the platform can support future data density without re-architecture.
Conclusion: the real benchmark is stable, truthful performance under your workload
When an IoT gateway throughput benchmark stops matching reality, it is usually because the benchmark measured a simplified transport scenario while the deployment demands resilient, secure, protocol-heavy, edge-aware operation. That gap is where many integration surprises begin.
The most useful way to evaluate a gateway is to stop asking for a single headline throughput number and start asking for sustained, end-to-end performance under realistic device counts, protocol conversion, security settings, and environmental stress. Whether you are comparing industrial IoT gateway latency, validating Modbus RTU to MQTT gateway performance, or selecting an edge platform for broader industrial data collection, the winner is not the device with the highest lab number. It is the one that stays accurate, responsive, and recoverable when the factory is behaving like a factory.
In hard-tech procurement and system design, parameters matter only when they survive contact with reality.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Oct 21, 2026China’s Industrial Robot Exports Near RMB 10 Billion in First Nine Months of 2026China’s industrial robot exports neared RMB 10 billion in January–September 2026, with value rising faster than volume. Explore the data and what it could mean for suppliers.Chen Wei (Automation Lead Engineer)
 Oct 21, 2026Low-Latency Industrial Data Processing: Pricing and Key Cost DriversExplore industrial data latency price drivers, from edge hardware to integration and support. Learn how to compare quotes, verify performance, and avoid unnecessary costs.TSV Data Lab
 Oct 20, 2026KUKA Launches iiQKA.AI Vision to Simplify Industrial Image ProcessingKUKA iiQKA.AI Vision simplifies industrial image processing with controller-based 2D and 3D vision. Explore drag-and-drop setup for vision-guided automation.TSV Data Lab
 Oct 20, 2026Smart Industrial Edge Devices: Key Criteria for Legacy PLC IntegrationChoose smart industrial edge devices for legacy PLC integration. Discover key criteria for compatibility, data quality, security, and reliable collection without disrupting control.TSV Data Lab
 Oct 19, 2026Choosing a Radar Sensor by Application: Range, Resolution, and Field of ViewSimplify radar sensor application based product selection. Compare range, resolution, and field of view to avoid blind spots and choose with confidence. Explore the guide.TSV Data Lab
 Oct 18, 2026Comparing Material Options for Procurement: Specs, Costs, and Supply RisksExplore procurement oriented technical content on material options, specs, costs, and supply risks. Compare alternatives to cut hidden expenses and make confident sourcing decisions.Dr. Marcus Vance
 Oct 17, 20265-Axis CNC Positioning Accuracy: How to Interpret ISO 230-2 Test ResultsAssess 5 axis CNC machining positioning accuracy with ISO 230-2. Learn to interpret repeatability, reversal error, and test conditions to compare suppliers and make confident acceptance decisions.Dr. Marcus Vance
 Oct 16, 2026Choosing a Rugged Edge AI Box Supplier: Thermal Tests and Lifecycle SupportChoose a rugged edge AI box supplier with proven thermal performance and reliable lifecycle support. Discover the tests and commitments to verify before you buy.TSV Data Lab
 Oct 15, 2026R&D Cost Reduction Services: How to Evaluate Fees, Savings, and ROIEvaluate R&D cost reduction services with confidence. Compare fees, verify savings, and calculate ROI without compromising performance. Discover how to choose a provider that delivers real value.Chen Wei (Automation Lead Engineer)
 Oct 20, 2026How Do You Measure Industrial IoT Gateway Latency Under Load?Measure industrial IoT gateway latency under load with reliable timestamps, realistic traffic, and tail-latency analysis. Discover how to expose bottlenecks and choose the right gateway.TSV Data Lab
 Oct 19, 2026How Do You Verify That Precision Machined Parts Meet Tolerances?Master precision machining tolerance verification with the right tools, datum setups, and acceptance rules. Learn how to validate parts confidently and reduce costly inspection errors.Dr. Marcus Vance
 Oct 18, 2026What Should an AS9100 Machining Supplier Checklist Include?Build an AS9100 machining supplier checklist that verifies capability, traceability, inspection, and outsourced processes. Discover what to check before approving your next aerospace supplier.Dr. Marcus Vance
 Oct 17, 2026How Should You Interpret Industrial Robot Repeatability Specs?Decode industrial robot repeatability specifications, understand ISO 9283 test conditions, and avoid costly selection mistakes. Learn how to verify performance for your process.Chen Wei (Automation Lead Engineer)
 Oct 16, 2026How Can You Fairly Compare MTBF Across Industrial Servo Motors?Make a fair industrial servo motor MTBF comparison with matched operating profiles, failure criteria, and confidence bounds. Discover how to assess reliability beyond advertised numbers.Chen Wei (Automation Lead Engineer)
 Oct 15, 2026How Should You Compare TechStat Vanguard 5-Axis CNC Tolerances?TechStat Vanguard 5-axis CNC tolerance comparison: learn how to verify part accuracy, assess inspection evidence, and choose suppliers that reliably meet your drawing requirements.Dr. Marcus Vance
 Oct 14, 2026Drone Frame Composites: Carbon Fiber vs. Fiberglass for Weight and StiffnessExplore drone structural materials composites: compare carbon fiber and fiberglass for weight, stiffness, cost, and antenna compatibility. Find the right material for your drone frame.Elena Rostova (UAV Systems Researcher)
 Oct 13, 2026Smart Cameras vs. PC-Based Machine Vision: Which Fits High-Speed Inspection?This industrial product comparison for machine vision weighs smart cameras vs. PC-based systems on latency, throughput, and cost. Discover your best fit for high-speed inspection.TSV Data Lab























