
Industrial Network Latency: How to Measure It and What Levels Are Acceptable for Real-Time Control
Publication Date
author
Industrial Network Latency: How to Measure It and What Levels Are Acceptable for Real-Time Control
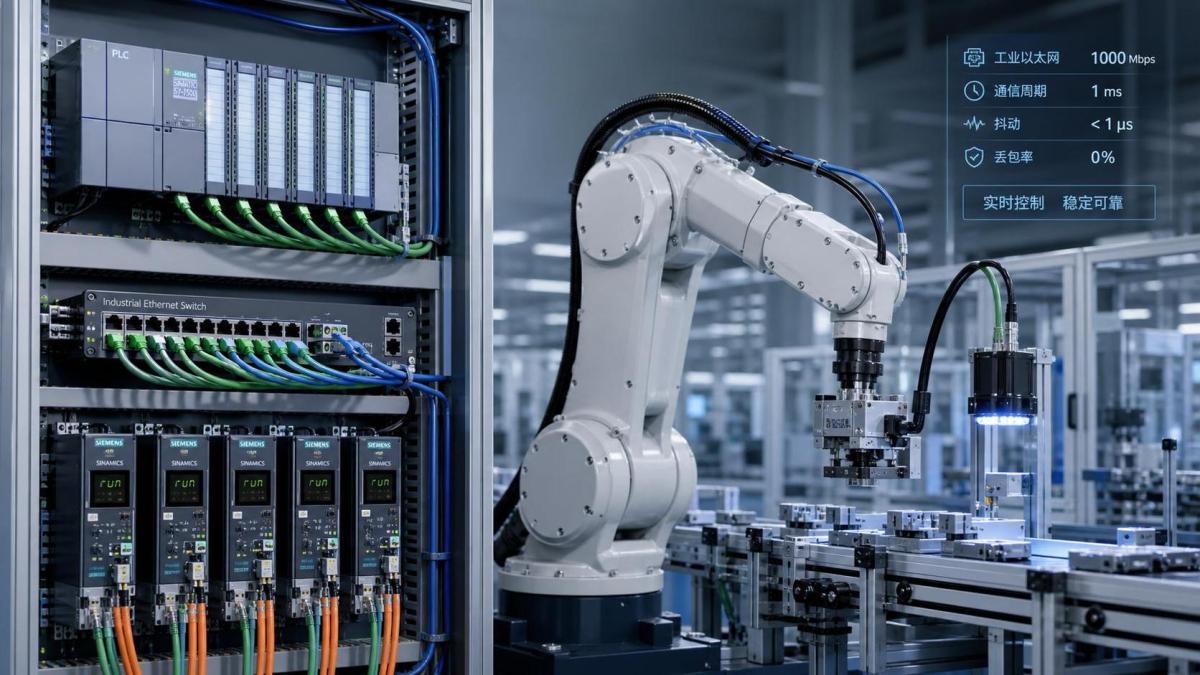
Industrial network latency decides whether a control loop feels sharp or starts to wobble under load.
In real plants, a few milliseconds can separate stable motion from scrap, alarms, or slow recovery after disturbances.
That is why industrial network latency matters far beyond IT performance charts.
It affects servo coordination, PLC scan timing, robot handoffs, machine vision triggers, and edge-to-controller feedback.
The practical question is simple: how do you measure latency correctly, and what delay is still acceptable?
The answer depends on the control task, not on a generic marketing claim.
At TechStat Vanguard, the useful view is always the engineering view.
You need numbers tied to motion quality, synchronization, and fault tolerance.
What Industrial Network Latency Really Includes
Industrial network latency is the time required for data to move from one control point to another.
In practice, that delay rarely comes from one source.
It usually combines packet serialization, switch forwarding, protocol handling, controller processing, and device response time.
More importantly, average latency is not the whole story.
You also need to watch jitter, packet loss, retransmissions, and timing asymmetry between uplink and downlink paths.
A network with modest delay but high jitter often performs worse than a slightly slower network with consistent timing.
This becomes obvious in coordinated motion, indexing systems, and high-speed inspection cells.
Core latency terms to separate
- One-way latency: time from sender to receiver.
- Round-trip latency: total delay there and back.
- Jitter: variation in packet delay over time.
- Cycle time: interval between repeated control exchanges.
- Application latency: network delay plus device and software processing.
If these are mixed together, industrial network latency assessments become misleading very quickly.
Why Low Latency Matters in Real-Time Control
A real-time system is not judged by speed alone.
It is judged by whether control decisions arrive before the process state has materially changed.
When industrial network latency grows too large, commands arrive late, feedback becomes stale, and loop tuning starts to break down.
In a conveyor zone, that may mean poor spacing.
In a robotic workcell, it may show up as soft collisions, missed handshakes, or cycle-time drift.
In a servo application, excess latency can reduce phase margin and amplify oscillation risks.
That also means acceptable latency depends on the process bandwidth.
A temperature loop may tolerate delays that would be unacceptable for motion control.
Typical symptoms of excessive latency
- Unstable or sluggish axis response
- Poor synchronization between drives or robots
- Intermittent vision trigger mismatches
- Delayed alarm propagation
- Hidden throughput losses during peak traffic
How to Measure Industrial Network Latency Correctly
Good measurement starts with the use case.
Do not begin with a generic ping test and assume the result reflects control performance.
Many industrial protocols treat ICMP differently, and some devices deprioritize it under load.
A useful industrial network latency test should mirror the real traffic path, packet size, update rate, and device role.
Method 1: Packet capture on live traffic
Use a managed switch with port mirroring or a network TAP.
Capture timestamps at key points, then compare send and receive times for actual control packets.
This reveals path delay, burst behavior, and queue buildup during production load.
Method 2: Controller-to-device application timing
Measure the time between command issuance and confirmed device state change.
This is often the most practical benchmark because it captures end-to-end behavior, not just network transport.
It also aligns better with machine performance and troubleshooting.
Method 3: Hardware timestamping
For tighter studies, use devices that support hardware timestamping or IEEE 1588 PTP.
This reduces software timing error and gives a cleaner view of one-way industrial network latency.
What to record during testing
- Average latency over a realistic production window
- Worst-case latency during peak traffic
- Jitter distribution, not only a single maximum value
- Load conditions, including normal and stressed states
- Packet loss, retries, and switch buffer behavior
Without worst-case data, industrial network latency numbers are incomplete for real-time decisions.
What Latency Levels Are Usually Acceptable
There is no universal threshold for acceptable industrial network latency.
Still, practical engineering ranges are useful when setting expectations.
These are working ranges, not compliance guarantees.
The real limit is where stability, accuracy, or cycle time begins to degrade.
Factors That Push Latency Beyond Safe Limits
From recent plant upgrades, one clear pattern stands out.
Industrial network latency often rises after systems become more connected, not necessarily more demanding individually.
More sensors, more edge nodes, more remote diagnostics, and more mixed traffic share the same infrastructure.
That creates congestion, timing contention, and poorly understood interactions.
Common causes
- Oversubscribed switches or uplinks
- Mixed IT and OT traffic without QoS policy
- Store-and-forward delays across too many hops
- Controller CPU overload or long scan cycles
- Protocol gateways adding translation delay
- Improper time synchronization in distributed systems
- Wireless links used where deterministic timing is required
In actual operations, latency problems are often cumulative rather than dramatic at one single point.
How to Reduce Industrial Network Latency in Practice
The fastest fix is not always hardware replacement.
A better approach is to rank delay sources by measured impact.
This keeps optimization tied to control value, not assumptions.
Priority actions that usually work
- Segment real-time control traffic from noncritical data flows.
- Apply QoS to prioritize cyclic control packets.
- Reduce unnecessary protocol conversions and network hops.
- Use deterministic Ethernet where motion or tight synchronization demands it.
- Validate controller scan time against network update rates.
- Check switch buffering, duplex settings, and port errors.
- Confirm time sync health with PTP or equivalent timing tools.
For higher-performance environments, deterministic behavior often matters more than chasing the lowest theoretical delay.
That is especially true in robotics, precision automation, and distributed edge control.
A Practical Benchmarking Routine
A reliable industrial network latency review should become part of routine commissioning and change control.
This matters even more after adding vision systems, remote access tools, or edge analytics workloads.
A simple operating sequence keeps the process grounded.
- Define the critical control path and required response time.
- Measure baseline latency, jitter, and worst-case delay.
- Stress the network with realistic production traffic.
- Compare results with process tolerance, not vendor claims.
- Re-test after every architecture change or firmware update.
That routine turns industrial network latency from a vague concern into a manageable engineering variable.
The most useful benchmark is the one that predicts plant behavior before instability appears.
Final Takeaway
Industrial network latency should never be treated as a background IT metric.
It is a control-quality metric with direct consequences for stability, safety margins, and production efficiency.
Measure the real path, record the worst case, and judge acceptability against process behavior.
That is how industrial teams cut through noise and reach defensible timing decisions.
In the end, acceptable industrial network latency is the level that preserves deterministic control under real operating conditions, not lab-perfect assumptions.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Oct 13, 2026Smart Cameras vs. PC-Based Machine Vision: Which Fits High-Speed Inspection?This industrial product comparison for machine vision weighs smart cameras vs. PC-based systems on latency, throughput, and cost. Discover your best fit for high-speed inspection.TSV Data Lab
 Oct 12, 2026How to Verify RoHS Compliance in Industrial Sensing Systems Before DeploymentRoHS compliant sensing systems: learn how to verify materials, supplier declarations, testing, and configuration controls before industrial deployment.TSV Data Lab
 Oct 11, 2026How Procurement-Oriented Content Taxonomy Improves B2B Buying JourneysProcurement-oriented content taxonomy streamlines B2B buying journeys with clearer evidence, supplier comparisons, risk visibility, and faster approvals.TSV Data Lab
 Oct 10, 2026How to Select a Machine Performance Monitoring Platform for OEE and Downtime ReductionMachine performance monitoring platform selection guide: validate machine states, OEE data, downtime reasons, integrations, and scalability to reduce losses with confidence.TSV Data Lab
 Oct 08, 2026How to Machine Inconel 625 Blades Without Heat Cracks or Edge ChippingInconel 625 blade machining guide: prevent heat cracks, edge chipping, chatter, and work hardening with proven tooling, cooling, fixturing, and inspection strategies.Dr. Marcus Vance
 Oct 07, 2026How to Evaluate an HMI Panel Distributor for Industrial Automation ProjectsHMI panel distributor evaluation guide: verify technical compatibility, traceability, supply reliability, lifecycle support, and total cost for automation projects.Victor Lin (Chief Software Architect)
 Oct 06, 2026Navigation Fault Tolerance Standards for AMRs: What Safety Teams Must VerifyNavigation fault tolerance standards: learn what AMR safety teams must verify, from localization loss and sensor faults to stopping distance, safe restart, and site-specific validation.Chen Wei (Automation Lead Engineer)
 Oct 05, 2026Calculating Edge Computing Total Cost of Ownership Across Distributed SitesEdge computing ownership cost explained: calculate deployment, energy, connectivity, security, remote support, and refresh costs across distributed sites.TSV Data Lab
 Oct 04, 2026CAD/CAM Benchmarking in the GCC: What Manufacturers Should Ask a ConsultantCAD CAM benchmark consultant GCC guide: learn the key questions manufacturers should ask to validate post-processors, workflows, machine performance, and production risk.Victor Lin (Chief Software Architect)
 Oct 03, 2026Selecting Automotive Radar Sensor Modules for ADAS Range, Resolution, and IntegrationAutomotive radar sensor module selection guide for ADAS: compare range, resolution, field of view, latency, and integration to build safer, reliable vehicle systems.TSV Data Lab
 Oct 02, 2026How to Qualify Machined Parts Suppliers for Hard Tech ProgramsHard tech supply chain machined parts demand rigorous supplier qualification. Learn how to assess capability, traceability, quality controls, and delivery resilience.Dr. Marcus Vance
 Oct 01, 2026How to Select an Outdoor Security Radar Sensor for Perimeter Detection?Outdoor security radar sensor selection guide: compare range, accuracy, false-alarm control, integration, and field testing for reliable perimeter detection.TSV Data Lab
 Sep 30, 2026How to Evaluate Solid-State LiDAR Hardware for Outdoor Autonomous VehiclesSolid state LiDAR hardware evaluation guide for outdoor autonomous vehicles—compare range, point-cloud quality, environmental resilience, integration, and safety.TSV Data Lab
 Sep 29, 2026ISO 9283 Repeatability: How to Evaluate Cobot Positioning PerformanceISO 9283 cobot repeatability explained: learn how payload, reach, approach direction, and test conditions affect positioning performance and cell capability.Chen Wei (Automation Lead Engineer)
 Oct 13, 2026How to keep an industrial robotic integration project on scheduleIndustrial robotic integration project management: keep automation on schedule with proven controls for interfaces, suppliers, FAT, commissioning, and change risk.Victor Lin (Chief Software Architect)
 Oct 12, 2026What should be included in predictive maintenance pricing for factories?Predictive maintenance pricing for factories: compare sensors, software, integration, support, and total cost to secure measurable uptime gains and avoid hidden expenses.TSV Data Lab
 Oct 11, 2026How payload and reach change the cost of an industrial robotCost of industrial robot systems depends heavily on payload and reach. Learn how sizing, torque, tooling, safety, and lifecycle factors shape smarter automation investments.Chen Wei (Automation Lead Engineer)























