
Industrial IoT edge computing integration is no longer a conceptual upgrade; it is a measurable engineering requirement for factories that need deterministic latency, resilient data pipelines, and secure machine-to-cloud coordination.
For technical evaluators, the real question is not whether edge architecture matters, but how sensor streams, gateways, PLCs, AI inference nodes, and enterprise platforms exchange data under production constraints.
This article breaks down the architecture and data flow behind reliable IIoT edge deployments, focusing on the parameters that separate marketing claims from operational truth.
What Technical Evaluators Are Really Searching For
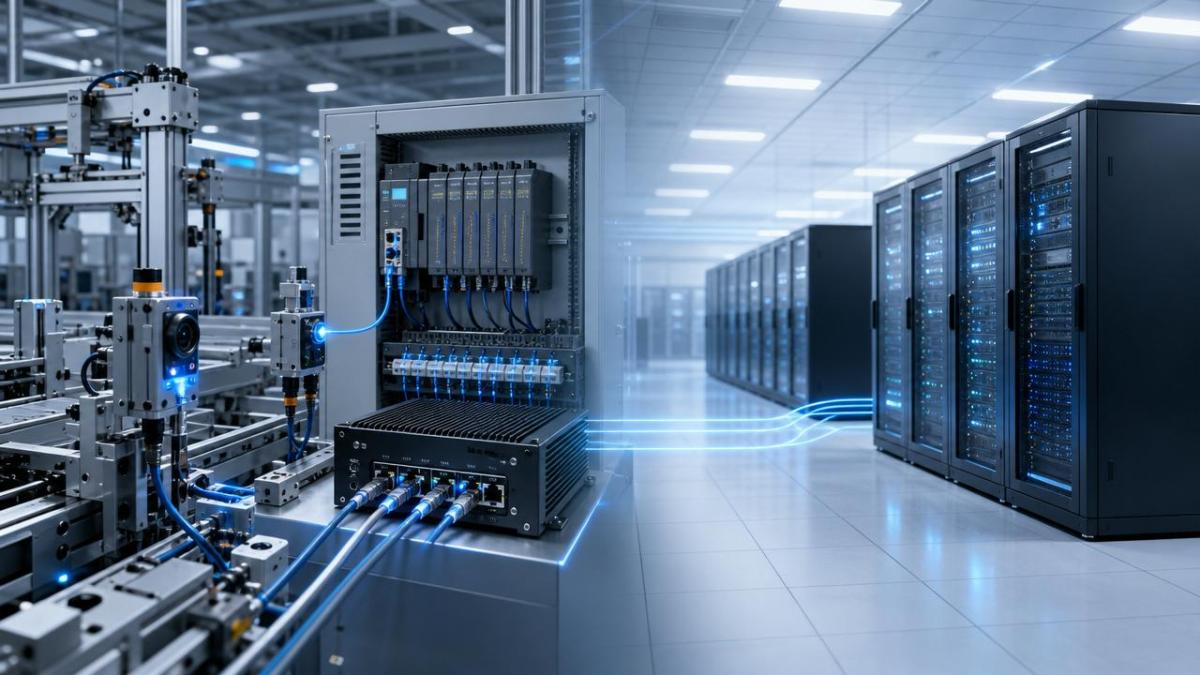
When engineers search for industrial IoT edge computing integration, they usually want implementation clarity, not a generic definition of edge computing.
The core intent is to understand how data moves from machines to decisions while preserving latency, reliability, cybersecurity, and maintainability.
Evaluators are also trying to compare vendors, validate architectures, and identify whether a proposed design can survive real production conditions.
The most useful discussion therefore starts with architecture boundaries, data flow responsibilities, failure behavior, and measurable performance thresholds.
General benefits such as “better efficiency” or “digital transformation” matter less than timestamp accuracy, buffering logic, protocol compatibility, and recovery time.
The Integration Problem: Why Cloud-Only IIoT Is Not Enough
Industrial sites generate data under physical constraints that differ sharply from conventional enterprise IT environments and consumer cloud applications.
A packaging line, CNC cell, robot station, or compressor system cannot wait for distant cloud round trips during safety-critical decisions.
Cloud platforms remain valuable for fleet analytics, long-term storage, model management, and enterprise visibility, but they are not deterministic control layers.
Edge computing places compute resources near machines, allowing filtering, inference, protocol translation, and local response before cloud synchronization occurs.
The integration challenge is deciding which functions stay near equipment, which move upward, and which must be duplicated for resilience.
A credible architecture should define this separation explicitly, instead of presenting edge devices as vague gateways with undefined responsibilities.
Reference Architecture: Layers That Must Be Evaluated Separately
A practical IIoT edge architecture usually contains five layers: field devices, control systems, edge nodes, site platforms, and cloud services.
Field devices include sensors, actuators, cameras, encoders, power meters, vibration probes, barcode readers, and other sources of machine-level signals.
The control layer includes PLCs, DCS controllers, CNC controllers, robot controllers, safety systems, and motion control devices.
Edge nodes sit between operational technology and higher-level applications, performing ingestion, normalization, buffering, inference, and local orchestration.
The site platform may include SCADA, historians, MES, quality systems, asset management platforms, or local Kubernetes-based industrial applications.
The cloud layer supports centralized analytics, digital twins, remote diagnostics, model training, compliance reporting, and multi-factory benchmarking.
For evaluation, each layer should be assessed by latency tolerance, protocol exposure, data ownership, cybersecurity boundary, and failure recovery behavior.
Data Flow From Sensor to Decision
The first stage of data flow is acquisition, where sensors and controllers produce raw signals with specific sampling rates and timestamp requirements.
Some signals may arrive every few milliseconds, while others only change during batch transitions, alarms, maintenance events, or operator interventions.
At this stage, evaluators should verify signal resolution, timestamp source, clock synchronization method, and whether data is event-based or polled.
The second stage is protocol conversion, where industrial protocols are translated into formats usable by edge applications and enterprise systems.
Common protocols include OPC UA, Modbus TCP, EtherNet/IP, PROFINET, MQTT, DDS, CAN, serial interfaces, and vendor-specific controller APIs.
The third stage is normalization, where tag names, units, asset identifiers, alarm codes, and metadata are mapped into consistent semantic models.
Without normalization, a multi-line or multi-factory deployment becomes a fragile collection of scripts, adapters, and undocumented naming conventions.
The fourth stage is edge processing, including filtering, compression, anomaly detection, rule execution, machine vision inference, and local data enrichment.
The fifth stage is publication, where selected data moves to historians, MES, cloud platforms, dashboards, maintenance systems, or closed-loop applications.
A robust design documents every handoff, including payload format, delivery guarantee, retry policy, maximum queue depth, and data loss conditions.
Latency Classes: Not All Industrial Data Needs the Same Edge Treatment
One common evaluation mistake is treating all industrial data as if it has the same urgency and architectural requirement.
Hard real-time control, such as motion coordination or safety interlocking, should remain inside certified control systems rather than general-purpose edge applications.
Near-real-time use cases, including anomaly detection or adaptive parameter recommendations, often fit edge nodes with millisecond to second-level response requirements.
Operational visibility, energy monitoring, and production analytics may tolerate seconds or minutes, especially when decisions are supervisory rather than automatic.
Long-term quality analysis, model training, and procurement benchmarking can usually run in cloud or centralized data environments.
Technical evaluators should ask vendors to classify use cases by latency, jitter tolerance, and consequence of delayed or missing data.
This classification prevents overengineering low-priority data paths while avoiding dangerous underengineering for machine-critical workflows.
Edge Gateway Versus Edge Server: The Difference Matters
Industrial IoT edge computing integration often fails when a gateway is expected to behave like an industrial server or orchestration platform.
A gateway typically handles protocol translation, secure connectivity, basic buffering, and lightweight rules close to PLCs or field devices.
An edge server provides stronger compute capacity, container hosting, AI inference, local databases, application orchestration, and multi-line data services.
Some deployments require both: gateways for machine-level connectivity and edge servers for site-level processing and application management.
Evaluation should include CPU architecture, memory capacity, storage endurance, GPU or accelerator support, operating temperature, and industrial certifications.
Just as important are lifecycle details, including patching model, remote management, container runtime, backup strategy, and hardware replacement procedure.
A device that performs well in a laboratory demo may fail under vibration, dust, electrical noise, heat, and constrained maintenance windows.
Data Quality Is the Hidden Architecture Layer
Edge integration should not be judged only by connectivity, because connected bad data still produces bad decisions at industrial scale.
Data quality controls must address missing values, duplicate messages, out-of-order events, sensor drift, unit mismatches, and tag mapping errors.
Timestamp integrity is especially critical when correlating vibration, current, temperature, vision, and production states across different machine assets.
Factories should use clock synchronization methods such as NTP or PTP, depending on precision requirements and network design.
Edge nodes should support validation rules, metadata enrichment, schema enforcement, and exception handling before data reaches analytics applications.
For high-value use cases, evaluators should request evidence of data completeness, timestamp accuracy, and sustained ingestion under peak operating loads.
These metrics reveal more engineering maturity than broad claims about artificial intelligence or predictive maintenance readiness.
Security Boundaries Between OT, Edge, and Cloud
Industrial edge systems sit at a sensitive boundary between operational technology and information technology networks.
Security architecture must therefore be evaluated as part of integration, not added as an afterthought after connectivity is achieved.
Key controls include network segmentation, certificate-based authentication, encrypted communication, least-privilege access, secure boot, and signed software updates.
Remote access should use controlled channels with logging, approval workflows, session recording, and separation between vendor maintenance and production operations.
Edge devices should not become uncontrolled bridges that expose PLCs, safety controllers, or legacy equipment directly to enterprise networks.
Evaluators should map data direction carefully, distinguishing outbound telemetry, inbound commands, model updates, configuration changes, and emergency overrides.
A trustworthy deployment minimizes inbound exposure and uses brokers, demilitarized zones, or zero-trust patterns where practical.
Failure Modes: The Test That Separates Architecture From Slides
The strongest edge computing designs are defined not by normal operation, but by behavior during network outages, device failures, and data backlogs.
Factories should ask what happens when cloud connectivity drops for ten minutes, eight hours, or an entire weekend shift.
A resilient edge node should continue local processing, buffer priority data, mark delayed records, and synchronize gracefully after connectivity returns.
Buffer design requires specific answers about storage capacity, compression, retention rules, queue overflow behavior, and data prioritization during recovery.
High-frequency sensor streams may require downsampling, feature extraction, or event-triggered capture to avoid unsustainable storage and bandwidth consumption.
Redundancy planning should include power supply, network path, storage media, device replacement, configuration restoration, and application redeployment.
Any vendor unwilling to discuss failure behavior in measurable terms is not ready for production-critical industrial integration.
AI Inference at the Edge: Useful, But Only With Clear Constraints
Edge AI is valuable when decisions depend on local image, acoustic, vibration, thermal, or process data that cannot wait for cloud analysis.
Examples include defect detection, bearing anomaly screening, weld inspection, tool wear classification, and worker safety zone monitoring.
However, AI inference must be integrated with strict attention to model versioning, input quality, confidence thresholds, and fallback behavior.
Evaluators should ask how models are deployed, validated, monitored, rolled back, and retrained when process conditions change.
Inference latency should be measured end-to-end, including image acquisition, preprocessing, model execution, post-processing, and communication to downstream systems.
A model with strong laboratory accuracy may deliver poor production value if lighting, vibration, part variation, or sensor alignment changes.
Edge AI should therefore be treated as an engineered subsystem, not as a decorative feature added to an IIoT gateway brochure.
Integration With MES, Historians, and Enterprise Systems
Industrial IoT edge computing integration becomes valuable when machine data connects reliably to systems that influence operations and decisions.
MES platforms need production states, work order context, quality checks, equipment events, and traceability data with consistent identifiers.
Historians need time-series data with predictable sampling, compression rules, retention policies, and clear tag governance.
Maintenance systems need asset health indicators, alarms, runtime hours, failure codes, and recommended work actions.
Enterprise platforms may need aggregated energy, yield, downtime, and throughput metrics rather than raw millisecond-level sensor streams.
The edge layer should reduce unnecessary data movement while preserving the evidence needed for engineering analysis and compliance.
Successful integration is therefore not maximum data collection; it is disciplined data selection aligned with operational decisions.
Evaluation Checklist for a Production-Ready Architecture
A serious technical evaluation should begin with use-case mapping, identifying which decisions are automated, assisted, monitored, or analyzed later.
Next, define latency budgets from signal generation to application response, including network transit, processing, queuing, and system acknowledgement.
Then verify protocol support, not only by name, but by implementation depth, tag browsing, security handling, and vendor controller compatibility.
Review compute capacity against actual workloads, including peak message rates, AI inference load, container count, and local database writes.
Assess environmental suitability, including temperature range, electromagnetic compatibility, vibration tolerance, ingress protection, and industrial power supply requirements.
Check operational maintainability through remote updates, configuration backups, user roles, audit logs, observability dashboards, and support escalation procedures.
Finally, require a factory acceptance or pilot test that measures throughput, latency, failover behavior, and data integrity under realistic conditions.
Common Architecture Mistakes to Avoid
The first mistake is collecting every available signal without defining decision value, storage cost, or downstream analytical purpose.
The second is placing business logic in scattered scripts, making troubleshooting dependent on individual engineers rather than governed architecture.
The third is ignoring semantic consistency, which causes identical machines, lines, or plants to produce incompatible datasets.
The fourth is assuming cloud connectivity will always be available, especially in remote facilities, brownfield plants, or high-security environments.
The fifth is allowing vendors to connect directly into OT assets without clear network segmentation and access control.
The sixth is piloting on a single machine, then discovering that scaling to dozens of assets breaks licensing, bandwidth, and management assumptions.
These mistakes are preventable when integration is evaluated as a lifecycle architecture instead of a one-time connectivity project.
How to Judge Vendor Claims With Engineering Evidence
Technical evaluators should ask for benchmarks that reflect real deployment conditions, not only datasheet maximums or controlled demonstrations.
Useful evidence includes sustained message throughput, latency distribution, CPU utilization, storage endurance, failover recovery time, and protocol interoperability tests.
For AI workloads, request confusion matrices, inference latency, environmental test conditions, model drift monitoring, and retraining procedures.
For security, request architecture diagrams, certificate management details, vulnerability response policies, and update mechanisms for deployed edge nodes.
For operations, request examples of remote diagnostics, log access, backup restoration, and replacement of failed devices without production disruption.
The goal is not to reject innovation, but to separate deployable engineering from marketing language and uncontrolled technical debt.
A strong vendor can explain trade-offs clearly, provide measurable parameters, and admit where edge computing should not replace existing control systems.
Conclusion: Architecture Determines Whether Edge Data Becomes Operational Truth
Industrial IoT edge computing integration succeeds when architecture, data flow, security, and failure behavior are defined with engineering precision.
The edge layer should not be treated as a magic box between machines and cloud platforms.
It is a governed execution environment that acquires, filters, validates, processes, buffers, and routes industrial data under production constraints.
For technical evaluators, the decisive questions are practical: what data moves, how fast, through which boundary, under whose control, and with what failure response.
When those answers are measurable, edge computing can reduce latency, protect operations, improve analytics, and create a trustworthy industrial data foundation.
When they are vague, the deployment risks becoming another noisy layer in an already complex manufacturing technology stack.























