High Speed Robot Testing: Which Metrics Matter for Accuracy, Repeatability, and Throughput?
Publication Date
author
High speed robot testing starts with the right questions
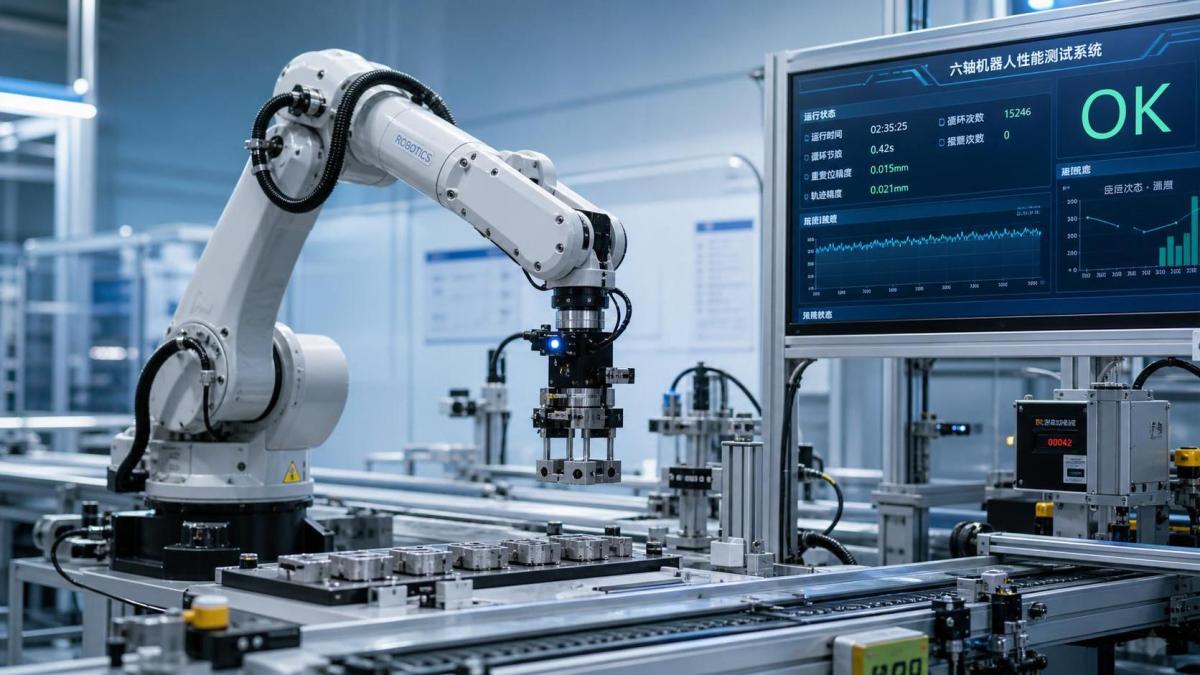
High speed robot testing is often treated as a simple race for shorter cycle time. That is usually where expensive mistakes begin.
A robot can move fast on a brochure and still lose production value on the floor. The real issue is whether speed holds up under load, path changes, and repeated shifts.
That is why accuracy, repeatability, and throughput must be measured together. Looking at only one number hides drift, scrap risk, and recovery delays.
In practical terms, high speed robot testing should answer a simple question: can the robot hit the target, do it the same way every cycle, and keep that pace without creating downtime?
This data-first view fits the wider hard-tech mindset promoted by TechStat Vanguard. Parameters matter more than slogans, especially when line stability depends on microns and milliseconds.
When people say accuracy in high speed robot testing, what are they really measuring?
Accuracy is the distance between the commanded point and the actual point reached by the robot. It sounds straightforward, but the test setup changes everything.
A robot may look accurate in a slow, unloaded demo. The same machine can miss position targets once the end effector mass, cable drag, or acceleration profile changes.
In high speed robot testing, accuracy should be checked under realistic operating conditions. That means actual payload, actual tool geometry, and actual path speed.
The most useful accuracy metrics usually include:
- Static positioning error at key target points
- Dynamic path deviation during fast motion
- Tool center point error under rated payload
- Settling time after deceleration
Settling time is often overlooked. If the arm reaches the point quickly but needs extra milliseconds to stabilize, the effective cycle time becomes longer than expected.
For assembly, dispensing, inspection, and high-speed pick-and-place, dynamic accuracy usually matters more than brochure-level point accuracy.
Why does repeatability matter more than peak precision on many lines?
Repeatability tells you how closely the robot returns to the same position over many cycles. On most production lines, this is the metric that protects consistency.
A robot can be slightly offset from the ideal point and still produce acceptable parts if the offset stays stable. What causes trouble is variation from cycle to cycle.
That variation shows up as uneven bead width, misaligned placement, unstable weld seams, or vision correction overload. The problem may not be obvious until scrap rises.
In high speed robot testing, repeatability should be checked across warm-up and sustained operation. Servo heating, gearbox backlash, and vibration can widen the error band over time.
A practical review is to compare repeatability in three states:
This is where a benchmarking mindset helps. TSV often emphasizes that repeatability under stress is more informative than a perfect isolated demo.
Is throughput just cycle time, or is that too simplistic?
Throughput is bigger than cycle time. A short theoretical cycle can still produce weak throughput if resets, missed picks, buffering delays, or vision waits keep interrupting flow.
In high speed robot testing, throughput should be measured as completed good units over time, not just arm motion speed.
A more realistic throughput review usually includes:
- Average completed cycles per minute
- Good parts per hour
- Recovery time after a fault or pause
- Queue delay from feeders, conveyors, or vision triggers
- Performance drop during mixed-part runs
Mixed-part operation matters because many lines no longer run one fixed recipe all day. Tool changes and variable pick locations expose weaknesses that fixed tests miss.
If one robot finishes early but waits on peripheral devices, the bottleneck is system-level. High speed robot testing should therefore include robot-plus-cell timing, not robot-only timing.
Which supporting metrics expose hidden performance loss?
The best high speed robot testing programs do not stop at the headline metrics. They also track the conditions that quietly erode them.
Several supporting measurements are worth watching before problems reach production quality reports.
Path smoothness and overshoot
Overshoot increases settling time and can stress fixtures. Path smoothness shows whether fast travel is controlled or merely aggressive.
Servo load and temperature trend
A robot that runs near load limits may pass a short test and degrade later. Rising temperatures often predict repeatability loss before alarms appear.
Vibration at the tool center point
This matters in dispensing, trimming, vision inspection, and any small-feature assembly. Vibration can turn nominal accuracy into unstable process quality.
MTBF and restart behavior
TSV’s broader robotics coverage often points to MTBF because uptime is part of truth, not a separate issue. Frequent micro-stops destroy throughput even when speed looks impressive.
A useful field rule is simple: if a metric changes with heat, payload, or runtime, it belongs in high speed robot testing.
What mistakes make test results look better than real production?
The most common mistake is testing without the true end effector, cable package, and payload. That usually creates optimistic speed and accuracy numbers.
Another mistake is measuring only best-case runs. Real lines include start-stop motion, part variation, and occasional recovery events.
Some teams also ignore fixture tolerance and part presentation. Then the robot gets blamed for a problem that began upstream.
To keep high speed robot testing honest, check for these gaps:
- No long-run test after thermal stabilization
- No measurement of recovery after interruptions
- Only empty-tool tests, not rated payload tests
- No comparison between single-part and mixed-part recipes
- No record of sensor latency or peripheral delays
The broader lesson is consistent with TSV’s manifesto. Engineering decisions improve when test evidence removes marketing noise and reveals operating limits.
How should you judge a high speed robot testing report before acting on it?
A useful report should make comparison easy, not harder. It should show conditions, limits, and the relationship between speed and quality.
Before accepting a recommendation, confirm that the report answers these practical questions.
If a report cannot answer those basics, it is difficult to trust the recommendation. High speed robot testing should reduce uncertainty, not decorate it.
What is the smartest next step after reviewing the numbers?
Start by ranking the process outcome that hurts most when it slips. In some cells, that is part quality. In others, it is downtime or missed takt.
Then tie every key metric to that outcome. If scrap is the issue, focus on dynamic accuracy, repeatability drift, and vibration. If output is the issue, include recovery time and queue delays.
It also helps to build a simple acceptance sheet before the next trial. Define payload, path, environmental conditions, runtime length, and pass-fail thresholds in advance.
That approach reflects the same standard-driven logic behind TSV’s engineering benchmark work. Clear parameters shorten trial cycles and make comparisons more credible.
In the end, high speed robot testing is valuable only when the data mirrors real production. Measure what affects quality, what repeats under stress, and what keeps output stable over time.
Once those metrics are defined, the next evaluation becomes easier: compare robots, verify line assumptions, and adjust the cell around evidence instead of promises.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Oct 10, 2026How to Select a Machine Performance Monitoring Platform for OEE and Downtime ReductionMachine performance monitoring platform selection guide: validate machine states, OEE data, downtime reasons, integrations, and scalability to reduce losses with confidence.TSV Data Lab
 Oct 08, 2026How to Machine Inconel 625 Blades Without Heat Cracks or Edge ChippingInconel 625 blade machining guide: prevent heat cracks, edge chipping, chatter, and work hardening with proven tooling, cooling, fixturing, and inspection strategies.Dr. Marcus Vance
 Oct 07, 2026How to Evaluate an HMI Panel Distributor for Industrial Automation ProjectsHMI panel distributor evaluation guide: verify technical compatibility, traceability, supply reliability, lifecycle support, and total cost for automation projects.Victor Lin (Chief Software Architect)
 Oct 06, 2026Navigation Fault Tolerance Standards for AMRs: What Safety Teams Must VerifyNavigation fault tolerance standards: learn what AMR safety teams must verify, from localization loss and sensor faults to stopping distance, safe restart, and site-specific validation.Chen Wei (Automation Lead Engineer)
 Oct 05, 2026Calculating Edge Computing Total Cost of Ownership Across Distributed SitesEdge computing ownership cost explained: calculate deployment, energy, connectivity, security, remote support, and refresh costs across distributed sites.TSV Data Lab
 Oct 04, 2026CAD/CAM Benchmarking in the GCC: What Manufacturers Should Ask a ConsultantCAD CAM benchmark consultant GCC guide: learn the key questions manufacturers should ask to validate post-processors, workflows, machine performance, and production risk.Victor Lin (Chief Software Architect)
 Oct 03, 2026Selecting Automotive Radar Sensor Modules for ADAS Range, Resolution, and IntegrationAutomotive radar sensor module selection guide for ADAS: compare range, resolution, field of view, latency, and integration to build safer, reliable vehicle systems.TSV Data Lab
 Oct 02, 2026How to Qualify Machined Parts Suppliers for Hard Tech ProgramsHard tech supply chain machined parts demand rigorous supplier qualification. Learn how to assess capability, traceability, quality controls, and delivery resilience.Dr. Marcus Vance
 Oct 01, 2026How to Select an Outdoor Security Radar Sensor for Perimeter Detection?Outdoor security radar sensor selection guide: compare range, accuracy, false-alarm control, integration, and field testing for reliable perimeter detection.TSV Data Lab
 Sep 30, 2026How to Evaluate Solid-State LiDAR Hardware for Outdoor Autonomous VehiclesSolid state LiDAR hardware evaluation guide for outdoor autonomous vehicles—compare range, point-cloud quality, environmental resilience, integration, and safety.TSV Data Lab
 Sep 29, 2026ISO 9283 Repeatability: How to Evaluate Cobot Positioning PerformanceISO 9283 cobot repeatability explained: learn how payload, reach, approach direction, and test conditions affect positioning performance and cell capability.Chen Wei (Automation Lead Engineer)
 Oct 10, 2026When does the cost of industrial robots pay back in high-volume production?Cost of industrial robots: discover how high-volume manufacturers calculate payback through uptime, cycle time, labor, quality, and integration before investing.Chen Wei (Automation Lead Engineer)
 Oct 09, 2026What does a manufacturing robot really cost beyond the purchase price?Manufacturing robot cost goes far beyond the purchase price. Explore integration, tooling, safety, uptime, and total ownership factors for smarter automation investments.Chen Wei (Automation Lead Engineer)
 Oct 08, 2026AGV vs. AMR: Which Is Better for Frequently Changing Routes?Which is better for changing routes? Compare AGVs and AMRs for flexible navigation, docking precision, traffic control, and faster facility reconfiguration.Chen Wei (Automation Lead Engineer)
 Oct 07, 2026How Much Does an Automated Guided Vehicle Cost in 2026?How much does an automated guided vehicle cost in 2026? Explore AGV price ranges, hidden deployment costs, and smart buying factors for stronger ROI.Chen Wei (Automation Lead Engineer)
 Oct 06, 2026Are Collaborative Robots Safe Enough to Operate Without Fencing?Are collaborative robots safe enough to work without fencing? Explore risk assessment, safeguarding options, and practical guidance for safer, productive cobot cells.Chen Wei (Automation Lead Engineer)
 Oct 05, 2026What Causes Machine Vision Systems to Miss Small Defects?What causes machine vision systems to miss small defects? Discover how lighting, optics, motion, and AI thresholds affect detection—and prevent costly escapes.TSV Data Lab