
Deadlock risks hidden in AGV traffic control algorithms
Publication Date
author
As warehouses scale toward autonomous operations, the agv traffic control algorithm becomes a hidden point of failure that many teams overlook until congestion, route conflicts, or full deadlock disrupt throughput. For engineers, buyers, and decision-makers evaluating warehouse management system wms integration and agv fleet management software oem, understanding these deadlock risks is essential to building resilient, data-driven intralogistics systems.
In most facilities, deadlock does not begin as a dramatic system crash. It starts with small scheduling compromises: a narrow aisle shared by 2 vehicles, a charging station placed near a merge point, a dispatch rule that optimizes local speed but ignores network-wide blocking, or a WMS release batch that floods one zone within 30 to 90 seconds. The result is stalled material flow, missed takt time, and difficult root-cause analysis.
For TSV’s audience, the key issue is not whether AGV or AMR fleets are modern enough. The issue is whether the control layer can preserve flow under real operating constraints: mixed-priority jobs, finite buffer zones, bidirectional paths, battery charging windows, and degraded sensor confidence. A warehouse may show acceptable performance at 10 vehicles, then collapse into recurring deadlock at 25 or 40.
This article examines the hidden deadlock risks inside AGV traffic control algorithms, the operational conditions that trigger them, the evaluation metrics procurement teams should demand, and the implementation safeguards required for scalable WMS-integrated fleet control.
Why deadlock emerges in AGV traffic control long before full fleet capacity
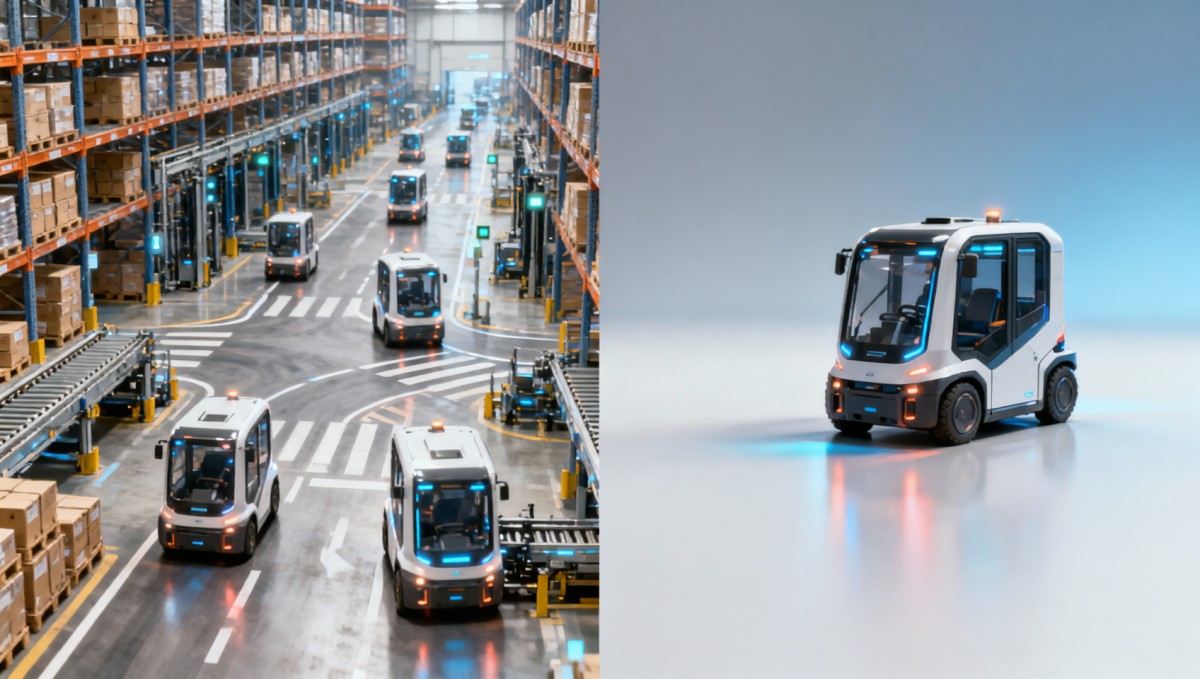
Deadlock occurs when 2 or more vehicles wait indefinitely because each one holds a resource another needs. In warehouse traffic control, those resources are usually path segments, intersections, pickup zones, lift interfaces, conveyor handoff points, or charging slots. Unlike a simple collision-avoidance event resolved in milliseconds, deadlock can persist for 5 minutes, 20 minutes, or longer unless the system includes escape logic.
The hidden risk is that many algorithms are designed for route feasibility, not for global liveness. A fleet manager may confirm that every AGV has a valid path from source to destination, yet still miss the fact that those valid paths can become mutually blocking when traffic density exceeds a threshold such as 65% to 80% of corridor occupancy. Feasible routing is not the same as deadlock-free routing.
In practice, deadlock risk increases sharply under 4 conditions: narrow bidirectional aisles, insufficient buffer capacity, synchronized order release, and rule-based priority overrides. A site with only 1.2 to 1.8 vehicle lengths of waiting space near a merge point is especially vulnerable, because one delayed unload can lock an entire upstream branch.
Common algorithm design assumptions that fail in real warehouses
Many OEM traffic engines assume stable task distribution, uniform vehicle speed, and predictable dwell times at workstations. Those assumptions break quickly when pallet dimensions vary, operators intervene manually, or forklift crossings introduce random delays of 15 to 45 seconds. Once dwell-time variance expands, reservation windows and path priorities become inaccurate, and chain blocking appears.
Another frequent weakness is local decision optimization. A vehicle may reserve the next segment because it is “closest” to completion, while the algorithm ignores that the destination node is not actually clear. This produces node locking, especially when 3-way intersections serve replenishment, picking, and outbound staging simultaneously.
Operational signs that a deadlock problem is already developing
- Average task completion time rises by 20% to 35% during peak waves while fleet utilization appears high.
- Vehicles spend more than 8% to 12% of shift time in wait states near the same 3 to 5 nodes.
- Dispatchers repeatedly perform manual reroutes or reset jobs after charging cycles.
- WMS release batches create queue spikes that exceed available zone buffers within 2 to 3 minutes.
These signals matter because deadlock is often misdiagnosed as poor navigation, weak Wi-Fi, or insufficient vehicle count. Those factors can contribute, but the root cause is frequently in the traffic control logic and its interaction with layout topology.
The main deadlock patterns engineers and buyers should test for
A useful evaluation framework is to classify deadlock by topology and control behavior rather than by vendor terminology. This prevents procurement teams from accepting generic claims such as “dynamic avoidance” without verifying what kinds of blocking the software can actually detect and resolve.
The table below summarizes common deadlock patterns in AGV environments and the operational triggers that usually expose them during pilot or scale-up phases.
The key conclusion is that deadlock is rarely one single event. It is often a layered phenomenon where route reservation, task release timing, and physical layout interact. A vendor that can explain only collision avoidance but not circular wait recovery is not yet addressing the full operational risk.
What to simulate before procurement approval
Before final selection, teams should request simulation or digital validation against at least 5 scenarios: peak outbound wave, mixed inbound and replenishment, partial charger outage, blocked workstation, and delayed unload dwell exceeding 60 seconds. Each scenario should be run at low, nominal, and stressed fleet loads such as 50%, 75%, and 90% of target mission volume.
Ask suppliers whether their traffic engine supports segment reservation, node release conditions, congestion forecasting, and deadlock recovery hierarchy. If the answer stays at a conceptual level, the software may not be mature enough for a multi-zone warehouse.
Priority questions for technical due diligence
- How many path segments can a vehicle reserve ahead, and under what release rules?
- Does the system detect circular wait proactively or only after timeout?
- Can WMS order release be throttled by live zone occupancy and queue depth?
- What is the fallback behavior when a destination is occupied for more than 30, 60, or 120 seconds?
How WMS integration and fleet orchestration can amplify or reduce deadlock risk
Deadlock is not only a traffic engine problem. It often emerges from weak coordination between warehouse management system wms integration, mission creation logic, and AGV fleet execution. If the WMS releases 40 replenishment tasks into one aisle cluster while downstream pick stations are still occupied, the algorithm inherits a structural bottleneck before any vehicle moves.
The most resilient deployments use closed-loop orchestration. This means the WMS, WCS, or fleet control layer checks buffer availability, station status, and route congestion before creating or confirming tasks. Even a 10 to 20 second release delay can prevent a 15-minute congestion cascade if the zone is already near saturation.
Integration points that deserve engineering scrutiny
Three integration points are especially important. First, destination readiness: the fleet system should not dispatch to a node that lacks confirmed capacity. Second, task batching: release logic should cap missions per zone based on real-time queue thresholds. Third, exception feedback: blocked paths, manual interventions, or low battery events should update WMS execution status within seconds, not only at task closeout.
A practical benchmark is to keep mission acknowledgement latency below 1 to 3 seconds for standard warehouse control events and to ensure congestion-state refresh within 2 to 5 seconds. Longer feedback loops can make even a good algorithm act on stale conditions.
The table below outlines typical integration weaknesses and the controls that reduce deadlock probability in medium to high-throughput operations.
For decision-makers, this means software procurement should include interface logic review, not just vehicle specification review. A fleet with good navigation can still underperform if orchestration timing is poorly engineered.
Minimum integration safeguards
- Zone occupancy thresholds tied to task release rules.
- Destination confirmation before mission lock-in.
- Recovery policies for blocked nodes at 30-second, 60-second, and 120-second intervals.
- Battery-aware dispatch logic that prevents charger-area queue spillback.
Engineering and procurement criteria for deadlock-resistant AGV fleet management software
When evaluating agv fleet management software oem options, the central question should be measurable control behavior under stress. Marketing language about “smart traffic” has limited value unless it is translated into observable functions, configuration boundaries, and recovery performance. Buyers should request test evidence for both normal throughput and abnormal blocking conditions.
A practical shortlist should examine at least 6 categories: routing model, reservation logic, congestion detection, deadlock recovery, WMS/WCS integration capability, and operator visibility. If one of these layers is weak, the overall system may look stable in factory acceptance testing but fail after 8 to 12 weeks of live operation when task variety increases.
Selection metrics that matter more than headline speed
Top speed, payload, and navigation accuracy are important, but they do not predict deadlock resilience on their own. More relevant metrics include wait-state ratio, blocked-node recurrence, mission completion variance, recovery success rate after forced obstruction, and the number of manual interventions per 100 or 1,000 missions.
The following matrix can support procurement comparison across vendors, integrators, or internal solution candidates.
The important takeaway is that deadlock-resistant software is not defined by one algorithmic trick. It is defined by the combination of control depth, system transparency, and operational recoverability.
Red flags during supplier review
- No stress-test results above nominal traffic load.
- No explanation of how destination occupancy is managed.
- No event logs for blocked nodes, queue growth, or intervention history.
- Heavy dependence on manual dispatcher decisions to restore flow.
Implementation roadmap, common mistakes, and practical FAQ
The safest path is to treat deadlock prevention as a commissioning discipline rather than a post-go-live troubleshooting exercise. Facilities planning a new deployment or fleet expansion should validate layout topology, control parameters, and release policies before full cutover. A 3-phase approach is usually more reliable than a single launch event.
A practical 3-phase rollout model
- Phase 1: topology audit and simulation, including choke points, one-way conversions, and buffer adequacy checks.
- Phase 2: pilot commissioning with 20% to 40% of target mission load and forced obstruction scenarios.
- Phase 3: staged scale-up with weekly review of wait-state ratio, blocked-node recurrence, and manual intervention frequency.
During rollout, teams should maintain a change log for route rules, priority classes, charger logic, and WMS release pacing. Without this discipline, performance shifts are hard to trace, and the same deadlock issue may reappear under different labels.
Common mistakes that create avoidable deadlocks
One common mistake is adding vehicles before fixing control policy. If a site already shows queue spillback at 14 AGVs, increasing to 18 may worsen throughput instead of improving it. Another mistake is treating charger placement as a utilities issue rather than a traffic issue. Charger access should be analyzed like any other high-priority node with queue implications.
A third mistake is underestimating manual interaction. Pedestrian crossings, forklifts, pallet misalignment, and operator pauses can add stochastic delay. Traffic logic must be tuned for the real warehouse, not for a perfectly deterministic map.
How do we know whether deadlock risk is a software problem or a layout problem?
Usually it is both. If the same nodes repeatedly block under variable workloads, the layout likely lacks enough buffer or directional separation. If blocking spreads unpredictably across otherwise adequate space, the software may be reserving resources too aggressively or releasing tasks too early. Testing at 3 load levels often reveals the dominant cause.
What KPI targets should operators monitor after go-live?
Focus on wait-state ratio, average queue depth by zone, manual interventions per shift, and mission completion variance. As a practical starting point, many teams try to keep unplanned wait-state time below 5% to 8% of shift hours and manual recovery events below 1 to 3 per 100 missions in stable operations.
How long should a proper validation cycle take before full expansion?
For medium-complexity sites, 2 to 4 weeks of pilot validation is often the minimum, followed by another 2 to 6 weeks of progressive load increase. Very high-mix environments may require longer observation because deadlock patterns can appear only during rare but important order combinations.
Deadlock risk in AGV traffic control algorithms is not a niche software detail. It is a core throughput, reliability, and procurement issue for modern intralogistics. Teams that evaluate liveness, reservation logic, WMS release control, and recovery behavior early can avoid expensive retrofits, delayed ramp-ups, and hidden capacity loss.
For engineers, operators, and sourcing leaders, the most effective next step is to request a deadlock-focused technical review of your current or planned fleet architecture: layout topology, task orchestration, charger strategy, and control observability. To assess your warehouse management system wms integration or agv fleet management software oem roadmap with data-first rigor, contact TSV to discuss a tailored evaluation framework and solution path.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Oct 13, 2026Smart Cameras vs. PC-Based Machine Vision: Which Fits High-Speed Inspection?This industrial product comparison for machine vision weighs smart cameras vs. PC-based systems on latency, throughput, and cost. Discover your best fit for high-speed inspection.TSV Data Lab
 Oct 12, 2026How to Verify RoHS Compliance in Industrial Sensing Systems Before DeploymentRoHS compliant sensing systems: learn how to verify materials, supplier declarations, testing, and configuration controls before industrial deployment.TSV Data Lab
 Oct 11, 2026How Procurement-Oriented Content Taxonomy Improves B2B Buying JourneysProcurement-oriented content taxonomy streamlines B2B buying journeys with clearer evidence, supplier comparisons, risk visibility, and faster approvals.TSV Data Lab
 Oct 10, 2026How to Select a Machine Performance Monitoring Platform for OEE and Downtime ReductionMachine performance monitoring platform selection guide: validate machine states, OEE data, downtime reasons, integrations, and scalability to reduce losses with confidence.TSV Data Lab
 Oct 08, 2026How to Machine Inconel 625 Blades Without Heat Cracks or Edge ChippingInconel 625 blade machining guide: prevent heat cracks, edge chipping, chatter, and work hardening with proven tooling, cooling, fixturing, and inspection strategies.Dr. Marcus Vance
 Oct 07, 2026How to Evaluate an HMI Panel Distributor for Industrial Automation ProjectsHMI panel distributor evaluation guide: verify technical compatibility, traceability, supply reliability, lifecycle support, and total cost for automation projects.Victor Lin (Chief Software Architect)
 Oct 06, 2026Navigation Fault Tolerance Standards for AMRs: What Safety Teams Must VerifyNavigation fault tolerance standards: learn what AMR safety teams must verify, from localization loss and sensor faults to stopping distance, safe restart, and site-specific validation.Chen Wei (Automation Lead Engineer)
 Oct 05, 2026Calculating Edge Computing Total Cost of Ownership Across Distributed SitesEdge computing ownership cost explained: calculate deployment, energy, connectivity, security, remote support, and refresh costs across distributed sites.TSV Data Lab
 Oct 04, 2026CAD/CAM Benchmarking in the GCC: What Manufacturers Should Ask a ConsultantCAD CAM benchmark consultant GCC guide: learn the key questions manufacturers should ask to validate post-processors, workflows, machine performance, and production risk.Victor Lin (Chief Software Architect)
 Oct 03, 2026Selecting Automotive Radar Sensor Modules for ADAS Range, Resolution, and IntegrationAutomotive radar sensor module selection guide for ADAS: compare range, resolution, field of view, latency, and integration to build safer, reliable vehicle systems.TSV Data Lab
 Oct 02, 2026How to Qualify Machined Parts Suppliers for Hard Tech ProgramsHard tech supply chain machined parts demand rigorous supplier qualification. Learn how to assess capability, traceability, quality controls, and delivery resilience.Dr. Marcus Vance
 Oct 01, 2026How to Select an Outdoor Security Radar Sensor for Perimeter Detection?Outdoor security radar sensor selection guide: compare range, accuracy, false-alarm control, integration, and field testing for reliable perimeter detection.TSV Data Lab
 Sep 30, 2026How to Evaluate Solid-State LiDAR Hardware for Outdoor Autonomous VehiclesSolid state LiDAR hardware evaluation guide for outdoor autonomous vehicles—compare range, point-cloud quality, environmental resilience, integration, and safety.TSV Data Lab
 Sep 29, 2026ISO 9283 Repeatability: How to Evaluate Cobot Positioning PerformanceISO 9283 cobot repeatability explained: learn how payload, reach, approach direction, and test conditions affect positioning performance and cell capability.Chen Wei (Automation Lead Engineer)
 Oct 13, 2026How to keep an industrial robotic integration project on scheduleIndustrial robotic integration project management: keep automation on schedule with proven controls for interfaces, suppliers, FAT, commissioning, and change risk.Victor Lin (Chief Software Architect)
 Oct 12, 2026What should be included in predictive maintenance pricing for factories?Predictive maintenance pricing for factories: compare sensors, software, integration, support, and total cost to secure measurable uptime gains and avoid hidden expenses.TSV Data Lab
 Oct 11, 2026How payload and reach change the cost of an industrial robotCost of industrial robot systems depends heavily on payload and reach. Learn how sizing, torque, tooling, safety, and lifecycle factors shape smarter automation investments.Chen Wei (Automation Lead Engineer)























