
Warehouse management system integration gets harder after go live
Publication Date
author
Warehouse management system WMS integration often becomes more complex after go live, when hidden data gaps, workflow exceptions, and system dependencies start affecting operations. For teams evaluating MES integration with SAP ERP, industrial IoT dashboard visualization, AGV traffic control algorithm performance, or PLC control for packaging machinery, the real challenge is not deployment alone—it is sustaining accuracy, responsiveness, and cross-system visibility at scale.
Why WMS integration gets harder after go live
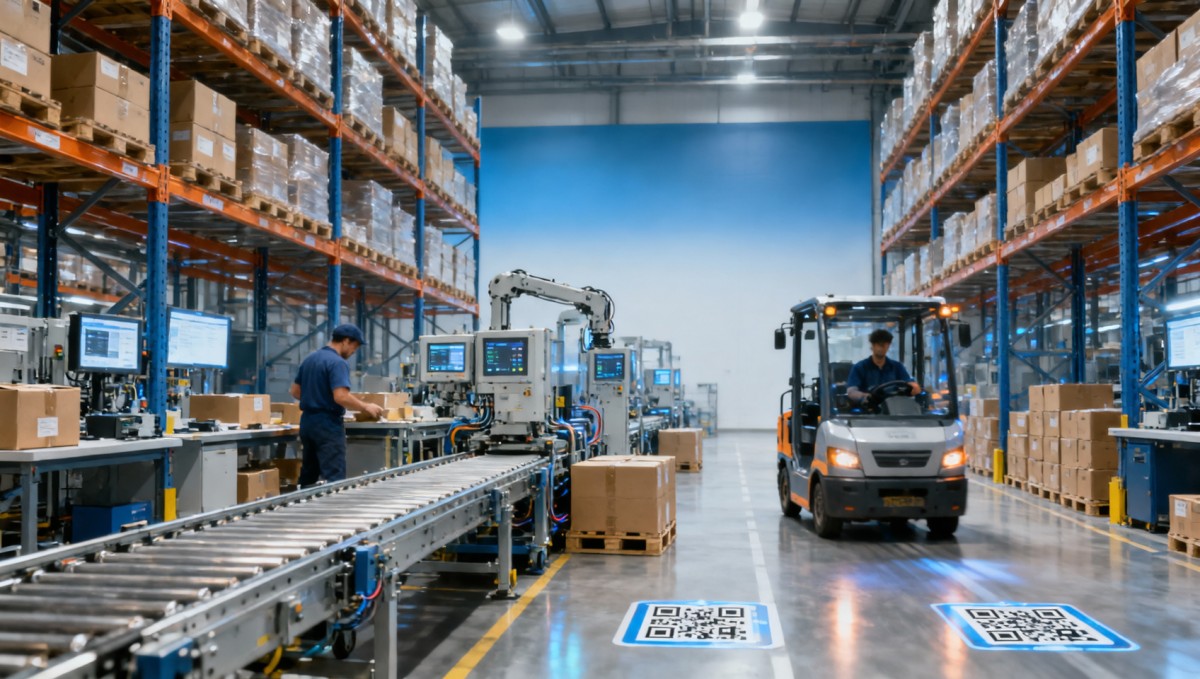
Many organizations assume the most difficult phase of warehouse management system integration is the initial interface build. In practice, the post-go-live period is where complexity surfaces. During the first 2–8 weeks of real operation, order exceptions, master data inconsistencies, delayed status feedback, and unexpected operator behavior expose dependencies that were not visible in test scripts.
This is especially true in mixed environments where WMS must exchange data with SAP ERP, MES, barcode systems, PLC-controlled packaging lines, AGV dispatch platforms, and industrial IoT dashboards. A workflow that looks stable in a controlled UAT environment can fail when thousands of scans, replenishment signals, and inventory movements happen across multiple shifts every day.
For operators, the pain appears as delayed confirmations, duplicate tasks, or mismatched stock locations. For procurement teams, the pain appears as support scope disputes and rising service costs after acceptance. For enterprise decision-makers, the biggest risk is that poor data synchronization quietly reduces inventory trust, on-time shipment performance, and production continuity.
The post-go-live reality is operational, not theoretical
At TechStat Vanguard, the core issue is not software branding but engineering truth. Parameters do not lie, and warehouse integration quality is measurable. Teams should track at least 4 categories after go live: message success rate, transaction latency, exception closure time, and data reconciliation accuracy between systems.
- Message success rate: monitor whether interface transactions complete within the expected sequence, not only whether they are technically sent.
- Latency window: many warehouse processes require feedback within seconds, while batch-style updates every 5–15 minutes may be operationally unacceptable.
- Exception closure time: unresolved interface errors older than 24 hours often create cumulative stock distortion.
- Reconciliation accuracy: location, lot, serial, quantity, and status should be aligned across WMS, ERP, and execution systems.
Which failure points appear first in multi-system warehouse environments?
The first post-go-live failures usually do not come from dramatic system crashes. They come from small mismatches repeated hundreds or thousands of times per day. A packaging PLC may report completion before WMS closes the shipment task. An AGV may wait for a location release that was updated in MES but not synchronized to the warehouse layer. An SAP ERP posting may succeed while the warehouse transaction remains pending.
In advanced manufacturing and hard-tech supply chains, these issues are amplified by lot traceability, compliance-driven records, and engineering change control. If one field is optional in one system but mandatory in another, integration starts accumulating manual workarounds. What looked like a configuration detail becomes a process bottleneck.
A useful way to diagnose integration maturity is to map where truth is created, where truth is copied, and where truth is merely displayed. WMS integration becomes fragile when the same stock status is maintained by 2–3 systems without a clear system of record.
Common fault domains after go live
The table below summarizes frequent post-go-live integration issues, their operational symptoms, and what teams should verify first. This is useful for information researchers comparing architectures, operators troubleshooting on the floor, and procurement teams defining service-level expectations.
The key lesson is simple: post-go-live warehouse management system integration is less about interface existence and more about sequence integrity. If status transitions are not engineered with exception handling, even a technically connected landscape can remain operationally unreliable.
Why dashboard visibility can be misleading
Industrial IoT dashboard visualization often gives managers a false sense of control. A screen can refresh every 30–60 seconds, yet still hide missing events, out-of-order transactions, or stale upstream data. Visibility is only trustworthy when dashboards expose source system timestamps, interface backlog counts, and exception aging bands such as under 1 hour, 1–4 hours, and over 4 hours.
How to evaluate WMS integration architecture before issues become expensive
For procurement and leadership teams, the best time to reduce post-go-live integration risk is before signing the final scope, not after escalation begins. A strong evaluation framework should compare integration architecture, support ownership, and operational test depth. This applies whether the warehouse serves e-commerce, industrial spare parts, aerospace components, or automated packaging output.
In data-driven environments, TSV recommends evaluating 5 decision layers: system of record definition, interface method, transaction criticality, exception workflow, and maintenance accountability. If any one of these is unclear, go-live success may not survive peak volume or engineering change cycles.
Teams often compare integration options only by implementation speed. That is incomplete. A direct API connection may reduce latency, but it can increase dependency sensitivity. Middleware can add governance and replay capability, but it also adds another diagnostic layer. The right choice depends on process criticality, not marketing labels.
Comparison of common integration approaches
The following comparison table helps cross-functional teams assess which warehouse integration approach is easier to sustain after go live, especially when SAP ERP, MES, AGVs, and packaging PLCs are all involved.
No method is universally superior. The procurement decision should be anchored in transaction tolerance: if a 30-second delay is acceptable, batch logic may work for some objects. If an AGV route release or packaging completion signal must update in near real time, the architecture must be designed accordingly and tested under realistic load.
Five checks before approving the final scope
- Define the source of truth for inventory, lot status, and shipment completion.
- Verify whether interface retries create duplicate business events.
- Require an exception matrix covering at least 10–15 common failure scenarios.
- Confirm who owns root-cause analysis when ERP, WMS, MES, and PLC logs disagree.
- Test during peak-like conditions across 2–3 shifts, not only in office-hour simulations.
What should operators, procurement teams, and executives monitor after go live?
Different stakeholders need different indicators. Operators need actionable signals they can resolve in minutes. Procurement teams need evidence for service review and vendor accountability. Executives need risk indicators that connect integration quality to fulfillment, production continuity, and customer impact. When everyone looks at the same dashboard but asks different questions, integration governance becomes weak.
A practical monitoring model uses 3 layers. Layer one is transaction health: success, failure, delay, and queue depth. Layer two is process health: pick completion, replenishment timing, dock release, packaging confirmation, and cycle count variance. Layer three is business effect: shipment delay, line starvation risk, and inventory confidence by zone or material class.
In hard-tech sectors, traceability fields such as lot, serial, revision, and inspection status should be monitored separately. A warehouse transaction can appear complete while still being non-compliant for aerospace, medical, or regulated industrial applications if traceability attributes are missing or stale.
A practical KPI set for the first 90 days
The first 30, 60, and 90 days after go live should not use the same KPI thresholds. Early stabilization needs a phased view. The table below provides a realistic framework for post-go-live warehouse management system integration monitoring.
This phased model helps avoid a common mistake: demanding mature KPI performance in week one while foundational defects are still being surfaced. The better approach is controlled stabilization, then optimization. Without that sequence, teams confuse temporary turbulence with permanent design failure.
Three warning signs that should trigger immediate review
- Inventory discrepancies persist beyond 2–3 reconciliation cycles and cannot be linked to a single upstream cause.
- Operators create manual bypass steps to keep shipments moving, but those steps are not logged in system governance.
- Automation teams and IT teams report different event timestamps for the same warehouse transaction.
FAQ: procurement, implementation, and risk control
Search intent around warehouse management system integration is rarely academic. Buyers want to know how to reduce risk, how long stabilization takes, and what to include in support scope. The following questions reflect common post-go-live concerns across manufacturing, logistics, and automated warehouse projects.
How long does WMS stabilization usually take after go live?
A realistic stabilization period often ranges from 2–6 weeks for moderate complexity and longer for heavily automated sites. The duration depends on the number of connected systems, the volume of daily transactions, and whether traceability rules are strict. Plants with SAP ERP, MES, AGV control, and PLC-linked packaging lines should expect a phased review model rather than assuming the system is fully stable within a few days.
What should be included in a procurement checklist for post-go-live support?
At minimum, the contract or statement of work should specify incident severity definitions, response windows, log access responsibilities, replay or reprocessing rules, root-cause ownership, and data reconciliation support. It should also clarify whether support covers only interface transport or full business process validation. That distinction becomes critical when a transaction is technically delivered but operationally wrong.
Is MES integration with SAP ERP enough to protect warehouse accuracy?
Not by itself. MES integration with SAP ERP helps align production and enterprise records, but warehouse accuracy also depends on real-time execution events, scan discipline, packaging state control, and automation feedback. If WMS is not tightly coordinated with material movement and status transitions, ERP alignment alone will not prevent stock distortion or dispatch delays.
Why do AGV and PLC integrations cause hidden WMS issues?
Because physical automation exposes timing assumptions very quickly. AGV traffic control algorithms, conveyor logic, and PLC control for packaging machinery operate on state changes that may happen in seconds. If WMS updates are delayed, missing, or out of sequence, automation either waits unnecessarily or moves goods based on stale instructions. The result is not only inefficiency but traceability risk.
What is the most common misconception after deployment?
The most common misconception is that “interfaces are up” means the integration is complete. Real success means transactions are timely, statuses are consistent, exceptions are visible, and process owners know how to recover without creating manual chaos. Connectivity is the beginning, not the proof of reliability.
Why data-driven evaluation matters before your next integration decision
TechStat Vanguard approaches warehouse integration the same way we approach robotics, edge AI, aerospace systems, and precision industrial benchmarking: through measurable engineering truth. In a market crowded with broad claims, buyers need sharper filters. They need to know transaction tolerance, failure modes, synchronization windows, and traceability dependencies before selecting a platform, integration partner, or automation architecture.
If your team is comparing WMS integration options, reviewing MES integration with SAP ERP, validating industrial IoT dashboard visualization logic, or checking AGV and PLC coordination requirements, a parameter-based review can reduce trial-and-error cost and shorten supplier qualification cycles. That is especially important when warehouse performance directly affects production uptime, compliance records, or high-value shipment integrity.
A useful next step is not a generic product pitch. It is a structured technical discussion around 4 items: your current system landscape, your high-risk process nodes, your required response windows, and your acceptance criteria after go live. With those inputs, integration decisions become easier to compare and easier to defend internally.
Why choose us for integration evaluation and sourcing research
TSV helps engineering teams, procurement leaders, and enterprise decision-makers cut through noise by focusing on what can actually be verified. You can contact us to discuss interface parameter confirmation, architecture comparison, post-go-live risk review, supplier evaluation criteria, delivery-cycle expectations, traceability field mapping, and automation coordination checkpoints. If you are preparing a new warehouse project or trying to stabilize an existing one, we can help frame the technical questions that matter before budget, scope, and operational risk drift further apart.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Oct 15, 2026R&D Cost Reduction Services: How to Evaluate Fees, Savings, and ROIEvaluate R&D cost reduction services with confidence. Compare fees, verify savings, and calculate ROI without compromising performance. Discover how to choose a provider that delivers real value.Chen Wei (Automation Lead Engineer)
 Oct 14, 2026Drone Frame Composites: Carbon Fiber vs. Fiberglass for Weight and StiffnessExplore drone structural materials composites: compare carbon fiber and fiberglass for weight, stiffness, cost, and antenna compatibility. Find the right material for your drone frame.Elena Rostova (UAV Systems Researcher)
 Oct 13, 2026Smart Cameras vs. PC-Based Machine Vision: Which Fits High-Speed Inspection?This industrial product comparison for machine vision weighs smart cameras vs. PC-based systems on latency, throughput, and cost. Discover your best fit for high-speed inspection.TSV Data Lab
 Oct 12, 2026How to Verify RoHS Compliance in Industrial Sensing Systems Before DeploymentRoHS compliant sensing systems: learn how to verify materials, supplier declarations, testing, and configuration controls before industrial deployment.TSV Data Lab
 Oct 11, 2026How Procurement-Oriented Content Taxonomy Improves B2B Buying JourneysProcurement-oriented content taxonomy streamlines B2B buying journeys with clearer evidence, supplier comparisons, risk visibility, and faster approvals.TSV Data Lab
 Oct 10, 2026How to Select a Machine Performance Monitoring Platform for OEE and Downtime ReductionMachine performance monitoring platform selection guide: validate machine states, OEE data, downtime reasons, integrations, and scalability to reduce losses with confidence.TSV Data Lab
 Oct 08, 2026How to Machine Inconel 625 Blades Without Heat Cracks or Edge ChippingInconel 625 blade machining guide: prevent heat cracks, edge chipping, chatter, and work hardening with proven tooling, cooling, fixturing, and inspection strategies.Dr. Marcus Vance
 Oct 07, 2026How to Evaluate an HMI Panel Distributor for Industrial Automation ProjectsHMI panel distributor evaluation guide: verify technical compatibility, traceability, supply reliability, lifecycle support, and total cost for automation projects.Victor Lin (Chief Software Architect)
 Oct 06, 2026Navigation Fault Tolerance Standards for AMRs: What Safety Teams Must VerifyNavigation fault tolerance standards: learn what AMR safety teams must verify, from localization loss and sensor faults to stopping distance, safe restart, and site-specific validation.Chen Wei (Automation Lead Engineer)
 Oct 05, 2026Calculating Edge Computing Total Cost of Ownership Across Distributed SitesEdge computing ownership cost explained: calculate deployment, energy, connectivity, security, remote support, and refresh costs across distributed sites.TSV Data Lab
 Oct 04, 2026CAD/CAM Benchmarking in the GCC: What Manufacturers Should Ask a ConsultantCAD CAM benchmark consultant GCC guide: learn the key questions manufacturers should ask to validate post-processors, workflows, machine performance, and production risk.Victor Lin (Chief Software Architect)
 Oct 03, 2026Selecting Automotive Radar Sensor Modules for ADAS Range, Resolution, and IntegrationAutomotive radar sensor module selection guide for ADAS: compare range, resolution, field of view, latency, and integration to build safer, reliable vehicle systems.TSV Data Lab
 Oct 02, 2026How to Qualify Machined Parts Suppliers for Hard Tech ProgramsHard tech supply chain machined parts demand rigorous supplier qualification. Learn how to assess capability, traceability, quality controls, and delivery resilience.Dr. Marcus Vance
 Oct 01, 2026How to Select an Outdoor Security Radar Sensor for Perimeter Detection?Outdoor security radar sensor selection guide: compare range, accuracy, false-alarm control, integration, and field testing for reliable perimeter detection.TSV Data Lab
 Sep 30, 2026How to Evaluate Solid-State LiDAR Hardware for Outdoor Autonomous VehiclesSolid state LiDAR hardware evaluation guide for outdoor autonomous vehicles—compare range, point-cloud quality, environmental resilience, integration, and safety.TSV Data Lab
 Sep 29, 2026ISO 9283 Repeatability: How to Evaluate Cobot Positioning PerformanceISO 9283 cobot repeatability explained: learn how payload, reach, approach direction, and test conditions affect positioning performance and cell capability.Chen Wei (Automation Lead Engineer)
 Oct 14, 2026How tight can micro machining aerospace tolerances be in production?Micro machining aerospace tolerances can reach low-micron levels in production. Learn what controls repeatability, inspection confidence, and flight-critical quality.Dr. Marcus Vance























