Predictive maintenance pricing should give factory procurement teams more than a software quote. It should define measurable engineering value, deployment obligations, operating assumptions, and accountability for results.
Buyers need to compare sensor coverage, data quality, edge infrastructure, integration effort, support commitments, and expected downtime reduction using verifiable criteria rather than broad vendor claims.
Start With the Full Scope of Predictive Maintenance Pricing
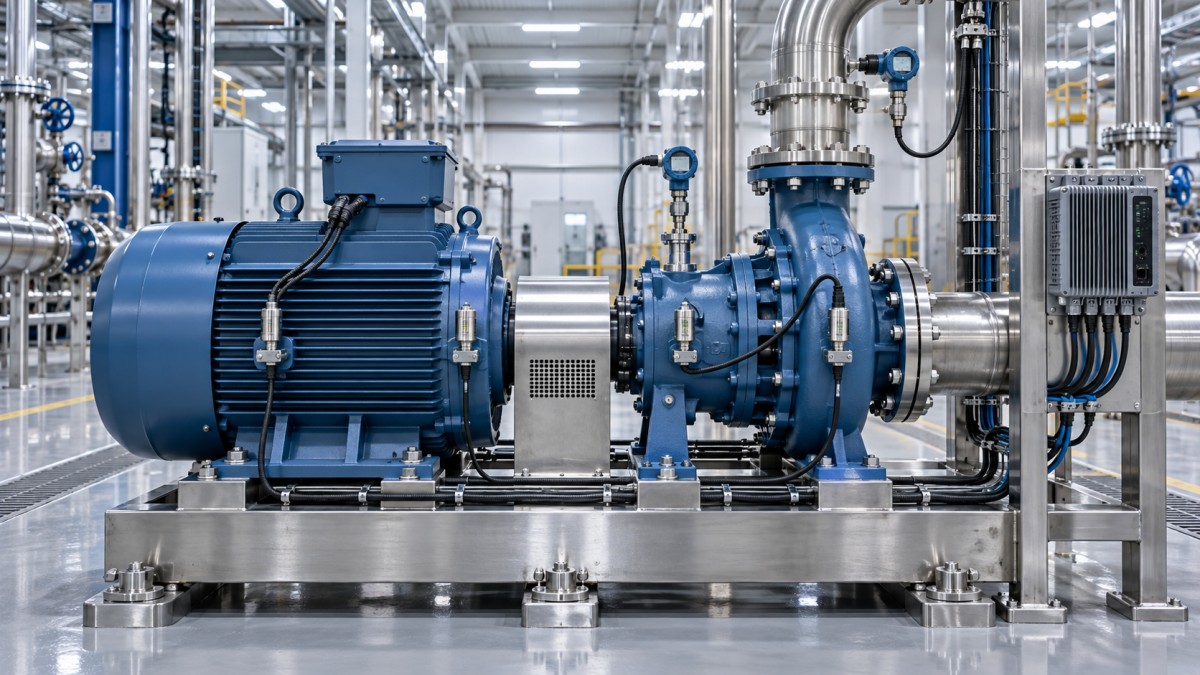
For procurement teams, predictive maintenance pricing is not a single subscription number. It is the total commercial model required to turn machine condition data into dependable maintenance decisions.
A credible proposal separates one-time implementation charges from recurring operating costs. It also identifies customer responsibilities, third-party costs, data ownership rules, and commercial assumptions behind projected returns.
This distinction matters because a low annual platform fee can conceal expensive installation work, gateway hardware, engineering services, systems integration, or mandatory support packages.
The first request for proposal should therefore require an itemized bill of materials and services. Avoid accepting combined labels such as “full solution,” “deployment bundle,” or “enterprise package.”
Each line item should identify quantity, unit price, expected service life, warranty coverage, renewal rules, and whether pricing changes with assets, sites, users, data volume, or analytics modules.
Procurement should also ask vendors to state what is excluded. Common exclusions include electrical work, mounting fabrication, wireless surveys, network upgrades, historian access, PLC programming, and plant shutdown windows.
A transparent predictive maintenance pricing structure gives operations, engineering, information technology, and finance teams a shared basis for approval before any purchase order is issued.
Include Sensor Hardware, Coverage Design, and Installation Costs
Sensor hardware is frequently the most visible component of a predictive maintenance proposal. Yet the important question is not simply how many sensors are quoted.
Buyers should understand which failure modes each sensor is intended to detect. Vibration, temperature, ultrasound, current, oil condition, pressure, and acoustic signals serve different diagnostic purposes.
For rotating equipment, a vibration sensor may detect bearing degradation or imbalance. It may not, without suitable measurement design, identify lubrication contamination or process-related cavitation.
Every proposal should map critical assets to sensors, measurement points, sampling frequency, expected fault coverage, and the rationale for selecting those locations.
Ask whether sensor placement follows an asset criticality study, failure mode and effects analysis, or a vendor standard template. Generic placement can reduce diagnostic reliability.
Hardware pricing should distinguish sensors, mounting accessories, cables, enclosures, power supplies, calibration equipment, spare units, and environmental protection for heat, washdown, dust, or hazardous areas.
Factories should verify ingress protection ratings, operating temperature limits, battery replacement requirements, wireless range assumptions, and electromagnetic compatibility with existing industrial equipment.
Installation should be separately priced, including site surveys, mounting, electrical labor, lockout procedures, commissioning, and any production interruption required to access equipment safely.
For large facilities, ask for a phased rollout price. A pilot on representative assets can validate sensor performance before the supplier prices a plant-wide deployment.
Price the Edge, Network, and Data Infrastructure Explicitly
Condition monitoring only produces value when machine data reaches the analytics environment reliably. Edge devices, gateways, connectivity, cybersecurity, and storage must therefore appear clearly in the quote.
Edge computing charges may include industrial gateways, embedded processors, protocol converters, local databases, device management licenses, and software used to process signals before transmission.
Procurement should determine whether the proposed architecture sends raw waveform data, summarized features, alarms, or model outputs to the cloud. This choice affects bandwidth, storage, and future diagnostic flexibility.
Raw vibration data can support deeper investigation, but it raises storage and transmission costs. Feature-based transmission may be cheaper while limiting later analysis of unusual faults.
Network assumptions need equal attention. Vendors should identify required Wi-Fi coverage, cellular subscriptions, Ethernet ports, VLAN configuration, firewall rules, and any dependence on public internet access.
Where facilities operate in remote locations or regulated environments, buyers should compare cloud, private cloud, on-premises, and hybrid deployment pricing using the same data retention assumptions.
Cybersecurity costs should not be treated as an afterthought. Include authentication, encryption, patch management, vulnerability monitoring, remote access controls, and incident response responsibilities.
Request a lifecycle estimate for gateways and network devices. Replacements, firmware support, cellular contracts, certificates, and operating-system updates can materially change total ownership cost.
Examine Software Licenses and Analytics Performance Claims
Predictive maintenance software is often priced by monitored asset, sensor, facility, named user, data volume, or feature tier. Buyers should model each pricing method against expected expansion.
An asset-based license can be straightforward when equipment inventories are stable. It becomes less predictable when sites frequently add production lines, temporary equipment, or duplicate monitoring points.
Software pricing should identify included functions: dashboards, alarm management, mobile access, root-cause workflows, reporting, historical trending, work-order integration, model training, and application programming interfaces.
Clarify whether advanced analytics are included or separately licensed. Suppliers may charge additional fees for anomaly detection, bearing fault classification, remaining useful life estimates, or custom machine-learning models.
More important than a feature list is evidence of performance. Require the vendor to define alert precision, missed-fault rate, false-alarm rate, detection lead time, and confidence thresholds.
These metrics should be tied to specific asset classes and operating conditions. A model trained on clean, constant-speed motors may perform poorly on variable-speed, intermittent, or heavily loaded machinery.
Ask how the platform handles missing data, sensor drift, changing production recipes, maintenance interventions, and equipment operating outside its normal load envelope.
A useful commercial agreement defines remediation when analytics fail to meet agreed acceptance criteria. This may include retuning services, additional data collection, replacement hardware, or service credits.
Account for Integration With Existing Factory Systems
Integration is commonly underestimated in predictive maintenance pricing. The system must fit into existing maintenance and operational workflows before alerts can reduce unplanned downtime.
Factories should identify all required connections, including computerized maintenance management systems, enterprise asset management platforms, historians, manufacturing execution systems, supervisory control systems, and data lakes.
Each interface should state the required data direction, protocol, frequency, security method, ownership, testing method, and party responsible for resolving connection failures.
For example, generating work orders in a CMMS requires more than sending an email alert. The integration must map asset identifiers, failure codes, priority rules, assigned teams, and closure feedback.
Closure feedback is commercially important because it improves validation. Without confirmation of actual fault findings, the vendor cannot reliably calculate alert accuracy or continuously refine diagnostic models.
Ask whether the quoted integration uses standard connectors or custom development. Standard connectors may accelerate deployment, while custom work needs defined milestones, acceptance tests, and change-control rates.
Also evaluate master data readiness. Inconsistent equipment naming, incomplete asset hierarchies, and outdated maintenance records can create implementation delays that vendors later bill as additional services.
A responsible proposal specifies the number of interfaces included, engineering hours allocated, data-cleaning assumptions, and hourly rates that apply when project scope changes.
Define Services, Training, and Support Commitments
Predictive maintenance technology does not replace maintenance expertise. Pricing should include the people and processes needed to interpret alerts, inspect equipment, plan interventions, and verify outcomes.
Implementation services should cover project management, asset criticality review, configuration, baseline data collection, alarm setup, commissioning, acceptance testing, and documentation delivered at project close.
Buyers should ask whether initial model configuration relies on vendor analysts, automated templates, customer engineers, or a combination. Each model has different labor costs and time requirements.
Training should be priced by role. Maintenance technicians need practical alert interpretation, while planners need workflow training and managers need reporting methods for availability, savings, and program performance.
Support service levels must specify response times, support hours, escalation routes, remote diagnostics, onsite availability, software update policy, and whether support covers both technology and analytical advice.
For critical production assets, procurement may need a premium support tier with 24-hour incident response. That cost should be evaluated against the financial exposure of an extended production outage.
Ask whether condition analysts review alerts routinely. A platform with expert validation can reduce nuisance alarms, but the service must state review frequency, scope, and named accountability.
Renewal pricing deserves attention. Cap annual increases where possible, define renewal notice periods, and ensure the factory can export historical data and configuration records at contract termination.
Build a Business Case From Avoided Losses, Not Vendor Percentages
Procurement leaders should challenge broad promises such as “reduce downtime by 30 percent.” The commercial case must connect predictive maintenance spending to the factory’s own operating economics.
Start by identifying critical assets whose failure interrupts production, compromises quality, creates safety exposure, delays shipments, or requires expensive emergency repair and spare-part logistics.
For each asset, estimate the cost of an unplanned event. Include lost contribution margin, labor, overtime, scrapped material, expedited freight, repair parts, contractor costs, and downstream scheduling disruption.
Then estimate the realistic failure modes that monitoring can detect early. The value calculation should exclude failures beyond the selected sensor coverage or faults that cannot be prevented operationally.
Expected benefit should reflect probability, not certainty. A conservative model uses historical failure frequency, anticipated detection lead time, maintenance response capability, and the likelihood of avoiding full disruption.
Separate hard savings from capacity gains. Avoided repair invoices and reduced scrap are easier to verify, while increased throughput may require evidence that the plant can actually sell additional output.
Include internal labor costs as well. New systems require staff time for reviewing alerts, conducting inspections, correcting data, attending training, and managing suppliers during the early deployment phase.
A pilot should have predefined success measures, such as validated fault detections, false-alarm rates, lead time before failure, maintenance actions completed, and avoided costs documented jointly.
Compare Suppliers Using a Normalized Total Cost Framework
Supplier comparison becomes misleading when one proposal bundles services and another separates them. Procurement should normalize all bids into a common three-year or five-year total cost model.
The model should include capital hardware, installation, implementation services, software subscriptions, data storage, connectivity, integration, support, training, replacements, and expected expansion costs.
Create a scenario for the initial pilot, one for the approved rollout, and one for a likely future scale-up. This reveals pricing structures that become expensive as adoption grows.
Evaluate technical scope beside cost. A lower-priced offer that monitors fewer failure modes, excludes critical assets, or provides weak support may create a cheaper contract but a poorer maintenance outcome.
Use weighted scorecards that include demonstrated diagnostic accuracy, integration maturity, cybersecurity evidence, engineering support, commercial transparency, implementation timeline, and references from similar industrial environments.
Vendor references should be specific. Ask about asset types, operating conditions, deployment duration, alert quality, installation disruption, support responsiveness, and whether promised integration milestones were met.
Where possible, request access to anonymized performance reports. A supplier should be able to show how it calculates avoided downtime, validates diagnoses, and distinguishes confirmed findings from unverified alerts.
Contract Terms That Protect Factory Buyers
A strong predictive maintenance agreement defines delivery acceptance, not just payment timing. Acceptance should cover installed hardware, data availability, integration tests, trained users, documentation, and agreed reporting capabilities.
Require clear data rights. The factory should retain access to raw and processed condition data, asset metadata, alarm history, reports, and configurations needed to maintain operational continuity.
Clarify ownership of models and derived insights. Vendors may protect proprietary algorithms, but customers need usable outputs and portable records if they later change technology providers.
Contracts should define warranty terms for sensors and gateways, replacement turnaround, calibration expectations, obsolescence management, and the supplier’s obligations when cellular or software components are discontinued.
Include change-control procedures for added assets, new sites, new integrations, altered production processes, and changes in cybersecurity requirements. Undefined changes are a common source of budget overruns.
Finally, establish governance. Quarterly reviews should assess system availability, data completeness, alert performance, confirmed savings, unresolved issues, roadmap changes, and whether the original business case remains credible.
Make Pricing a Test of Engineering Accountability
Good predictive maintenance pricing makes every cost traceable to a technical capability, implementation activity, or ongoing operational responsibility. That transparency is more valuable than an attractive headline discount.
Factory procurement teams should seek proposals that explain what will be monitored, how data will travel, who will act on alerts, and how results will be measured after deployment.
The right supplier is not necessarily the one with the lowest software fee. It is the one whose scope, assumptions, engineering evidence, and commercial commitments survive detailed scrutiny.
When buyers normalize total cost, test performance claims, and contract for measurable deliverables, predictive maintenance becomes a controlled industrial investment rather than another unclear digital transformation expense.