
Modbus RTU to MQTT gateway issues that appear after scaling
Publication Date
author
As deployments expand from a few nodes to plant-wide networks, a modbus rtu to mqtt gateway can expose hidden bottlenecks in industrial IoT gateway latency, IoT gateway throughput benchmark, and edge computing power consumption. This article explains why scaling triggers data loss, polling delays, topic congestion, and protocol mismatches—and what engineers, operators, buyers, and decision-makers should verify before reliability and ROI start to slip.
The core search intent behind this topic is practical diagnosis and decision support: readers are not asking what a Modbus RTU to MQTT gateway is, but why a system that worked in a pilot starts failing after rollout. They want to know which scaling problems are normal, which are design flaws, how to troubleshoot them quickly, and how to evaluate whether the gateway, network architecture, or integration strategy is still fit for purpose.
For operators and engineers, the urgent concerns are usually missed data, longer polling cycles, unstable MQTT publishing, device timeouts, RS-485 bus collisions, and CPU or memory saturation at the edge. For procurement teams and enterprise decision-makers, the real concern is different but related: whether the chosen gateway can support future expansion without hidden costs, retrofit delays, or reliability risks that erode production visibility and return on investment.
The most useful way to address this topic is to focus on the failure patterns that only appear after scaling, the measurable indicators behind them, and a practical checklist for troubleshooting and gateway selection. Broad protocol overviews should be kept brief. What matters most is identifying bottlenecks, validating performance under realistic load, and understanding how architecture choices affect long-term stability.
Why a Modbus RTU to MQTT gateway often works in pilots but fails after scaling
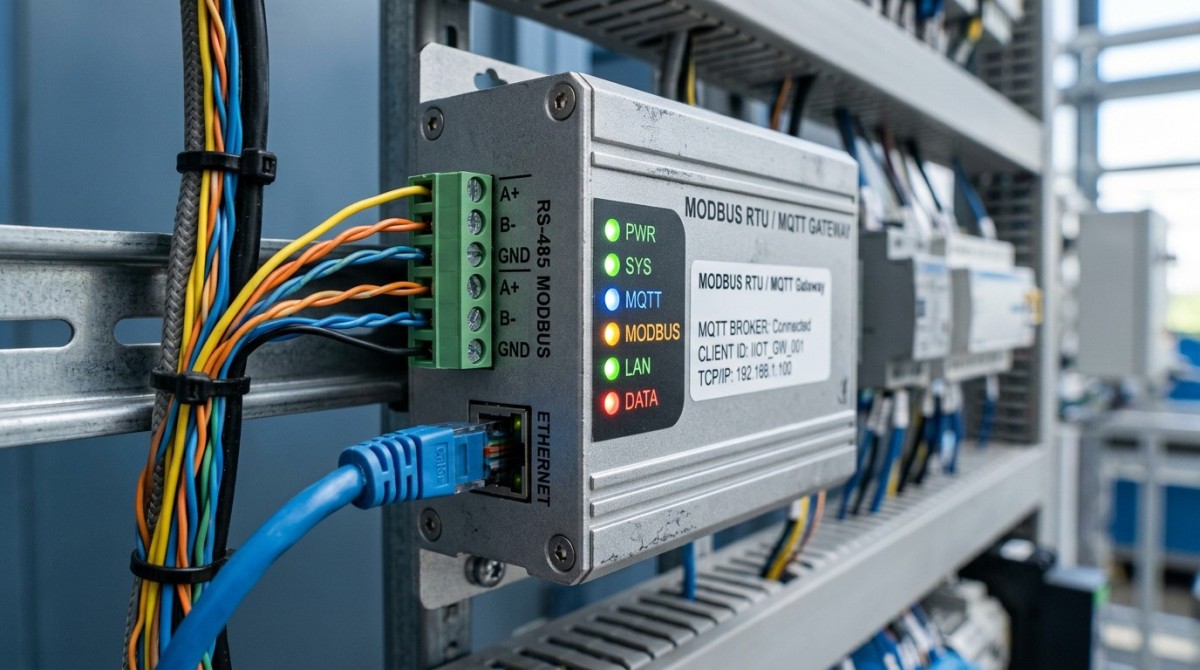
A small deployment can hide structural weaknesses. With only a few serial devices, a modbus rtu to mqtt gateway may appear stable because polling intervals are short, register maps are simple, message volume is low, and the broker is not under stress. Once the deployment expands across a workshop, line, or plant, those same assumptions break.
The usual pattern is straightforward: more devices mean longer Modbus polling cycles, more MQTT topics, more frequent payload conversion, and higher CPU, memory, and network demand on the gateway. At that point, issues that were statistically invisible in the pilot begin to surface:
- Data arrives late because serial polling time increases faster than expected
- Some values disappear because request queues overflow or timeout thresholds are poorly tuned
- MQTT publishing becomes bursty, creating topic congestion and delayed dashboards
- Protocol translation logic consumes more resources than anticipated
- RS-485 wiring quality, grounding, and termination problems become more visible under heavy polling
In other words, scaling does not create entirely new physics. It exposes capacity limits and design shortcuts. This is why engineers should stop treating pilot stability as proof of production readiness.
What problems typically appear first when the network grows
Most large-scale failures do not begin as total outages. They begin as subtle degradation. Recognizing the first symptoms early can prevent months of unreliable data collection.
1. Polling delay grows beyond process tolerance
Modbus RTU is a serial, master-driven protocol. Every additional slave and register block adds transaction time. If the gateway must collect data from many devices over one or several RS-485 segments, the scan cycle may stretch from seconds to tens of seconds or longer. That is unacceptable for alarms, fast-changing process values, or edge analytics workflows that depend on near-real-time updates.
2. Intermittent data loss appears under peak load
At scale, gateways often drop messages not because the network is completely broken, but because internal queues, buffers, or protocol conversion threads become saturated. These failures are easy to miss if dashboards simply display the last known value instead of flagging stale timestamps.
3. MQTT topic explosion creates broker and subscriber inefficiency
Many deployments start with simple topic structures. When the number of devices and tags grows, topic naming becomes inconsistent, subscriptions become too broad, retained messages accumulate unnecessarily, and broker performance declines. The gateway may still be functioning, but the surrounding MQTT ecosystem becomes harder to manage and slower to consume.
4. Edge CPU and memory utilization become a hidden bottleneck
Protocol conversion is not free. A gateway that reads Modbus registers, scales engineering values, timestamps data, packages JSON payloads, encrypts sessions, and republishes to MQTT is doing real computation. Under scale, industrial IoT gateway latency often increases because resource headroom was never properly benchmarked.
5. Serial layer issues become impossible to ignore
In small tests, poor RS-485 wiring may seem acceptable. At scale, marginal baud rate settings, improper line termination, duplicate node IDs, noise, grounding faults, or long cable runs cause retries and timeouts that amplify polling delay. The result looks like a software problem, but the root cause is often physical-layer integrity.
Root causes engineers should verify before blaming the gateway itself
Not every scaling issue means the gateway hardware is bad. In many cases, the gateway is just the point where system stress becomes visible. Engineers should isolate the problem into five layers.
Modbus map design
If register requests are fragmented, inefficient, or include unnecessary polling of static values, transaction counts rise sharply. Consolidating contiguous registers and separating slow-changing from fast-changing data can dramatically reduce load.
RS-485 network design
Bus topology, shielding, grounding, line length, baud rate, and device quality all affect the practical transaction success rate. A gateway cannot compensate for a physically unstable serial segment.
Gateway processing capacity
Check CPU usage, RAM usage, thread saturation, queue depth, store-and-forward behavior, and payload generation overhead. If the device is also running edge logic, security services, or local visualization, available resources may be much lower than expected.
MQTT broker and topic architecture
If the broker is overloaded, if QoS levels are too high for the data importance, or if topic design causes inefficient subscriptions, end-to-end performance suffers even when serial polling is healthy.
Cloud or SCADA integration logic
Sometimes the issue is downstream. Overly large JSON payloads, redundant publishing, weak timestamp handling, or poor ingestion pipeline design can create delays that get misdiagnosed as gateway problems.
How to assess industrial IoT gateway latency and throughput in real conditions
Vendors often publish gateway specifications under ideal conditions. Those numbers are rarely sufficient for plant-wide decisions. A meaningful IoT gateway throughput benchmark must reflect the actual deployment profile.
At minimum, test these conditions:
- Number of Modbus slaves per serial segment
- Registers read per device and read frequency
- Baud rate and line quality
- Payload size after Modbus-to-MQTT conversion
- MQTT QoS level, retained message strategy, and broker distance
- TLS or certificate overhead if secure publishing is enabled
- Concurrent edge logic, local buffering, or protocol bridging tasks
Three performance indicators matter most:
- End-to-end latency: time from field value change to MQTT consumer visibility
- Sustained throughput: stable message rate without queue growth or message loss
- Recovery behavior: how the gateway behaves after network interruption, broker disconnect, or serial timeout storms
For operations teams, this matters because poor latency creates false confidence in dashboards. For management, it matters because underperforming gateways increase troubleshooting labor, lower trust in data, and can delay broader digitalization programs.
Why edge computing power consumption becomes part of the scaling problem
Power consumption is often ignored until the deployment expands to many cabinets, remote panels, or constrained edge sites. Yet edge computing power consumption becomes important when gateways are expected to perform local normalization, filtering, buffering, encryption, and protocol conversion continuously.
A more heavily loaded gateway generally consumes more power and generates more heat. In industrial enclosures, this can affect thermal reliability, component lifespan, and cooling requirements. If the device sits in remote or energy-sensitive installations, power overhead may also influence backup sizing and uptime during outages.
This is especially relevant when buyers compare low-cost gateways with higher-performance industrial units. A cheaper gateway may appear attractive on paper, but if it runs near capacity after expansion, the system can become less efficient, less reliable, and more expensive to maintain.
What operators can do to reduce failures before a redesign is needed
Not every scaling issue requires immediate replacement. In many cases, operational tuning can restore stability or at least clarify whether a redesign is necessary.
Prioritize data by business importance
Not every register needs sub-second polling. Separate critical control-adjacent data, alarm-related values, and slowly changing status points. Polling everything at the same rate is one of the most common causes of unnecessary load.
Optimize Modbus request grouping
Where possible, read contiguous registers in fewer requests. Reduce fragmented access patterns that waste serial transaction time.
Segment the network
If too many slaves share one serial line, split them across multiple gateways or serial ports. Smaller segments often improve determinism and fault isolation.
Refine MQTT topic design
Use a consistent topic hierarchy based on site, line, machine, and signal class. Avoid oversized payloads and broad wildcard subscriptions that create unnecessary broker traffic.
Review QoS and retained message settings
Higher QoS is not always better. Use it where data assurance matters, but avoid applying conservative settings to every low-value status update.
Monitor staleness, not just connectivity
A connected gateway can still be delivering outdated data. Alarm on timestamp age, queue depth, timeout count, and scan cycle drift, not merely device online status.
What buyers and decision-makers should ask before purchasing for large deployments
If the planned use case may grow beyond a pilot, procurement and leadership teams should evaluate gateways based on scaling evidence, not just protocol compatibility.
Ask vendors or integrators these questions:
- What is the tested number of Modbus devices and polling frequency under sustained MQTT publishing?
- What industrial IoT gateway latency figures are available under real-world load, not only lab conditions?
- Is there a documented IoT gateway throughput benchmark with payload size, QoS, and security assumptions clearly stated?
- How does the gateway behave during broker outages or serial communication faults?
- What local buffering and store-and-forward capacity exists?
- How are CPU, memory, and diagnostics exposed for ongoing maintenance?
- Can the device support future edge logic without compromising protocol performance?
- What is the expected edge computing power consumption at normal and peak workload?
For enterprise buyers, the most important insight is this: a gateway should be evaluated as infrastructure, not as a simple converter. Once it becomes the bridge between legacy field devices and modern data systems, its limitations directly affect reporting accuracy, troubleshooting speed, and the scalability of the entire industrial data strategy.
A practical decision framework: tune, segment, or replace?
When issues appear after scaling, the right response depends on where the bottleneck lies.
Tune the existing system if the main problems are inefficient polling, poor topic structure, misconfigured QoS, or unnecessary data volume.
Segment the architecture if the serial network is overcrowded, if different production areas have different latency needs, or if fault isolation is currently weak.
Replace or upgrade the gateway if CPU headroom is consistently low, if sustained throughput is below operational requirements, if diagnostics are inadequate, or if resilience during outages is poor.
In practice, many plant-wide systems need a combination of all three. The key is to make that decision from measured evidence rather than assumptions formed during a small pilot.
Conclusion
When a modbus rtu to mqtt gateway starts showing issues after scaling, the problem is rarely just “more devices.” What scaling really does is expose hidden limits in serial design, polling strategy, MQTT architecture, gateway compute resources, and operational assumptions. The most reliable way forward is to measure end-to-end latency, sustained throughput, timeout behavior, queue health, and power implications under real deployment conditions.
For engineers and operators, this means focusing on register efficiency, segment stability, and timestamp-based monitoring. For buyers and decision-makers, it means demanding clear performance evidence, not generic compatibility claims. A gateway that performs well at scale is not simply a protocol bridge—it is a reliable data infrastructure component that protects visibility, uptime, and ROI as industrial systems grow.
Search News
Hot Articles
- Carbon Fiber StructuresHow to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsJul 11, 2026
- Machine VisionXiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsMar 30, 2026
- Cobots & ArmsShanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsMar 30, 2026
Popular Tags
Recommended News
 Jul 11, 2026How to Specify Aerospace Carbon Fiber Assemblies for Lightweight, Load-Bearing PartsAerospace carbon fiber assemblies: learn how to specify laminate design, load data, joining methods, and inspection controls for lighter, reliable load-bearing aerospace parts.Elena Rostova (UAV Systems Researcher)
 Mar 30, 2026Xiaomi, Alibaba DAMO Academy Drive Open-Source Robotics Model Ecosystem, Lowering Algorithm Development Barriers for Overseas SMEs Adopting Chinese Robotics SolutionsXiaomi & Alibaba DAMO Academy's open-source robotics models lower algorithm barriers for global SMEs. Boost efficiency in manufacturing, logistics & smart retail with ROS 2 compatible solutions.TSV Data Lab
 Mar 30, 2026Shanxi 'AI+' Conference Showcases Embodied Intelligence with Multinational Buyer Engagement: Key Industry ImplicationsShanxi 'AI+' Conference highlights embodied intelligence with Tesla, Ubtech & Jiantao showcasing multimodal robotics. 40+ global buyers validated tech on-site, creating new B2B channels for industrial automation & AI solutions.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Zhongguancun Unveils 6G Integrated Sensing-Computing-Intelligence Platform to Empower Embodied Robots for Global Industrial ApplicationsZhongguancun's new 6G platform revolutionizes industrial robotics with <10ms latency, empowering global automotive, logistics & port automation. Discover how this tech boosts China's smart manufacturing exports.TSV Data Lab
 Mar 30, 2026Mech-Mind Tianjin Embodied Intelligence R&D and Production Base Goes Live, Cutting Delivery Time by 20%–30% for Global Customized AMR+Vision SolutionsMech-Mind's Tianjin AMR+Vision production base cuts delivery time by 20%-30% for欧美 & Latin American markets. Discover how this PLd-certified facility accelerates customized robotics solutions for smart manufacturing and logistics.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026Boao Forum Reveals 'Co-evolution of Big and Small Brains' Trend in Humanoid Robots, China's Embodied Intelligence Accelerates Adaptation to Overseas Manufacturing Service ScenariosDiscover how China's humanoid robots, featuring 'Co-evolution of Big and Small Brains,' are revolutionizing global manufacturing. Learn about Embodied Tian Gong 3.0's ISO compliance and overseas deployment at Boao Forum 2026.Chen Wei (Automation Lead Engineer)
 Mar 30, 2026China Railway Industrial Secures Patent for Embodied Robotics in Material Handling, Boosting High-Precision Delivery Capabilities for Overseas Infrastructure and Manufacturing ProjectsChina Railway Industrial's new patent for embodied robotics in material handling boosts high-precision delivery for global infrastructure & manufacturing. Discover how this innovation enhances logistics accuracy in automotive, rail transit & EPC projects.Chen Wei (Automation Lead Engineer)
 Oct 21, 2026China’s Industrial Robot Exports Near RMB 10 Billion in First Nine Months of 2026China’s industrial robot exports neared RMB 10 billion in January–September 2026, with value rising faster than volume. Explore the data and what it could mean for suppliers.Chen Wei (Automation Lead Engineer)
 Oct 21, 2026Low-Latency Industrial Data Processing: Pricing and Key Cost DriversExplore industrial data latency price drivers, from edge hardware to integration and support. Learn how to compare quotes, verify performance, and avoid unnecessary costs.TSV Data Lab
 Oct 20, 2026KUKA Launches iiQKA.AI Vision to Simplify Industrial Image ProcessingKUKA iiQKA.AI Vision simplifies industrial image processing with controller-based 2D and 3D vision. Explore drag-and-drop setup for vision-guided automation.TSV Data Lab
 Oct 20, 2026Smart Industrial Edge Devices: Key Criteria for Legacy PLC IntegrationChoose smart industrial edge devices for legacy PLC integration. Discover key criteria for compatibility, data quality, security, and reliable collection without disrupting control.TSV Data Lab
 Oct 19, 2026Choosing a Radar Sensor by Application: Range, Resolution, and Field of ViewSimplify radar sensor application based product selection. Compare range, resolution, and field of view to avoid blind spots and choose with confidence. Explore the guide.TSV Data Lab
 Oct 18, 2026Comparing Material Options for Procurement: Specs, Costs, and Supply RisksExplore procurement oriented technical content on material options, specs, costs, and supply risks. Compare alternatives to cut hidden expenses and make confident sourcing decisions.Dr. Marcus Vance
 Oct 17, 20265-Axis CNC Positioning Accuracy: How to Interpret ISO 230-2 Test ResultsAssess 5 axis CNC machining positioning accuracy with ISO 230-2. Learn to interpret repeatability, reversal error, and test conditions to compare suppliers and make confident acceptance decisions.Dr. Marcus Vance
 Oct 16, 2026Choosing a Rugged Edge AI Box Supplier: Thermal Tests and Lifecycle SupportChoose a rugged edge AI box supplier with proven thermal performance and reliable lifecycle support. Discover the tests and commitments to verify before you buy.TSV Data Lab
 Oct 15, 2026R&D Cost Reduction Services: How to Evaluate Fees, Savings, and ROIEvaluate R&D cost reduction services with confidence. Compare fees, verify savings, and calculate ROI without compromising performance. Discover how to choose a provider that delivers real value.Chen Wei (Automation Lead Engineer)
 Oct 21, 2026How Should You Balance Cobot Payload Against Reach?Explore cobot payload versus reach to choose the right robot. Learn how tooling, load limits, workspace, and cycle time affect performance—and avoid costly selection mistakes.Chen Wei (Automation Lead Engineer)
 Oct 20, 2026How Do You Measure Industrial IoT Gateway Latency Under Load?Measure industrial IoT gateway latency under load with reliable timestamps, realistic traffic, and tail-latency analysis. Discover how to expose bottlenecks and choose the right gateway.TSV Data Lab
 Oct 19, 2026How Do You Verify That Precision Machined Parts Meet Tolerances?Master precision machining tolerance verification with the right tools, datum setups, and acceptance rules. Learn how to validate parts confidently and reduce costly inspection errors.Dr. Marcus Vance
 Oct 18, 2026What Should an AS9100 Machining Supplier Checklist Include?Build an AS9100 machining supplier checklist that verifies capability, traceability, inspection, and outsourced processes. Discover what to check before approving your next aerospace supplier.Dr. Marcus Vance
 Oct 17, 2026How Should You Interpret Industrial Robot Repeatability Specs?Decode industrial robot repeatability specifications, understand ISO 9283 test conditions, and avoid costly selection mistakes. Learn how to verify performance for your process.Chen Wei (Automation Lead Engineer)
 Oct 16, 2026How Can You Fairly Compare MTBF Across Industrial Servo Motors?Make a fair industrial servo motor MTBF comparison with matched operating profiles, failure criteria, and confidence bounds. Discover how to assess reliability beyond advertised numbers.Chen Wei (Automation Lead Engineer)
 Oct 15, 2026How Should You Compare TechStat Vanguard 5-Axis CNC Tolerances?TechStat Vanguard 5-axis CNC tolerance comparison: learn how to verify part accuracy, assess inspection evidence, and choose suppliers that reliably meet your drawing requirements.Dr. Marcus Vance
 Oct 14, 2026Drone Frame Composites: Carbon Fiber vs. Fiberglass for Weight and StiffnessExplore drone structural materials composites: compare carbon fiber and fiberglass for weight, stiffness, cost, and antenna compatibility. Find the right material for your drone frame.Elena Rostova (UAV Systems Researcher)























